| Lesson 2 | What is a view? |
| Objective | Understand what an SQL View is. |
What is a View in SQL?
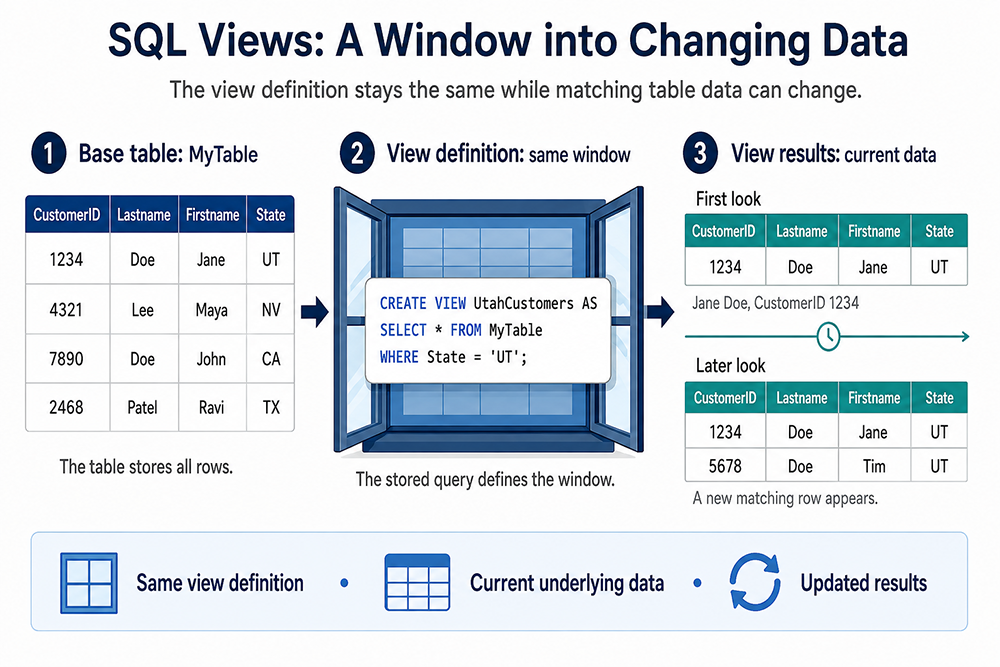
Think of a view as a window into your data. A window always gives you the same relative perspective on what's behind it, the same framing, the same angle, but what you actually see through that window changes as whatever is on the other side changes. A view works the same way: it's a stored query you can call on by name, and it always reflects whatever the underlying tables currently contain.
This isn't just a loose metaphor to memorize and move past. Every genuinely surprising thing a view does, showing different data on different days without anyone touching the view's definition, hiding columns nobody asked it to hide, staying valid even as the schema underneath it shifts slightly, traces back to this one idea: a view is a frame, not a photograph. Keeping that distinction in mind makes the rest of this lesson, and this whole module, much easier to reason about.
This isn't just a loose metaphor to memorize and move past. Every genuinely surprising thing a view does, showing different data on different days without anyone touching the view's definition, hiding columns nobody asked it to hide, staying valid even as the schema underneath it shifts slightly, traces back to this one idea: a view is a frame, not a photograph. Keeping that distinction in mind makes the rest of this lesson, and this whole module, much easier to reason about.
Why Views Exist
The people who design a database schema, and the people who write applications against it, generally need full knowledge of that schema, including direct access to the base tables. Most other users don't, and for good reason: letting end users query base tables directly is a security and stability risk. A view gives those users their own restricted window into the database, one that hides the details of the overall schema and prevents direct access to tables they shouldn't be touching at all.
A concrete example makes this less abstract. Suppose an employees table stores everything HR needs, name, department, hire date, and salary, all in one place. A payroll clerk needs to look up names and departments constantly, but has no business seeing salary figures. Rather than trusting every application and every ad hoc query to remember not to select the salary column, a view removes the possibility entirely:
This same principle extends naturally to rows, not just columns. A regional sales view might expose every column a manager needs, but filter to only the rows for that manager's own region, using the same WHERE clause technique shown next with the utah_customers example. Column restriction and row restriction are really the same tool, a SELECT list and a WHERE clause, applied with security in mind rather than just convenience in mind.
A concrete example makes this less abstract. Suppose an employees table stores everything HR needs, name, department, hire date, and salary, all in one place. A payroll clerk needs to look up names and departments constantly, but has no business seeing salary figures. Rather than trusting every application and every ad hoc query to remember not to select the salary column, a view removes the possibility entirely:
CREATE VIEW employee_directory AS
SELECT employee_id, first_name, last_name, department
FROM employees;This same principle extends naturally to rows, not just columns. A regional sales view might expose every column a manager needs, but filter to only the rows for that manager's own region, using the same WHERE clause technique shown next with the utah_customers example. Column restriction and row restriction are really the same tool, a SELECT list and a WHERE clause, applied with security in mind rather than just convenience in mind.
A View Starts as a SELECT Statement
Every view begins life as an ordinary SELECT statement, with every capability a SELECT normally has: filtering, joining, calculating, aliasing. The difference is that a view is a query the engine remembers, one you can refer to afterward as if it were a table in its own right.
Suppose CustomerTable has these columns:
A request to see only the customers based in Utah is a plain SELECT:
Suppose CustomerTable has these columns:
| CustomerID | Lastname | Firstname | State |
SELECT * FROM CustomerTable
WHERE State = 'UT';CREATE VIEW utah_customers AS
SELECT * FROM CustomerTable
WHERE State = 'UT';SELECT * FROM utah_customers;
Every time utah_customers gets queried, the underlying SELECT runs again against CustomerTable's current contents. Query it today and you might see one set of Utah customers; query it again next month, after new customers have signed up and others have moved away, and you'll see a different set of rows, through the exact same window.
To see this concretely, suppose querying utah_customers today returns:
The same window idea scales well past a single filtered table. A view can just as easily be built on a join across several tables, or on a query that computes totals and averages with GROUP BY, and the result still behaves exactly like the simple example above: a name you can query, always reflecting current data, regardless of how much logic sits behind that name. The mechanics of building views like that come later in this module; what matters here is that the underlying principle, a stored query rather than stored data, doesn't change no matter how complex the query gets.
To see this concretely, suppose querying utah_customers today returns:
CustomerID  Lastname   Firstname  State
1204        Chen       Wei        UT
1311        Okafor     Adaeze     UT
A new customer signs up in Salt Lake City next week, and an existing one updates their address to Nevada. Query utah_customers again, with no change whatsoever to the view's own definition, and the result reflects both changes automatically:
CustomerID  Lastname   Firstname  State
1204        Chen       Wei        UT
1487        Whitfield  Marcus     UT
Okafor dropped out of the result because their State no longer matches 'UT'; Whitfield appeared because theirs newly does. Nobody edited utah_customers between these two queries. The view didn't change at all; the data behind the window did, and the window simply kept doing what it always does, showing whatever currently matches its condition.
The same window idea scales well past a single filtered table. A view can just as easily be built on a join across several tables, or on a query that computes totals and averages with GROUP BY, and the result still behaves exactly like the simple example above: a name you can query, always reflecting current data, regardless of how much logic sits behind that name. The mechanics of building views like that come later in this module; what matters here is that the underlying principle, a stored query rather than stored data, doesn't change no matter how complex the query gets.
The filtering, calculating, and aliasing capabilities mentioned earlier are worth seeing together, not just naming. Suppose CustomerTable also has a LoyaltyPoints column, and the goal is a view that shows each customer's full name combined into one field, with their loyalty points converted into a rounded dollar-equivalent value:
CREATE VIEW customer_rewards AS
SELECT CustomerID,
       Firstname || ' ' || Lastname AS FullName,
       ROUND(LoyaltyPoints * 0.01, 2) AS RewardsValue
FROM CustomerTable;Views Go by Different Names
Not every product calls this concept a "view." In Microsoft Access specifically, the equivalent concept is simply called a query: queries can be saved, and a saved query can itself be the target of a SELECT in another query, the same layering a view provides elsewhere. SQL Server, MySQL, and PostgreSQL all use "view" directly, with CREATE VIEW syntax that reads almost identically to Oracle's for a simple case like the ones in this lesson; the differences between engines tend to show up in the more specialized clauses, not in this basic shape. Depending on which engine you're working with, you may also hear this concept called a stored query, a saved query, or a virtual table. The underlying idea, a named, reusable query that behaves like a table, stays consistent across products even when the terminology doesn't.
A Few Characteristics Worth Knowing Early
A handful of view characteristics are worth having in mind from the start, even before getting into the fuller syntax:
- Creating a view requires a specific privilege. You need the CREATE VIEW system privilege to create a view in your own schema, or CREATE ANY VIEW to create one in someone else's. More surprisingly, the privileges needed on the underlying base tables, to select, insert, update, or delete from them, have to be granted to the view's owner directly. A privilege inherited through a role doesn't count for this purpose, which catches people off guard the first time a view creation fails despite the owner apparently having full access to the base tables through their assigned role. A DBA might grant SELECT ANY TABLE through a role, watch that user query every table in the schema without issue, and then be genuinely confused when CREATE VIEW on one of those same tables fails with an insufficient-privileges error. The role grants querying; it doesn't satisfy the direct-grant requirement CREATE VIEW specifically checks for.
- OR REPLACE preserves what's already granted. Redefining a view with CREATE OR REPLACE VIEW, rather than dropping and recreating it from scratch, means any object privileges already granted on that view stay in place. Drop and recreate the same view instead, and every one of those grants has to be reissued by hand. Concretely: if twelve different users have been individually granted SELECT on employee_directory, updating that view's definition with CREATE OR REPLACE VIEW leaves every one of those twelve grants untouched. Dropping the view first and recreating it wipes all twelve out, silently, with no error to flag that anyone lost access; the next complaint from a user who can no longer query the view is usually how that gets noticed.
- A view has no data to protect on its own. Since a view is just a stored query, there's nothing about the view itself that's ever out of sync with its base tables; there's no separate copy of data that could drift. Whatever inconsistency might exist lives in the base tables, not in the view sitting on top of them.
What a View Does Not Do
A few misconceptions are worth heading off directly, since they follow naturally from the window metaphor if it's taken too literally.
A view is not a copy of data, and querying one doesn't inherently make anything faster. The underlying query still runs, still touches the base tables, and still costs whatever that query costs to execute; a view is a convenience for the person writing SQL, not a performance feature by itself. Materialized views, which do store a physical copy and refresh it on a schedule, are the exception, and they're covered on their own terms elsewhere in this course.
A view also doesn't enforce security beyond what its own column and row restrictions provide. Building employee_directory without a salary column keeps salary out of reach through that specific view, but it does nothing to stop someone with direct access to the underlying employees table from simply querying that table instead. A view is one layer of a security strategy, controlling what a given grant exposes, not a replacement for controlling access to the base tables themselves.
A view also doesn't guarantee a particular row order just because its defining query happens to include an ORDER BY. This is the same principle already established for GROUP BY and DISTINCT earlier in this course: an ORDER BY inside a view's definition can influence how the view's own query executes, but nothing forces a query against the view itself to preserve that order once other clauses, filters, or joins get layered on top by whoever is actually querying it. Treat a view the same way as any other query when order genuinely matters: add an explicit ORDER BY at the point where the final result is being read, rather than trusting that a view's internal ordering will survive intact.
Oracle also supports several more specialized kinds of views beyond the plain relational view covered in this course. Editioning views isolate an application from schema changes during upgrades, letting old and new versions of an application run against different column sets of the same underlying table simultaneously. Object views are built on user-defined types, where each row behaves as an instance of that type rather than a plain row of scalar columns. JSON collection views map JSON documents onto relational data, presenting rows of a table as a single JSON-type column. Each of these serves a genuinely different purpose than the plain view covered here, and none of them is needed to understand the material in the rest of this module; they're mentioned so that the plain view doesn't get mistaken for the only shape a view can take.
A view is not a copy of data, and querying one doesn't inherently make anything faster. The underlying query still runs, still touches the base tables, and still costs whatever that query costs to execute; a view is a convenience for the person writing SQL, not a performance feature by itself. Materialized views, which do store a physical copy and refresh it on a schedule, are the exception, and they're covered on their own terms elsewhere in this course.
A view also doesn't enforce security beyond what its own column and row restrictions provide. Building employee_directory without a salary column keeps salary out of reach through that specific view, but it does nothing to stop someone with direct access to the underlying employees table from simply querying that table instead. A view is one layer of a security strategy, controlling what a given grant exposes, not a replacement for controlling access to the base tables themselves.
A view also doesn't guarantee a particular row order just because its defining query happens to include an ORDER BY. This is the same principle already established for GROUP BY and DISTINCT earlier in this course: an ORDER BY inside a view's definition can influence how the view's own query executes, but nothing forces a query against the view itself to preserve that order once other clauses, filters, or joins get layered on top by whoever is actually querying it. Treat a view the same way as any other query when order genuinely matters: add an explicit ORDER BY at the point where the final result is being read, rather than trusting that a view's internal ordering will survive intact.
Oracle also supports several more specialized kinds of views beyond the plain relational view covered in this course. Editioning views isolate an application from schema changes during upgrades, letting old and new versions of an application run against different column sets of the same underlying table simultaneously. Object views are built on user-defined types, where each row behaves as an instance of that type rather than a plain row of scalar columns. JSON collection views map JSON documents onto relational data, presenting rows of a table as a single JSON-type column. Each of these serves a genuinely different purpose than the plain view covered here, and none of them is needed to understand the material in the rest of this module; they're mentioned so that the plain view doesn't get mistaken for the only shape a view can take.
Looking Ahead
A view is, at its core, nothing more exotic than a named, reusable SELECT statement that always reflects current data. That simplicity is exactly what makes it powerful: the same window metaphor that describes a basic single-table view like utah_customers scales up to views built on complex joins, aggregations, and calculations, which is where this module goes next.A few points from this lesson worth carrying forward:
- A view is a stored query, not stored data; it always reflects the current contents of its base tables, with no separate copy to go stale.
- Views exist primarily to hide schema complexity and restrict access, letting a user query a purpose-built window rather than the full base table underneath it.
- Creating a view requires a direct grant on the base tables, not just a role-based one, a detail that trips people up the first time they hit it.
- CREATE OR REPLACE VIEW preserves existing grants on a view; dropping and recreating it does not.
- A view isn't a performance feature, doesn't enforce security beyond its own column and row restrictions, and doesn't guarantee row order on its own, the same caveats that apply to ordinary queries apply here too.
- The plain relational view covered in this lesson is one member of a larger family that includes editioning views, object views, and JSON collection views, each suited to a different specialized purpose.