Learn about database writer and archive functions.
DBW and ARCn: A Closer Look
The previous lesson introduced all six of an instance's background processes, including DBW and ARCn. Rather than repeat those definitions here, this lesson takes a closer, more practical look at just these two, since they are the pair most directly responsible for getting your data and your recovery history safely onto disk. If you need a refresher on what DBW and ARCn fundamentally are before diving into how they behave under real conditions, the previous lesson covers that ground. Here, we will lean on two updated diagrams and focus on what "keeping up" versus "falling behind" actually looks like for each process.
Database Writer in Practice
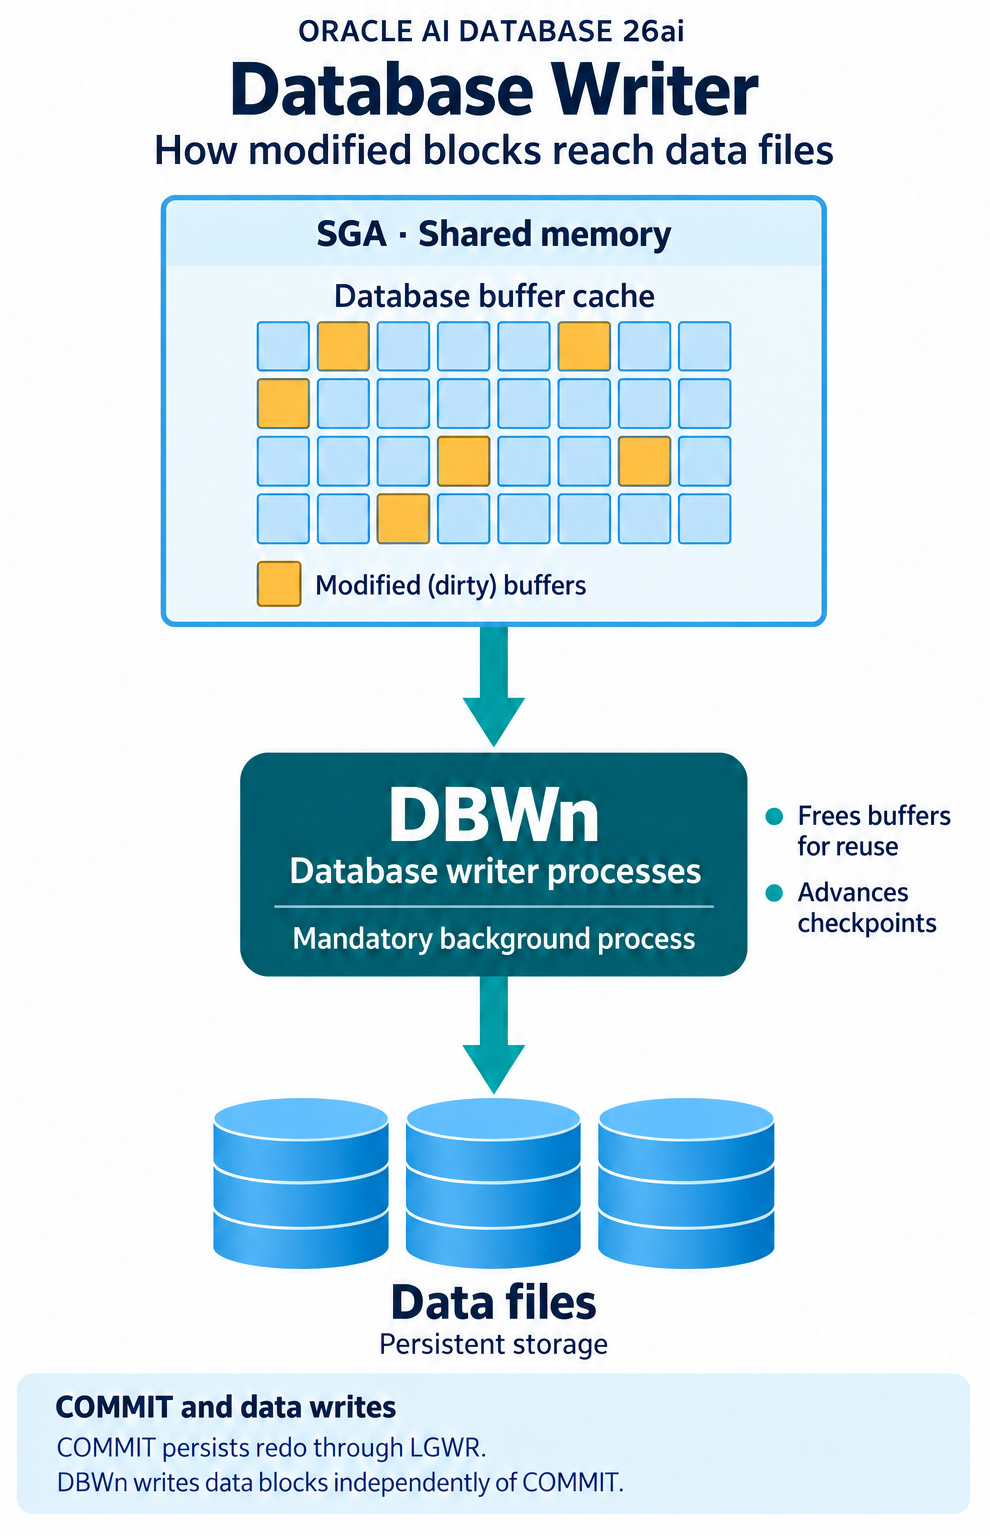
DBW writes modified, or dirty, data blocks from the database buffer cache out to the data files. It finds candidates for writing by scanning the buffer cache's least-recently-used list, which tracks a hot end of frequently accessed buffers and a cold end of buffers that haven't been touched in a while; it's the buffer cache itself that maintains this LRU structure, and DBW is simply the process that acts on it. Commit does not trigger a DBW write. A transaction becomes durable the moment LGWR flushes its redo to the online redo logs, and the actual dirty data block for that transaction may sit in the buffer cache for a while afterward, written out later when DBW gets around to it.
Database writer
On a system with meaningful write volume and enough CPU capacity to benefit, you can configure more than one writer via DB_WRITER_PROCESSES, which is where the familiar DBW0, DBW1, and so on naming comes from. This is a general capability across current Oracle platforms, not something limited to a particular operating system the way it once was in much older releases. What actually matters in practice is recognizing when DBW is falling behind rather than fixating on a specific process count. Oracle names this condition directly as the free buffer waits event: a server process couldn't find a free buffer to use and had to post DBW to go make room by writing out dirty ones. The usual causes are a slow I/O system, DBW waiting on some other resource like a latch, a buffer cache so small that DBW spends most of its time just cleaning out space for server processes, or, less intuitively, a buffer cache so large that a single DBW process can't free buffers fast enough to keep up with demand across it. If you see this wait event frequently, checking V$FILESTAT for where the writes are concentrated and the host's I/O statistics for write latency is the natural first step; if the cache itself looks undersized, V$DB_CACHE_ADVICE can tell you whether a larger cache would actually help before you go resize anything.
There is a more direct lever worth knowing about, since it connects straight back to this course's subject: the FAST_START_MTTR_TARGET parameter lets you specify, in seconds, roughly how long you're willing to let crash recovery take. Oracle uses that target to decide how aggressively DBW should write dirty buffers to disk, since the more dirty buffers accumulate, the more redo SMON has to replay to recover them after a crash. Set the target aggressively low and DBW works harder continuously to keep the recovery window short; set it higher and DBW can batch its writes more efficiently at the cost of a longer recovery if the instance does crash. That is a genuine tradeoff you get to make as a DBA, and it is a good example of how "background process behavior" and "recovery planning," the two halves of this module's subject, are really the same conversation.
Archiver in Practice
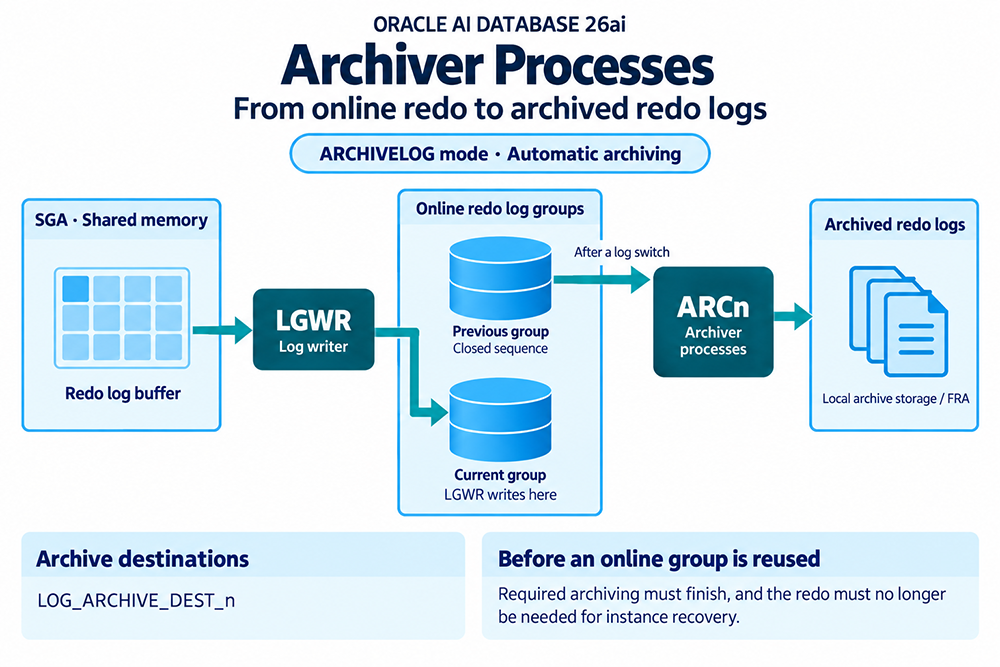
ARCn's job is narrower but arguably more consequential for this course specifically: once the database is running in ARCHIVELOG mode with automatic archiving enabled, ARCn copies each filled online redo log group to the archive destination as soon as LGWR switches away from it. This is not optional behavior once ARCHIVELOG mode is on; it is what makes the whole mode functional. LGWR will not reuse or overwrite a redo log group until ARCn has successfully archived it, full stop. That single rule is why archiving falling behind is a serious operational problem rather than a minor inconvenience: if ARCn can't keep pace, LGWR eventually runs out of redo log groups it's allowed to reuse, and the database stalls on the next log switch. DBAs commonly call this condition the database going "archiver stuck," and it is exactly the failure mode you want to catch through monitoring long before it happens rather than discover when your application stops responding.
Archive process
The archive destination itself is set with the LOG_ARCHIVE_DEST_n parameter (you'll see the older, unnumbered LOG_ARCHIVE_DEST in a lot of legacy material and even some older Oracle releases, but the numbered form is what supports multiple simultaneous destinations, which most real environments want). That parameter, like the rest of an instance's configuration, lives in either the server parameter file (SPFILE) or the older text initialization file (PFILE, historically named init.ora). It's worth being clear that PFILE is still fully supported today, not deprecated; it's simply less convenient for ongoing administration than SPFILE, since SPFILE lets ALTER SYSTEM persist a change directly without you manually editing a file. For a closer look at how these two mechanisms actually get managed day to day, see Additional Database Parameters.
This is also a good point to connect ARCn's job to where this course is headed. Archived redo logs are what make media recovery possible at all: restoring a damaged or lost data file from backup and rolling it forward past the point where your backup left off. They enable point-in-time recovery, letting you rewind the database to a specific moment before an unwanted change. And they are exactly what gets shipped to a standby database in a Data Guard configuration to keep it synchronized with the primary. None of those capabilities, which this course will spend real time on later, work without ARCn quietly doing its job in the background right now.
How They Interact Under Load
DBW and ARCn come under pressure in slightly different ways, and Oracle actually names two distinct wait events for the moment things go wrong: log file switch (archiving needed) and log file switch (checkpoint incomplete). Both describe the same underlying symptom: LGWR cannot switch into the next online redo log file, so every commit request on the system stalls waiting for that switch to complete. Knowing which of the two you're looking at tells you which process to go investigate.
A log file switch (archiving needed) wait means ARCn is the bottleneck. The usual causes are the archive destination running out of free space, ARCn not being able to read the redo logs fast enough because of contention with LGWR, or ARCn not being able to write fast enough because of contention on the destination or simply not enough archiver processes running; the default is two ARCn processes, and increasing that count is a reasonable next step once you've ruled out slow disks or a full destination. If you're shipping archived logs to a remote standby database, network delays or a write that never completes because of a transport error can produce the same symptom.
A log file switch (checkpoint incomplete) wait, by contrast, points at DBW. It shows up when your system generates redo fast enough to cycle all the way through your online redo log groups before DBW has finished writing out the buffers protected by the oldest one, at which point Oracle cannot safely reuse that log yet. The fix here is usually either checking whether DBW itself is slow (an overloaded or under-provisioned I/O system) or, just as often, increasing the size or number of your redo log groups so DBW simply has more time between cycles to catch up.
That second point matters enough to call out on its own: redo log file size affects both processes' behavior, not just LGWR's. Undersized redo logs force more frequent checkpoints, which pushes DBW harder, and they also force more frequent log switches, which pushes ARCn harder. Larger, well-sized redo log files generally improve the performance of both. A commonly used rule of thumb is to size your redo logs so that a switch happens at most once every twenty minutes or so under normal load; if you want a data-driven answer instead of a rule of thumb, the OPTIMAL_LOGFILE_SIZE column of V$INSTANCE_RECOVERY gives you Oracle's own sizing recommendation based on your current FAST_START_MTTR_TARGET setting.
If you want a single early-warning signal that ties both processes together, the V$SYSSTAT statistic redo log space requests is worth watching: it counts how many times a server process had to wait for space in the online redo log itself, not the redo log buffer. A rising count there is a strong hint that it's time to look at checkpoint tuning, DBW, or archiver activity, specifically, not at the redo log buffer size, which won't help this particular symptom no matter how large you make it.
Physical layout can help avoid contention between LGWR and ARCn in the first place, rather than just diagnosing it after the fact. Since LGWR writes sequentially and ARCn reads the log group LGWR just finished with, putting redo log members and the archive destination on separate disks lets the two processes work concurrently without competing for the same I/O path. A common pattern with four redo log groups of two members each is to alternate members across disks (1a, 1b, 2a, 2b, and so on) so that while LGWR is writing to the current group, ARCn can simultaneously read the previous group and write it out to the archive destination without either process waiting on the other.
The next lesson discusses log writer functions.