Explain how Oracle's ARCHIVELOG mode supports continuous data protection and recovery.
Understanding ARCHIVELOG Mode in Oracle AI Database 26ai
Oracle's ARCHIVELOG mode is what turns redo from a crash-recovery buffer into a continuous change history. When a database operates in ARCHIVELOG mode, filled online redo log groups are copied, archived, to a safe location by the archiver process before those groups can be reused. That archive stream is the basis for point-in-time recovery, online backups, Data Guard, Flashback Database, and near-zero-loss cloud protection.
"Continuous data protection" doesn't mean a nightly snapshot by itself. It means the combination of a backup plus every archived redo record generated since that backup, an unbroken sequence covering every committed change.
Purpose of Archiving
Archiving is the process of copying a filled redo log group to disk, tape, or cloud storage once it's no longer needed for instance recovery. The archived copies, called archived redo logs, preserve every transaction since the last backup, which is what lets a DBA recover the database to a precise point in time or to a specific system change number (SCN) rather than only to the moment of the last backup.
How Recovery Actually Uses the Archives
A recovery in 26ai is still two phases. First, restore a physical backup, an RMAN backup set or image copy, of the affected data files and usually a control file. Second, recover by applying incremental backups and then archived (and current) redo to roll those files forward.
Because the archives exist, ARCHIVELOG mode supports recovery that NOARCHIVELOG mode simply cannot:
Complete media recovery: restoring to the last committed transaction after a disk failure.
Incomplete, or point-in-time, recovery: restoring to a chosen time, SCN, log sequence, or restore point.
Block media recovery: repairing a single corrupted data block, or set of blocks, rather than an entire data file. RMAN can only apply archived redo for this, so a missing archived log covering the corrupted blocks can stop the repair.
Without archives, you can only restore a consistent closed backup and lose everything after it, exactly the limitation covered in the last two lessons on NOARCHIVELOG mode.
Why This Works While the Database Stays Open
ARCHIVELOG mode is also the prerequisite for hot backups. ALTER TABLESPACE ... BEGIN BACKUP and its whole-database counterpart, ALTER DATABASE BEGIN BACKUP, along with RMAN's own open-database backups, are only allowed when media recovery is actually possible, meaning ARCHIVELOG mode is enabled. A data file backed up while users are actively changing it is fuzzy, inconsistent at any single instant, and archived redo is exactly what supplies the missing changes to make the restored file consistent again. That's how production systems back up continuously instead of taking an outage for a cold copy.
The same archive stream also feeds incremental RMAN strategies (a level 0 backup plus incrementals plus archives), image-copy roll-forward with RECOVER COPY, and Recovery Appliance or Autonomous Recovery Service real-time redo transport, which can keep the recovery point objective under a second by shipping redo as it's generated rather than only after a log switch. Every one of those still assumes the source database is in ARCHIVELOG mode in the first place.
Features That Depend on This Same Stream
Several important 26ai recovery features are gated on ARCHIVELOG mode specifically:
Flashback Database: you can only enable flashback logging if the database is in ARCHIVELOG mode with a Fast Recovery Area configured. Flashback logs let you jump backward quickly, and archived redo still covers the gap if you flash back and then need to recover forward again. 26ai lets you place flashback logs outside the Fast Recovery Area now, but the underlying ARCHIVELOG requirement hasn't changed.
Data Guard: redo transport and apply are, fundamentally, the archived and online redo stream being sent to a standby database.
PDB and tablespace point-in-time recovery: both need archives covering the entire window you want to rewind through.
Guaranteed restore points used alongside Flashback also require ARCHIVELOG mode.
Flashback Query and Flashback Time Travel are a useful contrast here: they use undo data and flashback history tables, not archived redo, so they complement ARCHIVELOG mode rather than depending on it directly. They're not a substitute for it during an actual media failure, since they were never built to reconstruct a lost data file in the first place.
The NOLOGGING Gap, and Why FORCE LOGGING Closes It
ARCHIVELOG mode protects every change that actually generates redo, but not every operation does. A table or index created with CREATE TABLE AS SELECT or a bulk load can be marked NOLOGGING, which tells the database not to generate redo log records for that operation at all, usually done deliberately for speed on a one-time bulk load. Here's the part worth knowing: you cannot recover an object created this way, even if the database is running in ARCHIVELOG mode. If you mix normally-logged and NOLOGGING objects and then need media recovery, the NOLOGGING objects come back marked logically corrupt, not just missing recent changes, actually corrupt, and any attempt to read them afterward fails until you either restore them from a separate backup or recreate them.
FORCE LOGGING, enabled at the database or tablespace level, closes this gap by overriding NOLOGGING requests and generating redo regardless of what the operation asked for. That's exactly why earlier lessons in this course keep pairing "ARCHIVELOG mode" with "FORCE LOGGING" rather than treating ARCHIVELOG mode as sufficient protection on its own: without it, a single well-intentioned NOLOGGING bulk load can quietly create a hole in your otherwise continuous protection.
Monitoring the Archive Stream
It's worth actually checking that archiving is keeping up rather than assuming it is. V$ARCHIVED_LOG reports every archived log the database knows about:
SELECT sequence#, first_time, next_time, status
FROM v$archived_log
ORDER BY sequence#;
Watching this alongside ARCHIVE LOG LIST gives you both sides of the picture: whether the database currently believes it's in ARCHIVELOG mode, and whether the archives it's supposed to be producing are actually landing where they should, with no unexplained gaps in the sequence numbers.
Advantages of ARCHIVELOG Mode
Backups can be performed while the database remains online and accessible.
Supports complete recovery after disk failure or data corruption.
Enables point-in-time recovery by applying archived logs to data files.
Allows restoration to a specific SCN, or to just before a user error occurred.
None of this is free, though. ARCHIVELOG mode introduces real administrative tasks: DBAs need to allocate sufficient storage for archived log files, archived logs need to be backed up regularly, and the number of redo log groups may need to increase so that LGWR has somewhere to write while the archiver process catches up, rather than stalling.
Example Scenario
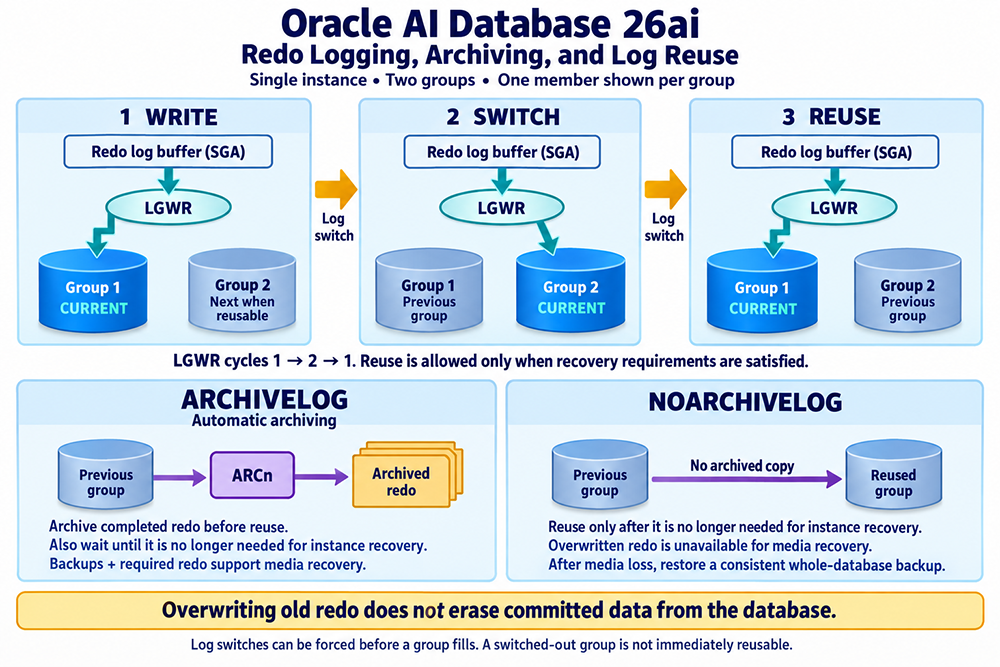
Consider a database configured with two redo log groups. When the current group fills, LGWR performs a log switch and begins writing to the next group. With ARCHIVELOG mode enabled, the archiver process copies the contents of the group that just filled to an archived log file before it becomes eligible for reuse. When the new current group fills in turn, another switch occurs and that group gets archived too. Each archived log is retained sequentially, building a continuous record of transactional activity that can be replayed during recovery.
The figure below illustrates this flow from memory to disk, showing how log switching and archiving work together to protect data while the redo logs themselves keep getting reused.
Oracle Redo and Archive Logging Process
Figure 1:Oracle AI Database 26ai: Redo Logging, Archiving, and Log Reuse
Single instance, two groups, one member shown per group.
Write. Redo log buffer (SGA) to LGWR. Group 1 is CURRENT; Group 2 is next when reusable.
Switch. Redo log buffer (SGA) to LGWR. Group 1 becomes the previous group; Group 2 is now CURRENT.
Reuse. Redo log buffer (SGA) to LGWR. Group 1 is CURRENT again; Group 2 is now the previous group.
LGWR cycles from Group 1 to Group 2 and back to Group 1. Reuse is allowed only once recovery requirements are satisfied.
In ARCHIVELOG mode (automatic archiving): the previous group is sent through ARCn to become an archived redo log. Oracle archives the completed redo before allowing reuse, and also waits until the group is no longer needed for instance recovery. Backups plus the required redo together support media recovery.
In NOARCHIVELOG mode: the previous group has no archived copy and simply becomes the reused group once it's no longer needed for instance recovery. Overwritten redo in this mode is unavailable for media recovery; after media loss, you restore a consistent whole-database backup instead.
Overwriting old redo does not erase committed data from the database itself. Log switches can also be forced before a group fills, and a switched-out group is not immediately reusable either way.
Operational Modes Compared
Feature
ARCHIVELOG Mode
NOARCHIVELOG Mode
Backup while online
Supported
Not supported
Point-in-time recovery
Available using archived logs
Not possible beyond the last full backup
Redo log reuse
After archiving completes
Overwritten immediately once no longer needed for recovery
Storage requirement
Requires additional space for archived logs
Minimal space, but limited recovery
How 26ai Operationalizes the Archive Stream
A typical production layout looks like this: multiplex the online redo logs, archive to more than one destination using LOG_ARCHIVE_DEST_n, often one local Fast Recovery Area destination plus a remote or cloud destination, and let RMAN back up archived logs on a short cycle, deleting them only once they're both backed up and obsolete under your retention policy. Where near-zero data loss actually matters, you can also ship redo in real time to Recovery Appliance or Autonomous Recovery Service.
The Fast Recovery Area is the usual local landing zone for archives, flashback logs, and backups together. Letting it fill up without an alternate archive destination configured can hang the database outright, since a redo log group can't be reused until it's been archived somewhere.
Best Practices for ARCHIVELOG Management
Place archived logs on a separate disk from the online redo logs to avoid I/O contention between LGWR and the archiver process.
Schedule regular backups of archived logs to off-site or cloud storage.
Monitor archive destination space, and configure multiple archive log destinations for redundancy.
Use RMAN to automate archived log deletion, only after they've actually been backed up.
A Practical Recovery Picture
After losing a data file on a 26ai CDB running in ARCHIVELOG mode, a typical RMAN recovery looks like:
RESTORE DATAFILE n;
RECOVER DATAFILE n;
ALTER DATABASE DATAFILE n ONLINE;
RECOVER DATAFILE here applies incremental backups, then archived redo, then whatever current redo is still needed, all in one step. After a logical mistake instead of a media failure, you can recover the PDB or the whole database UNTIL TIME or UNTIL SCN and open with RESETLOGS, because the archives contain the history needed to stop exactly where you want to.
ARCHIVELOG mode doesn't make backups by itself. What it does is make every later backup recoverable to a later point. Continuous protection in 26ai is that combination: physical backups for the base image, and the archived redo stream for every committed change that happened afterward. By implementing ARCHIVELOG mode, Oracle ensures committed transactions are never lost just because a disk or data file was damaged, and that's the backbone of the media recovery strategy the rest of this course builds on.
The next lesson explains how to enable ARCHIVELOG mode and verify that the archiving process is actually operating correctly.