| Lesson 6 | Querying Nested Tables |
| Objective | Choose and query Oracle 26ai nested tables using SQL collection expressions. |
Query Oracle 26ai Nested Tables with TABLE and Collection SQL
A nested table is a collection whose elements have one declared datatype. It can contain scalar values or structured objects, such as sale details. In SQL, a parent table can hold a nested-table column; collection expressions then let you query its elements as rows. This is useful when an application receives a collection value but a report needs individual products, quantities or amounts.
Separate three concepts: a collection type defines the element datatype, a persisted collection uses a storage table, and a PL/SQL collection variable holds values during program execution. Creating the type alone does not allocate a parent table or insert any elements. A relational parent can contain a collection column; an object-table parent is not required.
No maximum element count is declared for a nested-table type. That differs from a VARRAY's declared limit, but does not mean unlimited resources. A PL/SQL nested table starts dense when constructed and can become sparse after selected deletions. Persisted collection order is not guaranteed, and its transient indexes are not permanent element identifiers. Store a business key or explicit sequence value when the application needs one.
Use nested-table queries when filtering, joining or aggregating collection elements expresses the requirement directly. VARRAYs also support SQL unnesting, so the choice is not simply whether SQL can read the elements. Consider element updates, variable membership, storage and the application's data relationships. For independently managed child entities, ordinary relational child tables may provide a clearer model.
Define an element type, collection type and parent table
The three diagrams retain the PETSTORE sales model. They distinguish a typed reference from a scalar identifier and include the storage clause needed by the parent table. PRODUCT_TYPE and CUSTOMER_TYPE must exist before the displayed DDL. REF values designate stored row objects; these declarations neither create those targets nor enforce their continued existence.
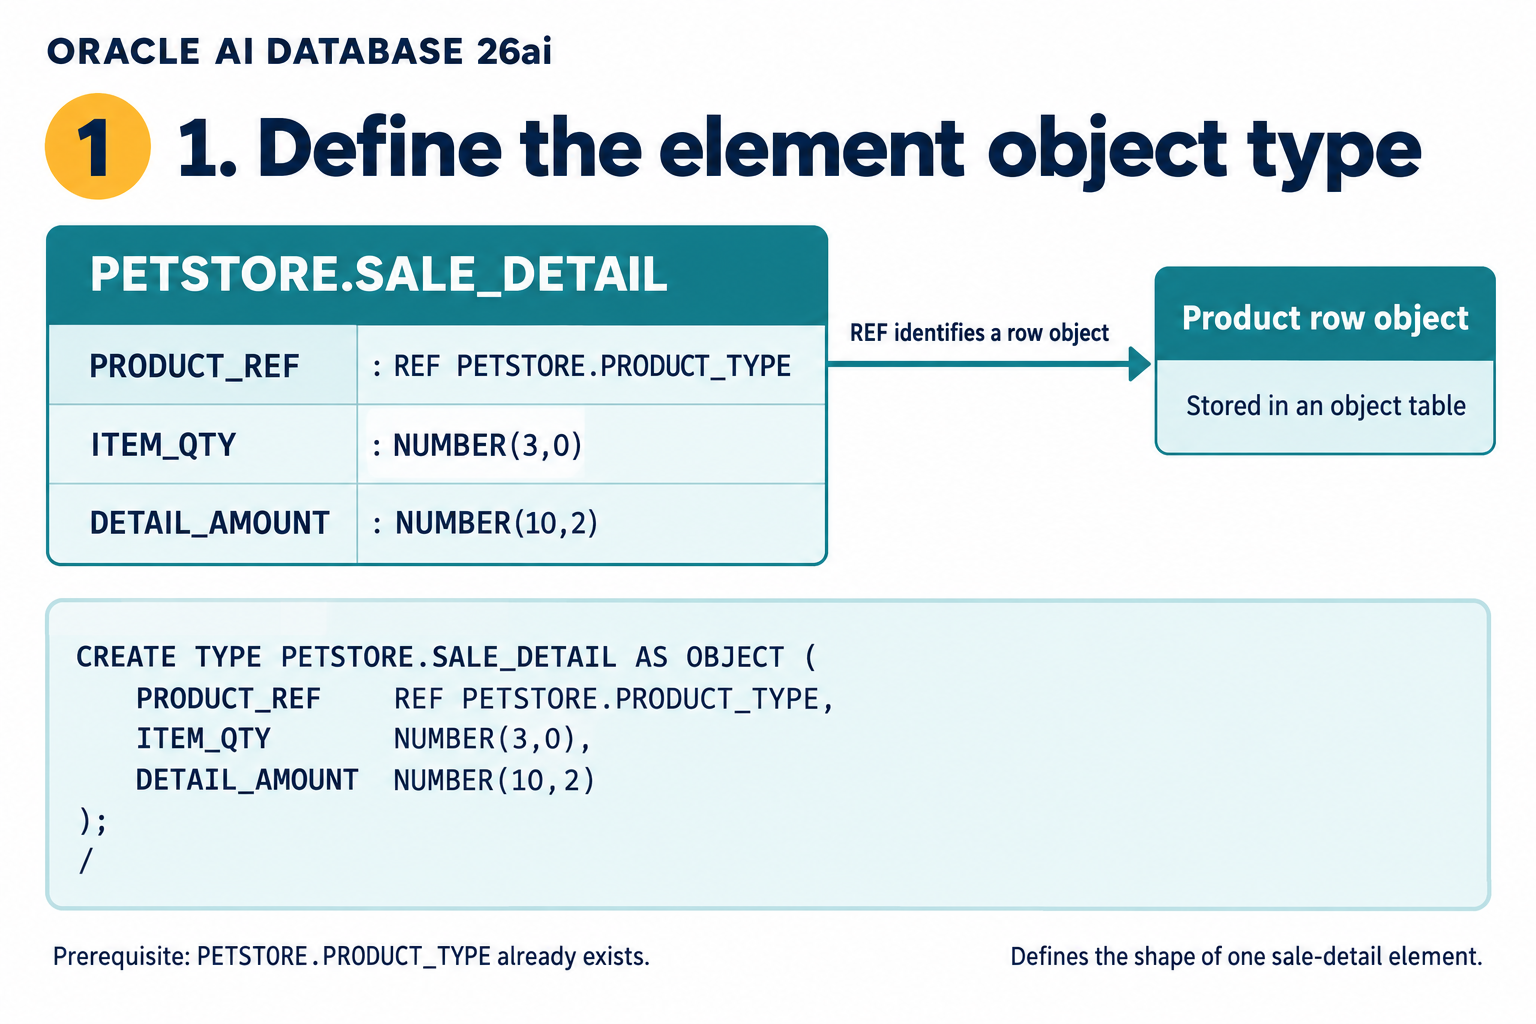
1) Define the SALE_DETAIL element object type. PRODUCT_REF names a typed reference rather than a scalar product identifier. ITEM_QTY uses a valid identifier, and commas separate the attributes.
CREATE TYPE PETSTORE.SALE_DETAIL AS OBJECT (
  PRODUCT_REF    REF PETSTORE.PRODUCT_TYPE,
  ITEM_QTY       NUMBER(3,0),
  DETAIL_AMOUNT  NUMBER(10,2)
);
/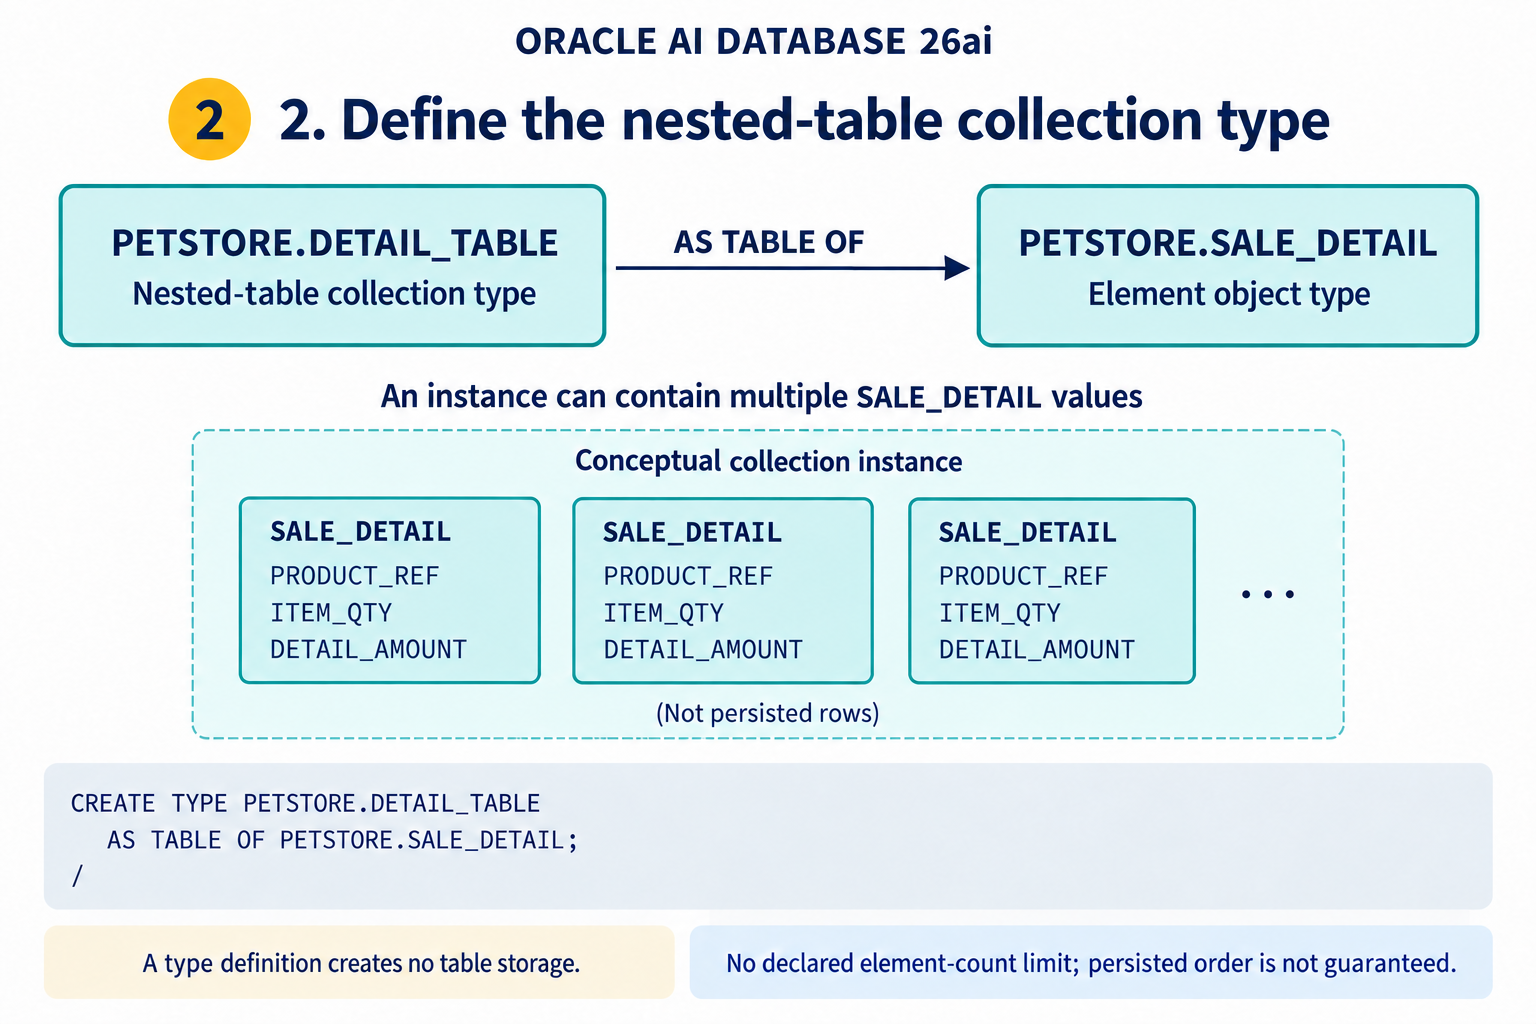
2) Define the nested-table collection type DETAIL_TABLE. Each element has type SALE_DETAIL. Creating this type does not create a persistent table. No maximum element count is declared, and persisted element order is not guaranteed.
CREATE TYPE PETSTORE.DETAIL_TABLE
AS TABLE OF PETSTORE.SALE_DETAIL;
/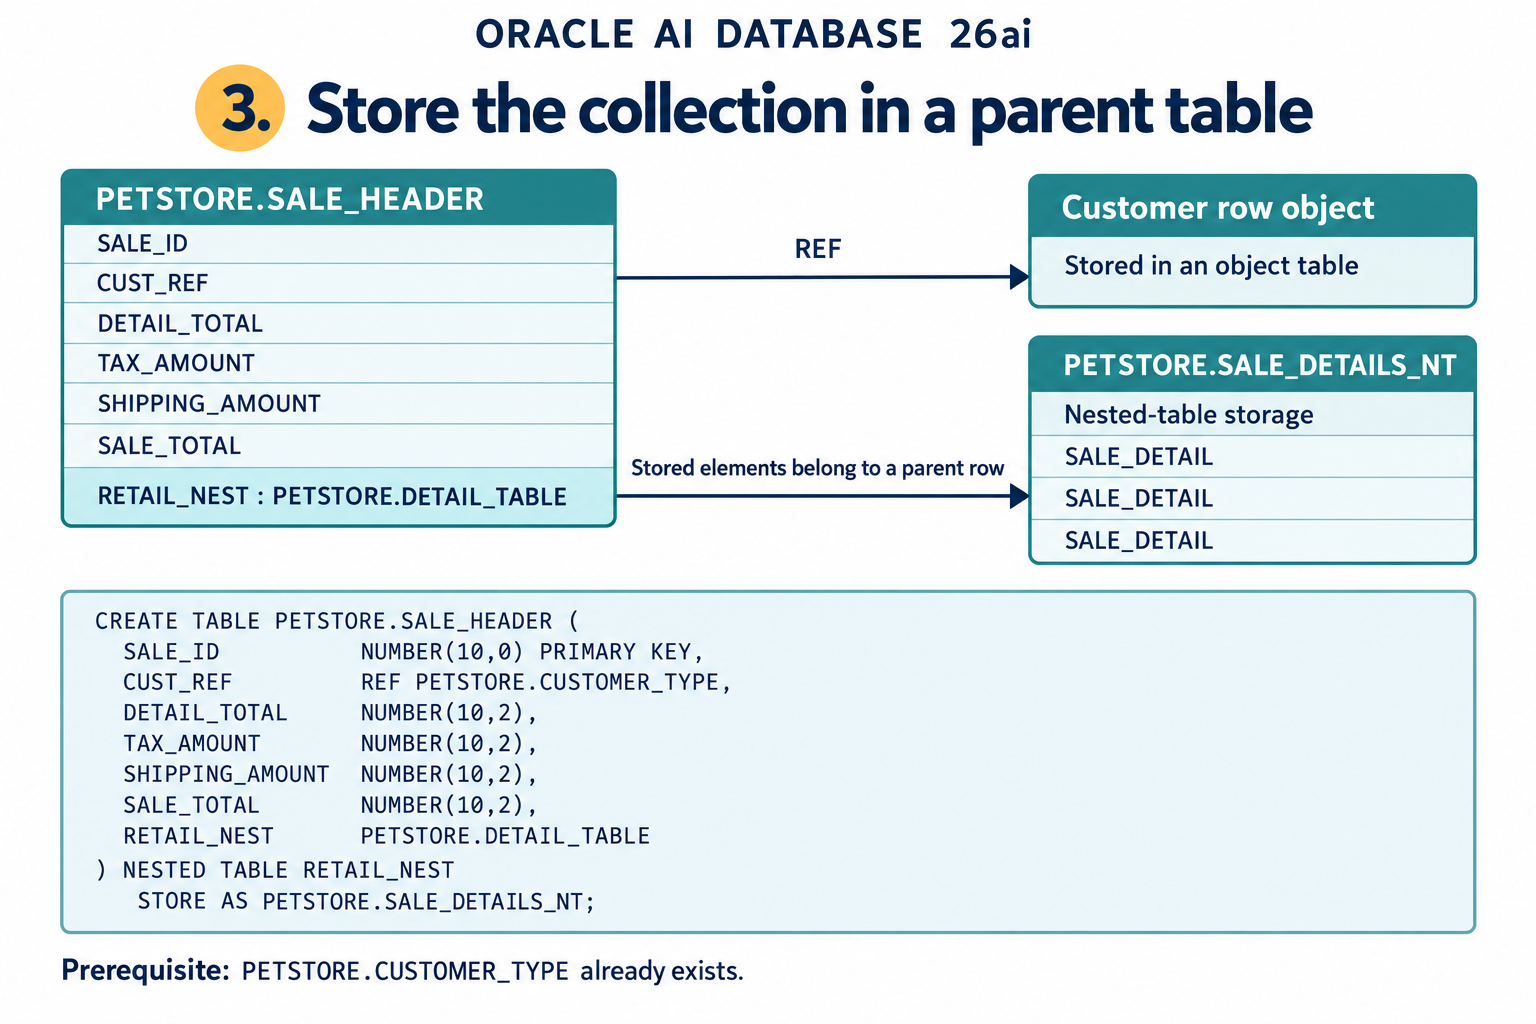
3) Create the relational parent table with a nested-table column. NESTED TABLE RETAIL_NEST STORE AS specifies the separate storage table for the collection elements. Oracle associates each stored element with its parent row. SALE_ID is the parent table's primary key; the stored total columns require application logic if they must agree with the line amounts.
CREATE TABLE PETSTORE.SALE_HEADER (
  SALE_ID          NUMBER(10,0) PRIMARY KEY,
  CUST_REF         REF PETSTORE.CUSTOMER_TYPE,
  DETAIL_TOTAL     NUMBER(10,2),
  TAX_AMOUNT       NUMBER(10,2),
  SHIPPING_AMOUNT  NUMBER(10,2),
  SALE_TOTAL       NUMBER(10,2),
  RETAIL_NEST      PETSTORE.DETAIL_TABLE
) NESTED TABLE RETAIL_NEST
  STORE AS PETSTORE.SALE_DETAILS_NT;
A self-contained practice example
The following separate example uses scalar product identifiers so you can study collection queries without first creating product and customer object tables. Run it in a practice schema with unused names and the appropriate privileges and quota. The examples are documentation-reviewed illustrations; they were not executed against an Oracle database. The expected results below follow the supplied data.
CREATE TYPE lesson6_line_t AS OBJECT (
  product_id     NUMBER,
  item_qty       NUMBER,
  detail_amount  NUMBER(10,2)
);
/
CREATE TYPE lesson6_line_list_t AS TABLE OF lesson6_line_t;
/
CREATE TABLE lesson6_sales (
  sale_id  NUMBER PRIMARY KEY,
  details  lesson6_line_list_t
) NESTED TABLE details STORE AS lesson6_sales_details_nt;

INSERT INTO lesson6_sales VALUES (
  1001, lesson6_line_list_t(
    lesson6_line_t(501, 2, 40.00),
    lesson6_line_t(502, 1, 15.00)
  )
);
INSERT INTO lesson6_sales VALUES (1002, lesson6_line_list_t());
INSERT INTO lesson6_sales VALUES (1003, NULL);
COMMIT;
The slash submits each type definition in script-oriented clients such as SQL*Plus. It is a client command, not SQL to send through a driver. Sale 1001 has two detail objects, sale 1002 has an initialized empty collection, and sale 1003 has a null collection. Here detail_amount means a complete line amount, not a unit price. The declared type alone does not enforce quantity positivity or consistency with other totals.
The schema stores collection elements separately and associates them with their owning sale row. That implementation is different from a manually defined child table with its own declared sale_id foreign key. Use the parent collection interface in the examples rather than treating the storage table as an unrelated application table.
Return a collection or unnest its elements
Select the collection column when an application needs the entire typed value:
SELECT s.sale_id, s.details
FROM lesson6_sales s
ORDER BY s.sale_id;
This produces two result columns. The details column is a collection value, whose display depends on the client. It is not automatically a flat list of product columns, and it should not universally be described as a locator. If a report needs one row per detail, use a TABLE expression in the FROM clause:
SELECT s.sale_id, d.product_id, d.item_qty, d.detail_amount
FROM lesson6_sales s, TABLE(s.details) d
WHERE d.detail_amount >= 20
ORDER BY s.sale_id, d.product_id;
The parent alias s supplies the collection, and d names the unnested elements. Because each element is an object, its attributes are exposed as d.product_id and d.item_qty. The illustrative matching row is sale 1001, product 501, quantity 2, amount 40.00. This form returns matching elements, rather than a sale row with an embedded list.
TABLE distributes the collection elements into relational rows. It does not introduce a permanent ordinal or sort the results. ORDER BY makes the reporting order explicit. If two details have the same product identifier, add a suitable line identifier to the model when a unique ordering or individual line identity is required.
With a nested table of scalar values, the unnested value is named COLUMN_VALUE instead of exposing object attributes. You will see that form in the tag example below. Choose projections to match the declared element datatype, rather than copying attribute names from an unrelated example.
Find qualifying parents without multiplying them
Suppose the question is which sales contain product 501, rather than which individual details match. A correlated EXISTS returns each qualifying parent once:
SELECT s.sale_id
FROM lesson6_sales s
WHERE EXISTS (
  SELECT 1
  FROM TABLE(s.details) d
  WHERE d.product_id = 501
)
ORDER BY s.sale_id;
The illustrative result is sale 1001. Even if several details in that sale meet the predicate, EXISTS asks only whether a match exists. A direct unnesting query can repeat the sale_id for multiple matching elements. Select the query shape deliberately instead of applying DISTINCT automatically to hide duplicates.
You can also join unnested product_id values to an ordinary product table when one exists. That join would require an actual product table definition and a chosen key relationship. A scalar attribute named product_id does not create a foreign key automatically. Similarly, the PETSTORE diagrams' REF attributes need explicit integrity design if target existence matters.
Aggregate details and preserve empty parents
An ordinary unnesting query produces no element rows for an empty collection. To preserve the sale and report a zero total, use the collection outer-join form documented by Oracle:
SELECT s.sale_id,
       COUNT(d.product_id) AS product_rows,
       NVL(SUM(d.detail_amount), 0) AS detail_total
FROM lesson6_sales s, TABLE(s.details) (+) d
GROUP BY s.sale_id
ORDER BY s.sale_id;
This illustrates totals of 55.00, 0 and 0 for sales 1001, 1002 and 1003. COUNT(d.product_id) illustrates two populated product identifiers for the first sale and zero for the others. It is not a universal count of all elements if real details can have null product identifiers. COUNT(*) would count the null-extended parent row, so it would be misleading for this particular report.
The (+) belongs to the collection expression here. It tells Oracle to return a parent row with null element columns when the collection contributes no rows, including a null collection. This is a documented collection-query pattern, not a claim that every historical outer-join form should be preferred for ordinary joins.
Be careful with a later WHERE predicate on an element attribute: it can remove the null-extended rows and undo the intended parent preservation. Decide whether a predicate qualifies sales or limits the elements included in an aggregate. Those are different reporting requirements. Test populated, empty and null collections when revising the query.
Distinguish empty collections from null collections
SELECT s.sale_id
FROM lesson6_sales s
WHERE s.details IS EMPTY
ORDER BY s.sale_id;

SELECT s.sale_id
FROM lesson6_sales s
WHERE s.details IS NULL
ORDER BY s.sale_id;
The first query illustrates sale 1002, and the second sale 1003. An initialized empty collection exists and contains no elements; a null collection has no supplied collection value. IS EMPTY applied to a null collection produces an unknown result, which does not pass a WHERE filter. Do not use IS NOT EMPTY as a substitute for every null check.
A collection containing an element with null attributes is another case: it is not empty merely because those attributes contain no values. Likewise, SQL filters normally retain only true conditions, not unknown conditions. Make absent data semantics part of the application contract rather than interpreting every missing value as an empty list.
Use membership and multiset tests on comparable elements
Scalar tags make these operators easy to demonstrate without requiring object comparison methods. Create a separate schema-level collection type:
CREATE TYPE lesson6_tag_list_t AS TABLE OF VARCHAR2(30 CHAR);
/
SELECT 'matching' AS result
FROM dual
WHERE 'oracle' MEMBER OF lesson6_tag_list_t('oracle', 'sql');

SELECT 'covered' AS result
FROM dual
WHERE lesson6_tag_list_t('oracle', 'sql')
      SUBMULTISET OF lesson6_tag_list_t('sql', 'oracle', 'plsql');
The first query illustrates matching and the second covered. MEMBER OF tests element membership. SUBMULTISET OF tests whether the left collection is contained in the right with the necessary multiplicities. Two copies of a tag on the left require enough matching occurrences on the right. Neither expression means that collections have been deduplicated.
Element datatypes must support the required comparison. For object elements, inspect comparison rules and methods before assuming whole-object membership behaves like a simple identifier check. The earlier EXISTS query compares a scalar product attribute and avoids that ambiguity. Null values can also produce unknown comparison results, so include them in meaningful application tests.
Query a collection variable using a SQL type
The following PL/SQL block uses the schema-level lesson6_line_list_t already defined above. SQL can therefore recognize the element structure in TABLE(l_lines):
SET SERVEROUTPUT ON
DECLARE
  l_lines lesson6_line_list_t := lesson6_line_list_t(
    lesson6_line_t(502, 1, 15.00),
    lesson6_line_t(501, 2, 40.00)
  );
BEGIN
  FOR r IN (
    SELECT d.product_id, d.detail_amount
    FROM TABLE(l_lines) d
    ORDER BY d.product_id
  ) LOOP
    DBMS_OUTPUT.PUT_LINE(r.product_id || ': ' || r.detail_amount);
  END LOOP;
END;
/
The illustrative traversal visits product 501 before 502 because of ORDER BY, although the constructor listed 502 first. Client settings control DBMS_OUTPUT visibility and numeric formatting. This block neither inserts collection elements nor allocates a persisted storage table.
Do not generalize this example to every locally declared PL/SQL collection of records. SQL interoperability depends on where the type is declared, its element datatype and the operation. A schema-level SQL collection is the straightforward choice here. BULK COLLECT can populate collections from queries, but it does not remove those type-compatibility rules or justify fetching an arbitrarily large dataset into memory.
Build a collection result with COLLECT
SELECT s.sale_id,
       CAST(COLLECT(TO_CHAR(d.product_id))
            AS lesson6_tag_list_t) AS product_labels
FROM lesson6_sales s, TABLE(s.details) d
GROUP BY s.sale_id;
COLLECT aggregates the selected scalar expressions, and CAST supplies the named result collection type. Here the tags type is reused to hold product identifiers converted to text. Only the populated sale contributes rows to this inner unnesting example. The collection value contains labels for products 501 and 502, but the example does not promise an element order.
This is a query result, not CREATE TABLE and not a new persisted nested-table column. Aggregating existing relational child rows into a typed collection uses the same idea. Consider duplicate handling and null expressions explicitly when designing that interface. Avoid assuming that casting a value enforces the business meaning implied by a type's name.
Modify selected nested-table elements
Nested tables support SQL element operations. This optional continuation updates one product's line amount within sale 1001:
UPDATE TABLE (
  SELECT s.details FROM lesson6_sales s WHERE s.sale_id = 1001
) d
SET d.detail_amount = 45.00
WHERE d.product_id = 501;
The parent selector uses a primary key to identify one collection. The element predicate may still update multiple details if product_id repeats inside that collection. Use a line key when exactly one element must be targeted. After this illustrative change, rerunning the total query would show 60.00 for sale 1001. Choose COMMIT or ROLLBACK according to the owning transaction.
SQL changes to the nested collection do not automatically maintain separate stored totals in a sales header. Applications must specify the consistency rule and implement it appropriately. VARRAYs differ here: SQL does not support their piecewise element DML, even though TABLE can query them. Choose based on actual update requirements, not an unsupported blanket claim that one collection is always faster.
Advanced context: Oracle Any types
ANYTYPE describes a SQL type, ANYDATA combines a value with type information, and ANYDATASET describes a set of instances of one type. They support generic interfaces where the type is not fixed in advance. Ordinary nested-table queries do not require them: the named SQL type already supplies the element definition. These interfaces have their own construction and persistence restrictions and belong in an advanced design discussion.
Before choosing nested storage, compare it with a normalized child table and, for document requirements, the appropriate JSON facilities. Consider constraints, independent identities, query patterns and maintenance. No generic claim of better JSON indexing or lower storage overhead replaces measurement for a specific workload.
The next lesson develops practical SQL examples. Review the distinction between returning a complete collection, returning individual elements and selecting qualifying parents, then use the existing quiz to check the object-relational concepts.
Nested Table - Quiz
Oracle 26ai references: collection querying and DML, multiset conditions, COLLECT and Any types.