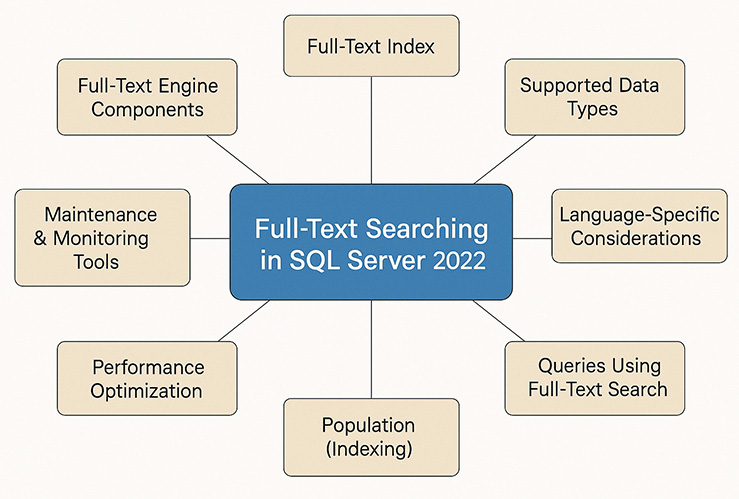
Describe the components you should consider when using full-text searching.
Considerations for Full-Text Searching
Full-text searching in SQL Server 2025 is not a single switch you turn on. It is a small collection of moving parts, a catalog, an index, a background engine, a set of query predicates, that all have to be set up correctly, in the right order, before CONTAINS or FREETEXT will return anything useful. This lesson walks through each of those components, what it is for, and the specific rules SQL Server enforces around it, so that when you build your first full-text index in the next lesson, none of the pieces are a surprise.
Full-Text Catalog
A full-text catalog is a logical container for one or more full-text indexes. Despite some older guidance to the contrary, a catalog is not optional, and a full-text index cannot be attached directly to a table with no catalog involved at all. A catalog has to exist first, created explicitly or already marked as the database's default, before CREATE FULLTEXT INDEX will succeed:
CREATE FULLTEXT CATALOG MyCatalog AS DEFAULT;
Marking a catalog AS DEFAULT means any later CREATE FULLTEXT INDEX statement that omits the ON catalog_name clause will use it automatically; otherwise, the catalog has to be named explicitly every time you create an index.
Full-Text Index
A full-text index is what actually enables full-text search on one or more columns of a table. Two requirements have to be satisfied before you can create one:
The table must have a unique, non-nullable, single-column index, usually the PRIMARY KEY.
Every column you index must be of a supported data type, covered in detail below.
CREATE FULLTEXT INDEX ON Documents(Content LANGUAGE 1033)
KEY INDEX PK_Documents_ID
ON MyCatalog;
Here, PK_Documents_ID is the table's existing unique key index, Content is the column being indexed, and 1033 is the language identifier for English, which tells SQL Server which word breaker and stemmer to apply.
Supported Data Types
Full-text indexes can only be created on columns that hold text or document content, not on ordinary numeric or relational data, because the full-text engine tokenizes and indexes words and phrases rather than comparing values. The valid data types are:
char, varchar: fixed-length and variable-length non-Unicode string data.
nchar, nvarchar: fixed-length and variable-length Unicode string data.
text, ntext (deprecated but still supported): variable-length non-Unicode data up to 2^31-1 bytes, and variable-length Unicode data up to 2^30-1 characters, respectively.
xml: stores XML data.
image (deprecated) and varbinary(max): variable-length binary data up to 2^31-1 bytes, used with a type column and document filters so the engine knows how to parse the stored document, typically .pdf or .docx files stored as blobs.
Numeric and date/time types, such as int, bigint, money, decimal, float, and datetime, are not allowed. Full-text indexing relies on word breakers, stemmers, stopword removal, and linguistic analysis to build an inverted index, and none of that makes sense against a numeric or binary value that has no linguistic structure to analyze.
Language-Specific Considerations
A language ID, such as 1033 for English, determines the linguistic rules used for word-breaking and stemming on a given column. SQL Server ships with word breakers and stemmers for many languages, so a column holding French product descriptions and a column holding English product descriptions can each be indexed with the correct linguistic rules applied to each one individually.
Full-Text Engine Components
Three pieces of the engine work together behind every full-text query:
Word Breakers and Stemmers: break text into individual tokens and reduce words to their base forms, so a search for "run" can also match "running" or "ran".
Noise Words (Stopwords): common words, such as "the" and "and", that are excluded from the index by default because they carry no search value.
Thesaurus Files: XML-based mappings for synonyms, used to broaden a match beyond the exact word typed.
Queries Using Full-Text Search
Once an index exists, four predicates and rowset functions are available to query it:
Predicate
Description
CONTAINS
Searches for precise matches and supports complex syntax with prefixes, wildcards, proximity terms, and logical operators.
FREETEXT
Searches for meaning or intent, using a thesaurus and linguistic analysis rather than a precise set of criteria you construct yourself.
CONTAINSTABLE / FREETEXTTABLE
Return ranked result sets, including a RANK column indicating relevance.
Example:
SELECT Title
FROM Documents
WHERE CONTAINS(Content, '("SQL Server*" AND "indexing")');
This query finds documents where the Content column contains a word beginning with "SQL Server" alongside the word "indexing", using CONTAINS's prefix-matching and logical AND syntax rather than a plain substring search.
Population (Indexing)
Population is the process of building and refreshing the full-text index itself. It can be triggered manually, or SQL Server can keep it current automatically based on change tracking:
AUTO: automatic change tracking. As rows change, SQL Server queues the change and propagates it to the index asynchronously, in the background, with no manual step required.
MANUAL: change tracking is recorded, but repopulation has to be triggered on demand, typically with ALTER FULLTEXT INDEX ... START UPDATE POPULATION.
FULL or INCREMENTAL population are the two ways a (re)population can be run, whether triggered manually or kicked off for the first time: a full population rebuilds the entire index, while an incremental population updates only what has changed since the last population, provided the table has a timestamp column to compare against.
Security Considerations
Two things matter for securing full-text search:
Users need SELECT permission on the columns being searched; full-text search does not bypass ordinary column-level permissions.
Full-text indexes are not stored as separate files alongside the database. Since SQL Server 2008, full-text catalogs and indexes have been fully integrated into the main database engine and its own storage mechanisms, so they are backed up, restored, and secured as part of the database itself, not as a separate directory that has to be managed on its own.
Performance Optimization
A few habits keep full-text search fast as the underlying data grows:
Use filters, such as a WHERE clause on other columns, to narrow the rows a full-text predicate has to evaluate.
Avoid reaching for FREETEXT out of habit; its semantic expansion makes it more resource-intensive than a targeted CONTAINS predicate when you already know the exact terms you are looking for.
Index only the columns that actually need to be searched, rather than every character column on the table.
Monitor index health using the catalog views sys.fulltext_catalogs and sys.fulltext_indexes, along with dynamic management views such as sys.dm_fts_index_population.
Maintenance and Monitoring Tools
A handful of tools let you check on a catalog or index directly:
Catalog status:FULLTEXTCATALOGPROPERTY('MyCatalog', 'PopulateStatus') reports whether a catalog is idle, populating, or paused.
Population status:sys.dm_fts_index_population exposes an active population's progress in more detail.
Forcing a rebuild:
ALTER FULLTEXT INDEX ON Documents START FULL POPULATION;
Components to consider when using full-text searching
Before You Begin
A few prerequisites have to be in place before any of the above will work at all:
The Full-Text and Semantic Extractions for Search feature has to be installed; it is an optional component presented during SQL Server setup and is not selected by default.
The SQL Server Full-Text Filter Daemon Launcher service has to be running. This is the modern service behind what much older versions of SQL Server called the Microsoft Search service; the name and architecture changed, but the underlying job, loading filters and word breakers outside the main database engine process, has stayed the same. Without the feature installed and this service running, both the full-text menu options in SQL Server Management Studio and any Transact-SQL statement that depends on full-text search will fail.
One Full-Text Index Per Table
Like a clustered relational index, a table can have only one full-text index. This is a hard design constraint, not a guideline: every column you want searchable has to be part of that single index, and there is no way to create separate full-text indexes over different sets of columns on the same table. All of the columns you intend to search have to be decided on together, at the time the index is created, rather than added piecemeal across several indexes later. Keep this in mind when planning a schema for full-text search. In the next lesson, you will see how to define a full-text index in practice.
The CREATE FULLTEXT INDEX Statement
CREATE FULLTEXT INDEX is the statement that creates a full-text index on a table or indexed view, enabling linguistic searches with CONTAINS, FREETEXT, CONTAINSTABLE, and FREETEXTTABLE, well beyond what LIKE can do on its own.
Syntax overview:
CREATE FULLTEXT INDEX ON table_name
(
    column_name1 [TYPE COLUMN type_column_name] [LANGUAGE language_term_id],
    column_name2 [LANGUAGE language_term_id],
    ...
)
KEY INDEX unique_index_name
[ON fulltext_catalog_name]
[WITH <fulltext_index_options>];
Clause
Description
ON table_name
The base table the full-text index is being created on.
(columns...)
The columns to index; only character-based and document-content data types are allowed, as covered above.
TYPE COLUMN
Required when the indexed column is varbinary(max) or image; names a column that tells SQL Server the document's file type, such as .pdf or .docx.
LANGUAGE
The language-specific word breaker and stemmer to use, such as 1033 for English.
KEY INDEX
Mandatory; the unique key index on the table, typically the primary key.
ON catalog_name
Optional; the full-text catalog to associate with the index. If omitted, the catalog already marked as the database's default is used.
WITH
Defines index properties such as change tracking and stoplist behavior.
Example:
CREATE FULLTEXT INDEX ON Articles
(
    Title LANGUAGE 1033,
    Body LANGUAGE 1033
)
KEY INDEX PK_Articles_ArticleID
ON MyFullTextCatalog
WITH CHANGE_TRACKING AUTO;
This creates a full-text index on the Title and Body columns of Articles, using English linguistic rules for both, in the MyFullTextCatalog catalog, with automatic change tracking.
Options in the WITH clause:
Option
Description
CHANGE_TRACKING { AUTO | MANUAL | OFF }
Determines how index updates are tracked. AUTO is the default and most common setting.
STOPLIST { SYSTEM | OFF | stoplist_name }
Controls which stopwords (noise words) are ignored during indexing.
Special cases:
TYPE COLUMN: used for varbinary(max) or image columns that store binary documents:
CREATE FULLTEXT INDEX ON Documents
(
    DocumentContent TYPE COLUMN DocumentType
)
KEY INDEX PK_Documents_DocumentID
ON DocCatalog;
Here, DocumentType holds a value such as .docx or .pdf, identifying the document format stored in DocumentContent.
Indexed view support: a full-text index can also be created on an indexed view, but the view must meet strict requirements, including being schema-bound with deterministic expressions.
Best practices:
Ensure the base table has a unique, single-column, NOT NULL index.
Use a dedicated full-text catalog for large datasets, to isolate I/O.
Choose the correct LANGUAGE for accurate linguistic processing.
In the next lesson, you will practice implementing full-text searching, putting the catalog, index, and query predicates covered in this lesson together into a working example.