| Lesson 9 | Aggregated data |
| Objective | Create queries to aggregate data. |
SQL Server Aggregated Data Queries
Aggregated Data Queries and SQL Data Selection
In this lesson, you will learn how to aggregate data in several common situations. Assume you are working against the following table:
| EmployeeID | DepartmentID | Salary |
| 101 | 1 | 50000 |
| 102 | 1 | 25000 |
| 103 | 2 | 60000 |
| 104 | 2 | 100000 |
| 105 | 2 | 125000 |
If you wanted to summarize all of the salaries in this table, you could use the following query:
SELECT SUM(Salary)
FROM Employees
WHERE clause:
SELECT SUM(Salary)
FROM Employees
WHERE DepartmentID = 1
The GROUP BY Clause
Now for a new clause:
GROUP BY[1]. A GROUP BY clause places query results into groups that you specify. If your query also specifies an aggregate function, GROUP BY performs that function within each group and returns a single value per group, rather than one value for the whole table. In SQL Server 2025, the basic form looks like this:
GROUP BY expression [, ...n]
ROLLUP, CUBE, and GROUPING SETS extend GROUP BY to produce subtotals and grand totals alongside the detail groups, covered in the diagram below.
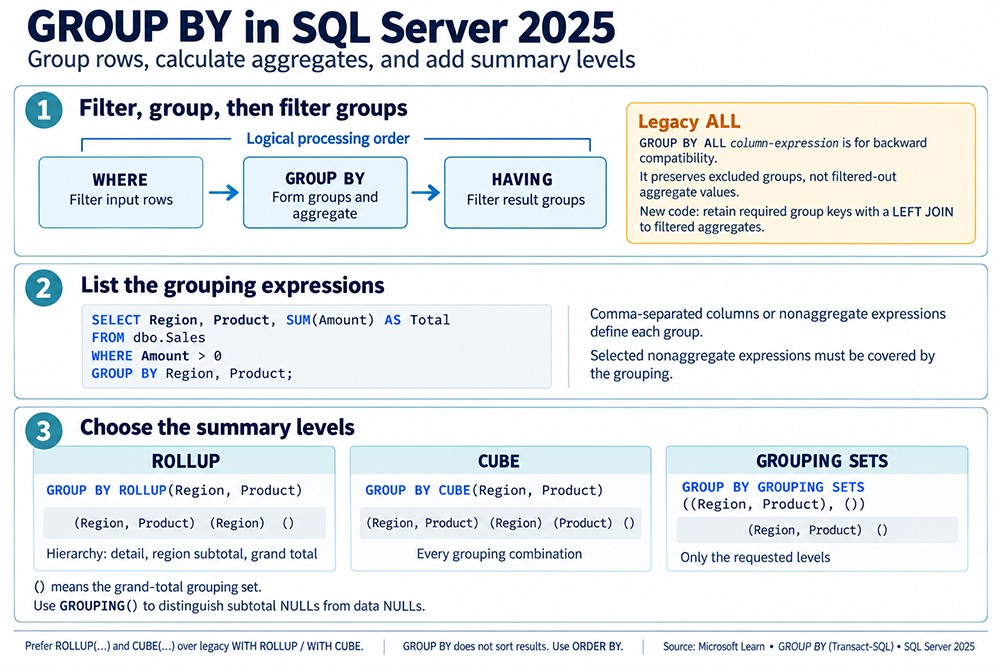
GROUP BY and HAVING Together
You will often want to find trends in your data that require the database server to summarize it a bit before you retrieve a result set.
When using
GROUP BY is one such mechanism: rather than looking at a list of employees and the departments they belong to, you might want a list of departments along with how many employees each one has.
When using
GROUP BY, you can also use HAVING, which filters grouped data the same way WHERE filters raw, ungrouped data. Here is a query that counts employees in each department and returns only the departments with more than one employee, using the Employee table already established in this lesson:
SELECT DepartmentID, COUNT(EmployeeID) AS NumEmployees
FROM Employees
GROUP BY DepartmentID
HAVING COUNT(EmployeeID) > 1;
| DepartmentID | NumEmployees |
|---|---|
| 1 | 2 |
| 2 | 3 |
Both departments have more than one employee, so both appear. If the threshold were raised to
HAVING COUNT(EmployeeID) > 2, only department 2 would qualify, since department 1 has only two employees.
The ORDER BY Clause
Normally, if you specify a
GROUP BY clause, you also specify an ORDER BY[2] clause after it, so the grouped data comes back in a predictable order. Generally, the GROUP BY and ORDER BY clauses reference the same columns.
Aggregate Query Example
Now a query that returns the
SUM of all employees' salaries, grouped by department. Because you are selecting a SUM rather than an actual column, it is a good idea to alias it so the result set's column name is understandable:
SELECT SUM(Salary) AS Salary
FROM Employees
GROUP BY DepartmentID
ORDER BY DepartmentID
| Salary |
| 75000 |
| 285000 |
From this result alone, you cannot tell which sum belongs to which department, since the query never asked for DepartmentID back. Rewriting the query to include it fixes that:
SELECT DepartmentID, SUM(Salary) AS Salary
FROM Employees
GROUP BY DepartmentID
ORDER BY DepartmentID
| DepartmentID | Salary |
|---|---|
| 1 | 75000 |
| 2 | 285000 |
In the next lesson, you will learn how to construct queries within queries, also known as subqueries.
Summary
A short recap before the next lesson:
GROUP BYplaces query results into groups you specify, and any aggregate function in the query is applied separately within each group.HAVINGfilters grouped results the wayWHEREfilters raw rows, applied after grouping and aggregation rather than before.ROLLUP,CUBE, andGROUPING SETSextend basic grouping to add subtotals and grand totals; in SQL Server 2025, these are preferred over the legacyWITH ROLLUPandWITH CUBEsyntax.- Selecting an aggregate without the column you grouped by produces a result you cannot interpret; always select the grouping column alongside the aggregate so each value in the result set can be traced back to the group it belongs to.
GROUP BYdoes not sort its results on its own; pair it withORDER BY, generally on the same columns, when the order of the grouped output matters.
Aggregate Data - Exercise
Click the exercise link below to practice creating aggregate queries.
Aggregate Data - Exercise
Aggregate Data - Exercise
[1] GROUP BY: specifies how a query's results should be broken into groups, based on the values in the columns listed after the
GROUP BY keywords.
[2] ORDER BY: the SQL keywords that specify the order in which a query's results are returned.