| Lesson 5 | Implementing full-text searching |
| Objective | Practice implementing full-text searching. |
Implementing Full-Text Searching
Once a full-text index exists on a table, you are ready to query it. This lesson covers why full-text search exists in the first place, how SQL Server actually builds and ranks a full-text index under the hood, and worked examples of the four Transact-SQL mechanisms used to query one.
Why Full-Text Search Exists
A traditional relational index, a B-tree, sorts column values from left to right. That makes a prefix search like
Full-text search solves this with a different data structure entirely. Instead of indexing whole rows by primary key, the engine breaks documents into normalized linguistic tokens and builds an inverted index, a structure that maps every unique word to the documents, and the positions within those documents, where it appears.
WHERE Title LIKE 'SQL%' fast, but a substring or multi-word search like WHERE Body LIKE '%index%' cannot use that sort order at all: SQL Server has no way to know where inside the column the match will start, so it falls back to scanning every row.
Full-text search solves this with a different data structure entirely. Instead of indexing whole rows by primary key, the engine breaks documents into normalized linguistic tokens and builds an inverted index, a structure that maps every unique word to the documents, and the positions within those documents, where it appears.
How a Full-Text Index Is Built
Building a full-text index happens in stages:
- Document filtering (text extraction): if the source data is a binary format, such as a PDF or DOCX stored in a
varbinary(max)column, a format-specific filter strips out formatting markup and extracts the raw text. - Tokenization (word breaking): a language-specific word breaker splits the character stream into individual tokens, based on whitespace, punctuation, and language-specific rules. This matters most for languages like Japanese or Chinese that do not use spaces between words.
- Stopword removal: high-frequency, low-meaning words, such as "the", "and", "of", and "is", are stripped out using a stoplist, to keep the index compact and avoid false-positive matches.
- Linguistic normalization and stemming: a stemmer reduces words to a root or inflectional base form, for example mapping "running", "ran", and "runs" to "run", and case is normalized.
- Inverted index construction: the resulting tokens are written into the inverted index itself, a sorted structure where each term points to the documents, columns, and word positions where it occurs.
How SQL Server Ranks Results
Unlike an ordinary
WHERE predicate, which is a simple boolean match, full-text queries compute a relevance rank for each matching row. Several factors go into that rank:
- How often a term appears in a given row's text: a row mentioning "deadlock" a dozen times is treated as more relevant than one mentioning it once.
- How rare a term is across the whole table being searched: a specific technical term that appears in only a handful of rows carries more weight than a common word that appears everywhere.
- Proximity: using the word-position data stored in the index, SQL Server favors matches where the searched terms appear close together or in the exact phrase order requested.
RANK value. Its own documentation describes rank only in general terms, how well a row matches the selection criteria, and states that the raw rank numbers are not meaningful on their own and can differ between runs of the same query. Treat rank as a relative ordering tool, useful for sorting matches from most to least relevant, rather than as a precisely documented statistical score.
SQL Server 2025 Architecture
Full-text search is built into the relational engine itself, while the riskier work of parsing arbitrary binary documents is isolated into a separate process:
| Component | Where It Runs | Role |
| Full-Text Engine | Inside the database engine (sqlservr.exe) | Compiles full-text queries, manages index population, and computes relevance ranking. |
Full-Text Filter Daemon Launcher (fdhost.exe, service MSSQLFDLauncher) | External, sandboxed process | Runs document filters, word breakers, and stemmers outside the core engine, so a corrupted or malicious document cannot crash SQL Server itself. |
| Full-Text Catalog | Logical container, stored inside the database's own filegroups | Groups one or more full-text indexes together for administration. |
| Full-Text Index Fragments | Internal structures, inspectable via sys.fulltext_index_fragments | Stores the inverted index in batches ("fragments"); a catalog with many queryable fragments can be merged with ALTER FULLTEXT CATALOG catalog_name REORGANIZE. |
| Unique Key Index | On the base table | A single-column, non-nullable unique index, typically the primary key, that the inverted index uses to map matches back to relational rows. |
A Richer Index Example
The previous lesson built a full-text index on a single plain-text column. A full-text index can also span several columns of different kinds at once, including a binary document column:
-- 1. Create a full-text catalog
CREATE FULLTEXT CATALOG TechnicalDocsCatalog AS DEFAULT;
GO

-- 2. Create the full-text index
-- Requires the name of an existing single-column unique or primary key index
CREATE FULLTEXT INDEX ON Production.Documentation
(
    Title LANGUAGE 1033,
    ArticleBody LANGUAGE 1033 STATISTICAL_SEMANTICS,
    BinaryAttachment TYPE COLUMN FileExtension LANGUAGE 1033
)
KEY INDEX PK_Documentation_DocID
ON TechnicalDocsCatalog
WITH (
    CHANGE_TRACKING = AUTO,
    STOPLIST = SYSTEM
);
GO
STATISTICAL_SEMANTICS on ArticleBody additionally builds the key-phrase and document-similarity indexes used by Semantic Search; it requires that feature to be configured separately and is not needed for ordinary CONTAINS or FREETEXT queries. BinaryAttachment TYPE COLUMN FileExtension tells SQL Server to parse the binary document using the file type recorded in FileExtension, the same pattern covered for varbinary(max) columns in the previous lesson.
The Four Query Functions
SQL Server provides two predicate functions, used in a
WHERE clause, and two table-valued functions, used in a FROM clause, that additionally return a [KEY] column (the matched row's unique key) and a [RANK] column (relevance, scaled 0 to 1000).
| Function | Used In | Purpose |
CONTAINS | WHERE | Precise matches: exact words or phrases, prefix wildcards, boolean logic (AND, OR, AND NOT), and proximity (NEAR). |
FREETEXT | WHERE | Looser, natural-language matching: the engine tokenizes the search string, removes stopwords, generates inflectional forms, and matches on meaning rather than exact wording. |
CONTAINSTABLE | FROM | Same matching rules as CONTAINS, returned as a rowset with [KEY] and [RANK] columns so results can be joined and ordered by relevance. |
FREETEXTTABLE | FROM | Same matching rules as FREETEXT, also returned as a rowset with [KEY] and [RANK] columns. |
Exact, prefix, and proximity search with CONTAINSTABLE:
SELECT
    d.DocID,
    d.Title,
    ft.[RANK] AS RelevanceScore
FROM Production.Documentation AS d
INNER JOIN CONTAINSTABLE(
    Production.Documentation,
    (Title, ArticleBody),
    -- Inflectional forms of "optimize" within 5 words of a prefix match on "index*"
    'NEAR((FORMSOF(INFLECTIONAL, optimize), "index*"), 5)'
) AS ft
    ON d.DocID = ft.[KEY]
ORDER BY ft.[RANK] DESC;
SELECT
    d.DocID,
    d.Title,
    ft.[RANK] AS RelevanceScore
FROM Production.Documentation AS d
INNER JOIN FREETEXTTABLE(
    Production.Documentation,
    ArticleBody,
    'how to troubleshoot transaction log bloat and lock escalation'
) AS ft
    ON d.DocID = ft.[KEY]
WHERE ft.[RANK] >= 100
ORDER BY ft.[RANK] DESC;
Four Patterns Against an Employees Table
The following runnable examples apply all four functions to a single, concrete case: searching the
Notes column of a dbo.Employees table, with EmployeeID as the full-text unique key, assuming the full-text index has already been created and populated, as in the previous lesson.
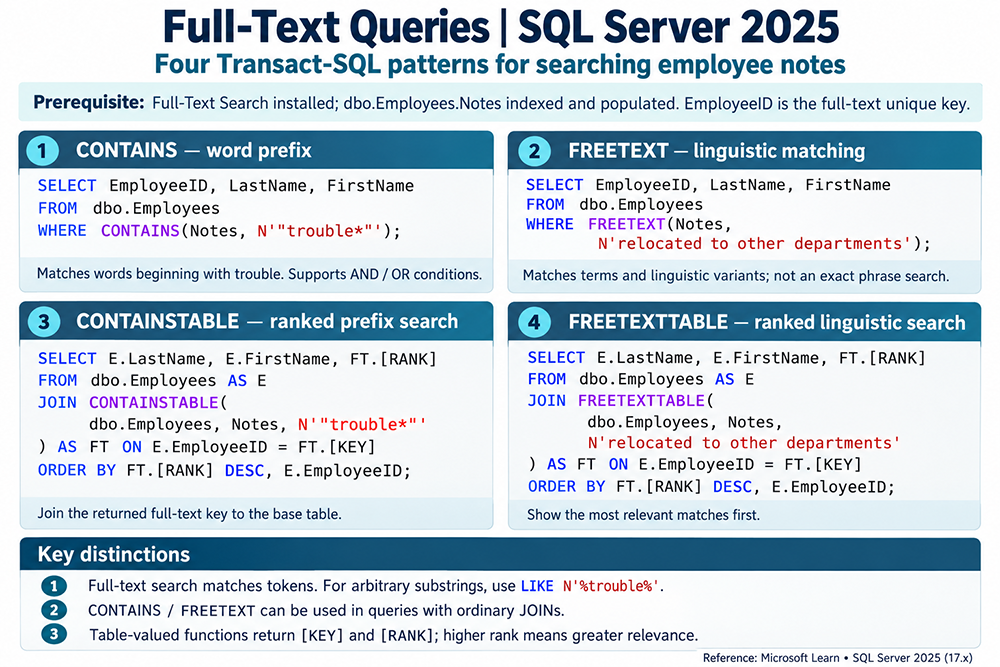
CONTAINS, word prefix:
SELECT EmployeeID, LastName, FirstName
FROM dbo.Employees
WHERE CONTAINS(Notes, N'"trouble*"');
AND/OR conditions, similar in spirit to a LIKE search but far more capable. Note the prefix term syntax: a trailing asterisk inside double quotes, not a leading and trailing asterisk as in a LIKE pattern; full-text search has no equivalent of a leading wildcard.
FREETEXT, linguistic matching:
SELECT EmployeeID, LastName, FirstName
FROM dbo.Employees
WHERE FREETEXT(Notes, N'relocated to other departments');
CONTAINSTABLE, ranked prefix search:
SELECT E.LastName, E.FirstName, FT.[RANK]
FROM dbo.Employees AS E
JOIN CONTAINSTABLE(
    dbo.Employees, Notes, N'"trouble*"'
) AS FT ON E.EmployeeID = FT.[KEY]
ORDER BY FT.[RANK] DESC, E.EmployeeID;
FREETEXTTABLE, ranked linguistic search:
SELECT E.LastName, E.FirstName, FT.[RANK]
FROM dbo.Employees AS E
JOIN FREETEXTTABLE(
    dbo.Employees, Notes, N'relocated to other departments'
) AS FT ON E.EmployeeID = FT.[KEY]
ORDER BY FT.[RANK] DESC, E.EmployeeID;
A few distinctions worth keeping in mind:
- Full-text search matches whole tokens. For an arbitrary substring match, you still need
LIKE N'%trouble%'. CONTAINSandFREETEXTcan be used in ordinary queries with normal joins, since they are predicates, not table sources.- The table-valued functions,
CONTAINSTABLEandFREETEXTTABLE, return[KEY]and[RANK]; a higher rank means greater relevance.
Beyond Lexical Search: Pairing with Vector Search
SQL Server 2025 pairs classic lexical full-text search with native vector search, the
vector data type, VECTOR_DISTANCE(), VECTOR_SEARCH(), and DiskANN vector indexes, covered earlier in this module. The two approaches are complementary rather than competing:
- Lexical full-text search (
CONTAINSTABLE,FREETEXTTABLE) excels at exact part numbers, error codes, acronyms, and specific terminology, the cases where the exact word matters. - Vector search excels at conceptual similarity, finding related content even when two passages share no words in common.
RRF(), Reciprocal Rank Fusion, call; a hybrid query is built by running a full-text search and a vector search separately, then merging and re-ranking the two result sets yourself in T-SQL, typically with a FULL OUTER JOIN and a scoring formula based on each result's rank in its own result set. It is a pattern you assemble, not a feature you turn on.
Implement Full-Text Searching: Exercise
Click the exercise link below to practice creating a full-text query.
Implement FullText Searching - Exercise
Implement FullText Searching - Exercise
In the next lesson, we will review the information covered in this module.