| Lesson 2 | Partitioning explained |
| Objective | Describe table partitioning. |
Oracle Table Partitioning Explained
Oracle Database gives you access to information based on its logical structure, while the data itself is stored in physical structures. This mirrors the relationship between a tablespace and its data files: a tablespace is a logical concept, and the data within it is stored in one or more physical data files on disk.
Partitioned Tables
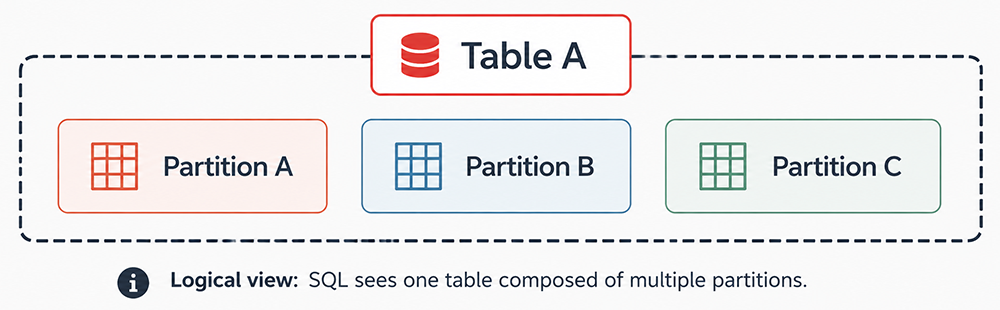
The concept of a partitioned table is analogous to that tablespace-to-data-file relationship. A tablespace can have one or more data files associated with it, and even though those data files are invisible to the end user, all database maintenance operations occur at the tablespace level. A partition works the same way at the table level: it is a section of a table, and the different partitions in a table are completely transparent to a user executing SQL against it. Unlike the tablespace and data file relationship, however, the DBA has direct control over how a table is partitioned. Oracle 23ai uses this structure to improve query performance and increase the manageability of large tables, particularly as data volumes grow well beyond what a single unpartitioned table can handle efficiently. The structure of a partitioned table is shown in the diagram below.
Oracle Partitioned Tables
| Object | Description |
|---|---|
| Table A | The table is a logical structure, visible to SQL statements as a single whole. |
| Partition A | Partition A contains an exclusive subset of the data in Table A. The data in Partition A is not repeated in other partitions. |
| Partition B | Partition B contains an exclusive subset of the data in Table A. The data in Partition B is not repeated in other partitions. |
| Partition C | Partition C contains an exclusive subset of the data in Table A. The data in Partition C is not repeated in other partitions. |
Why Partitioning Is Needed
Partitioning addresses the key challenges of supporting very large tables and indexes by decomposing them into smaller, more manageable pieces called partitions. SQL queries and DML statements do not need to be modified in any way to access partitioned tables; the partitioning is entirely transparent to the application layer. Once partitions are defined, however, DDL statements can target individual partitions rather than entire tables or indexes, which is what makes partitioning such an effective tool for simplifying the management of large database objects. Each partition of a table or index must share the same logical attributes as its siblings, such as column names, datatypes, and constraints, but each partition can carry its own physical attributes, including storage parameters and tablespace assignment. This lets a DBA, for example, place a rarely-queried historical partition on slower, cheaper storage while keeping an actively-written current partition on fast storage. Partitioning benefits many application types, particularly those managing large volumes of data. OLTP systems typically see the biggest gains in manageability and availability, since maintenance can be scoped to a single partition instead of an entire table. Data warehousing systems typically see gains in both performance and manageability, since large-scale queries can often be satisfied by scanning only a fraction of the total data.
Partitioning Offers These Advantages
- It enables data management operations, such as data loads, index creation and rebuilding, and backup and recovery, to run at the partition level rather than against the entire table. This significantly reduces the time these operations take, since a maintenance job on one partition does not have to touch the rest of the table.
- It improves query performance through partition pruning. In many cases, the optimizer can satisfy a query by accessing only the partitions that could possibly contain matching rows, rather than scanning the entire table. For queries with a predicate that aligns with the partition key, this can produce order-of-magnitude gains in performance.
- It significantly reduces the impact of scheduled downtime for maintenance. Partition independence lets you run concurrent maintenance operations on different partitions of the same table or index, and it lets ordinary SELECT and DML operations continue running against partitions that are unaffected by the maintenance in progress.
- It increases the availability of mission-critical databases, since dividing critical tables and indexes into partitions reduces maintenance windows, shortens recovery times, and limits the blast radius of a failure to the affected partition rather than the whole table.
- It supports parallel execution for queries, DML, and DDL against partitioned objects. Parallel execution against partitioned data is a key factor in scalability within Oracle Real Application Clusters (RAC) environments, where work against different partitions can be distributed across nodes.
Faster Data Access
Partitioning enables faster data access regardless of database size, whether a table holds gigabytes or terabytes of data. It can be implemented without requiring any modification to existing applications: a nonpartitioned table can be converted to a partitioned table without changing any of the SELECT or DML statements that access it, since partitioning is transparent at the SQL level. Partitioning remains a separately licensed option under Oracle Database Enterprise Edition in current Oracle releases, including Oracle 23ai. Licensing terms and available editions do change over time, so the exact current terminology should be verified against Oracle's published licensing documentation before this page is published.
Where This Is Headed
The next lesson looks at the specific strategies available for dividing a table into partitions: range partitioning, list partitioning, hash partitioning, and composite partitioning that combines two of these methods. Each strategy suits a different kind of data and access pattern, and choosing the right one is what turns the general advantages described here into a measurable improvement for a specific table.