| Lesson 2 | Identify structures required for recovery |
| Objective | Identify the persistent structures used in Oracle recovery and explain their roles in instance recovery and restoring damaged files. |
Identify Structures Required for Oracle Database Recovery
Restore and Recovery Are Different Operations
Oracle AI Database 26ai uses persistent datafiles, redo, undo, and control-file metadata to recover database contents. Which inputs are needed depends on the failure. A crashed instance with surviving files presents a different problem from a failed disk containing datafiles.
Restore means retrieving files from a backup. RMAN can restore backup sets and image copies; restoration is not limited to an operating-system COPY command. Recovery applies the changes needed to reach a consistent, usable database state. Depending on the operation, those changes can come from redo or incremental backups.
A restore is not always necessary before recovery. After an instance failure, Oracle normally recovers the existing datafiles using surviving online redo and undo. After media loss, backups may be needed to replace damaged files. Neither operation guarantees recovery to the last committed transaction unless the required recovery inputs are available.
The Core Recovery Structures
The following table distinguishes stored data, change records, log files, and metadata. A redo record is information inside a log, while a control file describes the database rather than containing its application rows.
| Structure | Role |
|---|---|
| Datafiles | Store persistent database blocks, including application data and undo. Restored datafiles may need changes applied before use. |
| Redo records | Describe block changes that Oracle can reconstruct. A record can contain multiple change vectors. |
| Online redo logs | Hold the current sequence of redo generated during database operation. |
| Archived redo logs | Preserve redo from online logs for later recovery when archiving is enabled. |
| Undo segments | Store information for reversing transaction changes, including uncommitted work encountered during recovery. |
| Control files and checkpoint metadata | Identify database files and record structural and recovery information. |
In the multitenant architecture, PDBs have datafiles within the CDB. They do not have independent control files or online redo log sets. See Oracle's physical storage documentation.
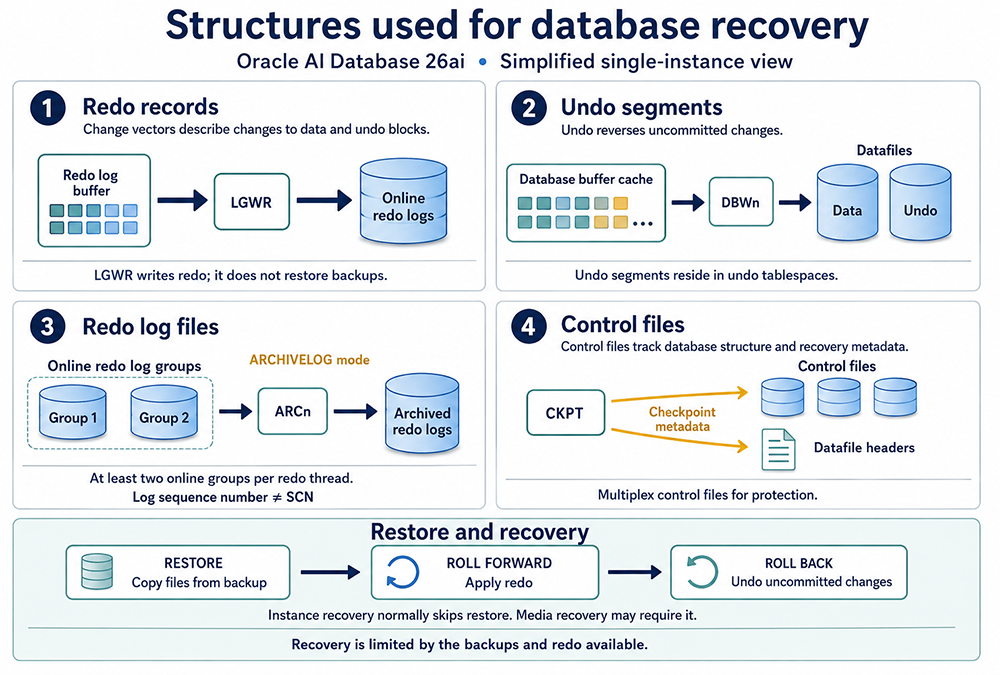
How Redo, Undo, and Checkpoints Work Together
Database activity generates redo in memory. Log Writer, LGWR, writes redo to online log files. Database Writer, DBWn, writes modified data blocks to datafiles. These are different responsibilities: writing redo does not mean every corresponding data block has already been written to its datafile.
Checkpoint information establishes where instance recovery must begin in the redo stream. The checkpoint process, CKPT, records checkpoint information; it does not write the modified data blocks itself. After an inconsistent shutdown, Oracle can use persistent redo to reconstruct changes missing from those blocks.
Roll-forward includes changes from transactions that had not committed. Undo then allows Oracle to reverse uncommitted work. Redo also records changes to undo blocks, so recovery can reconstruct the undo information it needs. This explains why replaying redo alone is not the same as retaining every change that occurred before a crash.
Modern explanations use undo segments in undo tablespaces. Older lessons often call these rollback segments. The key concept is the stored information needed to reverse transaction changes, not manual administration of legacy rollback segments.
The starting point for instance recovery is the checkpoint position, not the most recent backup. The SGA and redo log buffer are volatile memory and do not survive an instance failure as recoverable backup assets. Oracle's instance-recovery overview explains the relationship between checkpointing, redo application, and rollback.
Online Log Groups and Archived Redo
Each redo thread requires at least two online redo log groups. A group may contain multiple members holding the same redo, providing redundancy if a member is lost. A log switch moves writing to another group and advances the log sequence number. In RAC, sequence numbers must be interpreted with the redo thread; a sequence number alone is insufficient to identify a log across threads.
In NOARCHIVELOG mode, log groups can be reused without first retaining archived copies. Online redo still exists, but older history can be overwritten. In ARCHIVELOG mode, archiving preserves redo for subsequent recovery. These modes must not be confused with NOLOGGING, which can reduce data redo for certain operations.
Control Files Coordinate Recovery
The control file contains database structure, file identities, checkpoint information, log history, and RMAN backup metadata. A recovery catalog can supplement backup history, but it does not replace the control file needed to mount the database.
A missing control file is not handled simply by replaying application redo into it as though it were a datafile. Restoration or re-creation requires an appropriate recovery procedure. Missing backup metadata may also be obtained from a recovery catalog or registered through supported RMAN cataloging operations.
Multiplexed current control files provide redundancy. Historical control-file backups serve another purpose: recovering metadata when current copies are unavailable. Retaining multiple current copies does not eliminate the need for backups.
Requirements Depend on the Recovery Scenario
Instance failure with surviving storage
Oracle uses the existing datafiles, control files, and required online redo. Undo supports transaction rollback. This applies in both archiving modes and does not normally require restoring datafiles from backup.
Media recovery in ARCHIVELOG mode
Restored files need sufficient change history to reach the selected recovery target. Archived redo provides retained history, and surviving online redo may supply the newest changes. Applicable incremental backups can reduce the redo that must be applied. Complete recovery depends on having every required input, not merely a recent backup.
A gap does not automatically leave the database openable at the last available redo record. The recovery procedure must reach a valid consistent endpoint. Recovery cannot be reduced to making every file header display an identical SCN, because read-only and offline files complicate that shortcut.
Restoration in NOARCHIVELOG mode
Plan around a consistent whole-database backup. Suitable consistent incremental backups can advance the restored state through RECOVER DATABASE NOREDO, which avoids attempting archived-redo recovery. This is limited to what the backup chain contains; it does not provide arbitrary timestamp recovery or manufacture missing changes.
The next lesson develops the restore prerequisites. Oracle documents the incremental approach in NOARCHIVELOG recovery with incremental backups.
Supporting Assets and Tools
An SPFILE or PFILE supplies startup configuration. Backup pieces and image copies supply restoration data. Encryption keys, passwords, and storage credentials may be necessary to access those inputs. RMAN manages backup and recovery operations; it is a tool, not a substitute for the files and metadata it uses.
Tempfiles may need recreation and are not restored as ordinary RMAN backup contents. Block change tracking helps incremental backup selection rather than serving as a recovery input. The fast recovery area is a storage location for recovery-related files, not a redo stream. These distinctions help you inventory dependencies without treating every Oracle component as an essential backup file.
Check Your Understanding
Question: A server restarts after a power failure, but its database files and required online redo survive. Must an administrator restore a backup before instance recovery?
Answer: Normally no. Oracle uses the surviving files, redo, and undo to recover the existing database. Lost datafiles would create a different problem and could require restoration from backup.
The next lesson describes the files and backups required to restore a NOARCHIVELOG database.