| Lesson 2 | Implications of Instance Failure in ARCHIVELOG Mode |
| Objective | Explain how Oracle recovers after an instance failure and distinguish automatic instance recovery from media recovery and recovery from logical errors. |
Instance Failure and Recovery in Oracle AI Database 26ai
When an Oracle instance fails, its active sessions are interrupted and its memory contents are lost. If the current datafiles, control files, and required online redo logs remain intact, Oracle AI Database 26ai automatically performs instance recovery when the database is reopened. It reapplies recorded changes and removes uncommitted work, bringing the database back to a transactionally consistent state.
This recovery normally requires neither restoring a backup nor manually applying archived redo logs. It works in both ARCHIVELOG and NOARCHIVELOG modes. Archiving becomes especially important when files must be restored from an earlier backup, which is a different recovery situation.
What Fails When an Instance Stops?
An Oracle instance consists of memory structures and background processes that manage access to the database. The system global area, or SGA, contains structures such as the database buffer cache and redo log buffer. The database itself includes persistent files stored outside that memory.
A power interruption, operating-system failure, critical process failure, or SHUTDOWN ABORT can stop an instance without allowing a clean shutdown. Cached information disappears, connections break, and transactions may be interrupted. However, an abrupt shutdown does not by itself mean that the underlying database files have been destroyed.
During a clean shutdown, Oracle completes the required work to leave the database consistent on disk. Following an abrupt shutdown, some committed changes may still need to be written into datafiles, while some uncommitted changes may already be present there. Instance recovery resolves both conditions.
The first diagnostic question is therefore whether the persistent files survived. A server crash with intact storage and a disk failure that removes a datafile can produce similar application outages, but they require different responses.
Why Committed Changes Can Survive Lost Memory
Oracle separates writing transaction redo from writing modified database blocks. The log writer process, LGWR, writes redo to the online redo logs. Database writer processes write modified blocks from the buffer cache to datafiles as needed.
With normal synchronous commit behavior, Oracle acknowledges a successful commit after the transaction's redo and commit record have been written to persistent online redo. It does not have to write every modified data block to its datafile before acknowledging that commit.
Consider two sessions updating different customer records:
- Session A commits: Its redo is durable, but the modified customer block may still be in memory when the instance fails. Recovery can reconstruct that committed change from online redo.
- Session B does not commit: Some modified blocks may already have reached disk. Recovery uses undo to remove those uncommitted changes.
The survival of a transaction therefore depends on its durable commit information and the required files, not simply on whether its modified blocks were in the buffer cache. Losing memory does not automatically mean losing committed data. Losing essential redo at the same time can change the recovery outcome.
There is also an application distinction: a connection failure during a commit does not prove that the transaction failed. The server might have committed before its reply reached the client. Applications should resolve uncertain outcomes before retrying work that could create duplicate payments, orders, or other business operations.
The Two Phases of Instance Recovery
1. Cache Recovery: Roll Forward
Oracle uses checkpoint information to determine where recovery must begin in the online redo stream. A checkpoint records progress in writing changes to datafiles, allowing recovery to start from the appropriate position instead of replaying the database's entire history.
During cache recovery, Oracle applies the required online redo to reconstruct changes missing from the datafiles. This includes changes associated with committed and uncommitted transactions. Redo also reconstructs undo information needed for the next phase.
Rolling forward first may seem surprising because it can reintroduce uncommitted changes. Its purpose is to reconstruct the recorded block state, including the information required to identify and undo incomplete work.
2. Transaction Recovery: Roll Back
Oracle then uses undo to remove changes made by transactions that did not commit. Those changes might have reached the datafiles before the failure or might have been reapplied during cache recovery.
Rollback need not finish for every terminated transaction before users can access the database. Oracle can continue transaction recovery after opening, and a session accessing an affected block can perform the necessary rollback work for that block.
Oracle coordinates these phases automatically. The DBA does not normally issue RECOVER DATABASE for an ordinary instance crash. Oracle's instance recovery documentation explains the checkpoint, redo, and undo mechanisms involved.
What ARCHIVELOG Mode Adds
Both logging modes generate online redo and preserve the active redo needed for instance recovery. Oracle cannot simply reuse a log while its contents are still required for that purpose.
In ARCHIVELOG mode, filled online redo logs are also archived before reuse. These archived copies preserve a longer history of changes. That history enables media recovery of restored backups and supports recovery capabilities that are unavailable or substantially restricted without archiving.
The important distinction is between recovering current files after a crash and recovering older files restored from backup. NOARCHIVELOG does not inherently discard committed transactions after an ordinary instance failure. Its major limitation concerns recovering beyond a backup when current files are lost and the required redo history is unavailable.
| Situation | Recovery direction |
|---|---|
| The instance stops, but persistent database files remain usable. | Restart and allow automatic instance recovery using online redo and undo. |
| A datafile is lost or physically damaged. | Diagnose the affected scope, then restore and recover the file with RMAN as appropriate. |
| An unwanted change was committed to otherwise intact files. | Evaluate a suitable Flashback feature or point-in-time recovery. |
Deleting rows with a committed SQL statement is a logical error. Deleting the operating-system file containing those rows is physical file loss. The word "delete" describes both actions, but their recovery requirements differ.
Responding to an Ordinary Instance Failure
Begin by checking the host, storage availability, and diagnostic messages. Correct the underlying problem before restarting. If the instance is stopped, the files are intact, and the database uses a standalone startup procedure, a suitably privileged SQL*Plus session can illustrate the restart with:
STARTUPOracle starts the instance, mounts the database, and performs the required recovery as it opens. Cluster-managed deployments should follow their established startup procedure. In Oracle RAC, a surviving instance can automatically recover a failed instance's redo thread.
Review the alert log for recovery progress and subsequent errors. Confirm that the expected PDBs and application services are available, then verify an application connection and a representative business operation. Database recovery and restoration of the complete application service are related but separate checks.
Existing application sessions do not simply resume because the database has opened. Connection pools may need to discard failed connections and establish replacements. Scheduled jobs and interrupted requests also need attention according to their restart behavior. Record whether the outage interrupted a request before execution, during an uncommitted transaction, or while its commit result was being returned. These distinctions help application owners recover work without repeating an operation that already succeeded.
If startup reports missing files, damaged blocks, or a requirement for media recovery, reassess the incident. Repeated startup attempts do not replace diagnosis. Preserve usable files and diagnostic evidence while selecting the appropriate recovery procedure.
What Determines Recovery Time?
Recovery duration depends on the amount of redo to process, the blocks requiring changes, the volume of uncommitted work, and available CPU and storage performance. Checkpoint progress influences how much work must be repeated after a crash.
The FAST_START_MTTR_TARGET initialization parameter can guide checkpointing toward a target instance recovery time. Oracle also provides estimates through V$INSTANCE_RECOVERY. A target is not a guarantee of total application downtime: host restart, database startup, service availability, and application reconnection add their own time.
More aggressive checkpointing can increase normal-operation I/O, so recovery-time tuning should be evaluated against the actual workload. The Oracle performance tuning guidance describes this relationship.
Do not assume that an ARCHIVELOG database necessarily takes longer to recover from an instance crash because it has archived logs. Ordinary instance recovery uses online redo; workload and checkpoint behavior provide the relevant comparison.
Complete Media Recovery After File Loss
When a datafile is lost or damaged, restarting the instance cannot recreate its contents. In a typical RMAN workflow, RESTORE retrieves an appropriate backup, and RECOVER advances the restored file using redo and applicable incremental backups.
Complete recovery aims to bring the affected files to the current recoverable state. Reaching the failure point without losing committed changes requires suitable backups and all recovery information necessary for that endpoint. The newest changes may exist only in surviving online redo logs. ARCHIVELOG mode alone does not guarantee their survival.
For example, restoring a Monday backup after a Wednesday datafile loss returns that file to an older state. The required recovery information must advance it through the intervening changes before it can participate consistently in the current database. Restoring the backup is therefore only part of the operation. By contrast, an ordinary Wednesday instance crash with intact files starts recovery from the current files and their checkpoint position, rather than from Monday's backup.
Only the affected files may need restoration. Eligible noncritical datafiles can be taken offline and recovered while unaffected database contents remain available. Recovery involving SYSTEM or active undo requires an appropriate mounted recovery procedure. In a CDB, the affected container and recovery scope determine the required database state.
A missing archived-log file in one directory is not automatically an unrecoverable gap. RMAN may retrieve another copy from backup or use an applicable incremental backup to advance the affected files. However, if required recovery information remains unavailable for the selected recovery path, complete recovery cannot reach its intended endpoint.
Preserve surviving current control files and online redo logs where appropriate. Restoring every file indiscriminately can discard useful current information. Complete recovery with the current control file normally permits opening without RESETLOGS; point-in-time recovery and recovery using a backup control file follow different rules.
Detailed procedures depend on the failure and available backups. Oracle's complete database recovery guide provides the relevant scenarios.
Flashback Database and Recovery from Logical Errors
An instance can operate correctly while an application commits an unwanted update. Automatic instance recovery preserves validly committed transactions, including an update that was logically wrong. Repairing that error requires a method that deliberately returns data to an earlier state or corrects the affected objects.
The following diagram compares Flashback Database with backup-based point-in-time recovery. Both can return data to a point before an unwanted logical change, but they use different starting material.
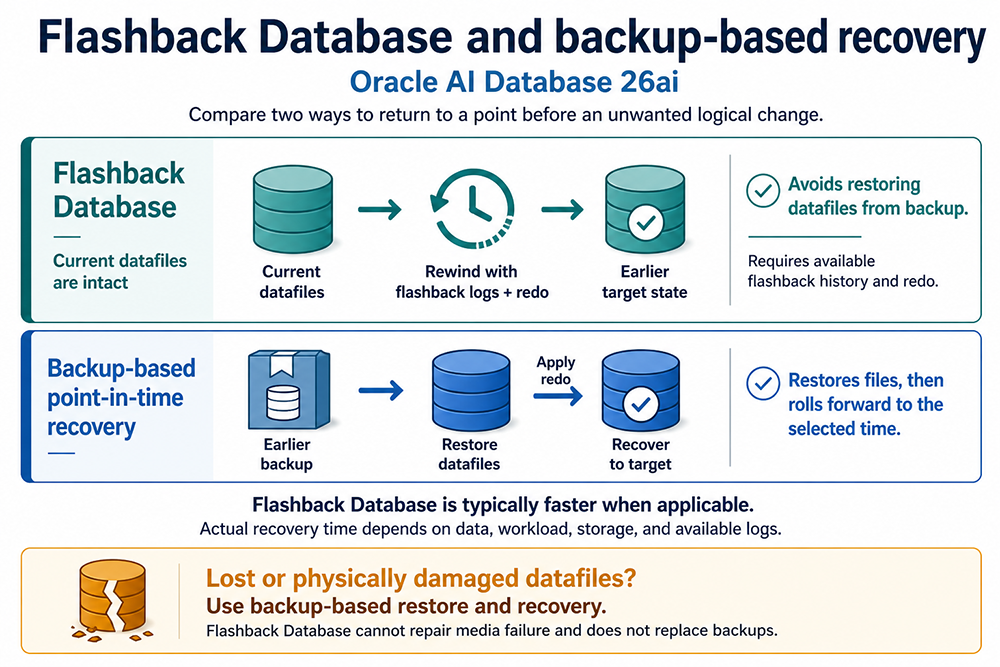
Flashback Database works on existing datafiles using available flashback history and redo. It requires ARCHIVELOG mode, a configured fast recovery area, and suitable advance logging or guaranteed-restore-point preparation. The selected target must remain reachable with the available recovery history.
Backup-based point-in-time recovery restores suitable earlier backups and applies recovery information up to the selected target. It is an alternative when Flashback Database cannot reach that time or is otherwise unsuitable.
Flashback Database is often faster because it avoids restoring datafiles, but its duration varies with changed data, storage, workload, and available logs. Neither method selectively removes only the offending transaction: wanted changes after the target are also removed within the recovered scope.
A normal restore point names a target; it does not preserve all required history. A flashback retention target is also not a guaranteed window. Guaranteed restore points provide stronger retention behavior, but still have storage requirements and documented limitations. Flashback Database cannot repair media failure or recreate an accidentally deleted datafile.
For narrower problems, Flashback Query can inspect older data and Flashback Table can return eligible tables to an earlier state using undo. These features have different prerequisites from Flashback Database. Select a method according to the error's scope and the available history, as described in Oracle's Flashback Database and restore point guidance.
Checking Database and Datafile Status
After mounting or opening the database as appropriate, use a suitably privileged connection to the CDB root for these read-only checks. Results depend on container visibility and the current database state.
SELECT name, log_mode, open_mode, flashback_on
FROM v$database;
This query reports the database name, logging mode, open mode, and Flashback configuration. FLASHBACK_ON can report YES, NO, or RESTORE POINT ONLY. It does not establish whether a specific target time remains recoverable.
SELECT con_id, file#, status, name
FROM v$datafile
ORDER BY con_id, file#;
The container identifier helps distinguish datafiles belonging to different containers. Status values include ONLINE, OFFLINE, SYSTEM, and RECOVER. These are metadata checks, not validation of every block or proof that backups are usable. Interpret them alongside the alert log and the relevant recovery diagnostics.
Prepare for Recovery Before a Failure
Use an RMAN backup strategy matched to acceptable data loss and downtime. ARCHIVELOG supports online backups, so routine database shutdowns are not a universal backup requirement. Online backups require recovery when restored; that is expected behavior.
If a failure interrupts a backup job, check which backup sets completed successfully. Do not assume that arbitrary partial output becomes usable by applying redo. RMAN does not select partial backups as restore candidates.
Protect datafiles, archived redo, control-file backups, and the server parameter file. Preserve encryption keys and separately back up password files and external configuration that RMAN does not include. Maintain recoverable copies outside the storage failure domain of the database.
Monitor archive destinations and recovery-area capacity. Archive consumption reflects redo generation and retention, rather than the number of instance crashes. Insufficient archive space can obstruct normal database operation, even when the datafiles are healthy.
Finally, test restoration and recovery through application verification. A completed backup job demonstrates that backup processing finished; it does not prove that every required file, log, key, credential, and recovery step will be available during an incident. Measure the complete recovery exercise against operational requirements.
The central lesson is to identify what failed before selecting a recovery method. Intact files after an instance crash normally call for automatic instance recovery. Lost files require media-recovery planning, while unwanted committed changes call for logical repair or point-in-time recovery. The next lesson examines recovery methods in greater detail.