| Lesson 7 | Monitoring Recovery Status with Dynamic Performance Views |
| Objective | Identify datafiles needing media recovery, monitor RMAN recovery from a separate administrative session, and verify completion using Oracle 26ai dynamic performance views and diagnostic output. |
Monitor Datafile Recovery Status in Oracle 26ai
Recovery monitoring involves three different questions: Which files need recovery? Is the selected operation progressing? Has recovery completed successfully? Oracle AI Database 26ai provides views that help answer each question, but no single query answers all three. Combine view output with the recovery command's results, file diagnostics, and the alert log.
The V$ objects discussed here are dynamic performance views. They are not physical files, and they do not all obtain information from the same source. Some report control-file metadata, some inspect datafile headers, and others expose runtime information. What you can see depends on privileges, database state, container, instance, and the operation being performed.
This lesson uses complete media recovery of a datafile in a single-instance primary CDB running in ARCHIVELOG mode. The current control file is usable, storage has been repaired, and suitable backups and all required redo are available. RMAN performs the work while a separate authorized SQL*Plus session observes progress.
The example uses file 7 and a Windows filename. Verify the actual file number and container in your environment. Restoring a control file, performing point-in-time recovery, or recovering a NOARCHIVELOG database requires a different plan.
Select a View for the Question You Are Asking
| Question | Primary evidence | Important limitation |
|---|---|---|
| Which files need attention? | V$RECOVER_FILE, V$DATAFILE_HEADER, and diagnostic errors | Control-file history and header readability affect interpretation. |
| Is recovery progressing? | V$RECOVERY_PROGRESS, RMAN output, and the alert log | Available metrics depend on the operation. |
| How far has an RMAN operation progressed? | V$SESSION_LONGOPS | A row describes an instrumented operation, not necessarily the complete job. |
| Can the database be opened? | Successful recovery results and a review of all outstanding file requirements | An empty monitoring query is not sufficient evidence. |
Record the instance, container, file number, and observation time when collecting evidence. A result from the wrong database or an earlier operation can be technically valid yet irrelevant to the current incident. When several RMAN jobs are running, correlate session identifiers and start times with the job you intend to monitor.
Why Some Recovery Views Are Process-Local
V$RECOVERY_STATUS and V$RECOVERY_FILE_STATUS remain documented in Oracle 26ai. Their useful information belongs to the Oracle process performing recovery. When RMAN directs that process, a separate SQL*Plus connection cannot retrieve its relevant information through these views, even under the same administrative account.
V$RECOVERY_STATUS describes recovery-process state, including the needed redo thread and sequence. V$RECOVERY_FILE_STATUS describes files associated with a recovery statement. These are process-local reference queries, not the queries to run in the separate RMAN monitoring session:
SELECT recovery_checkpoint, thread, sequence_needed,
       scn_needed, reason
FROM v$recovery_status;

SELECT filenum, filename, status
FROM v$recovery_file_status;
The same visibility limitation applies to V$RECOVERY_LOG, which reports archived logs needed by the recovery process. Empty results from these views in another connection do not mean that RMAN has finished or that no redo is required. Oracle documents the restriction in the references for V$RECOVERY_STATUS, V$RECOVERY_FILE_STATUS, and V$RECOVERY_LOG.
Datafile Media Recovery: Monitoring Workflow
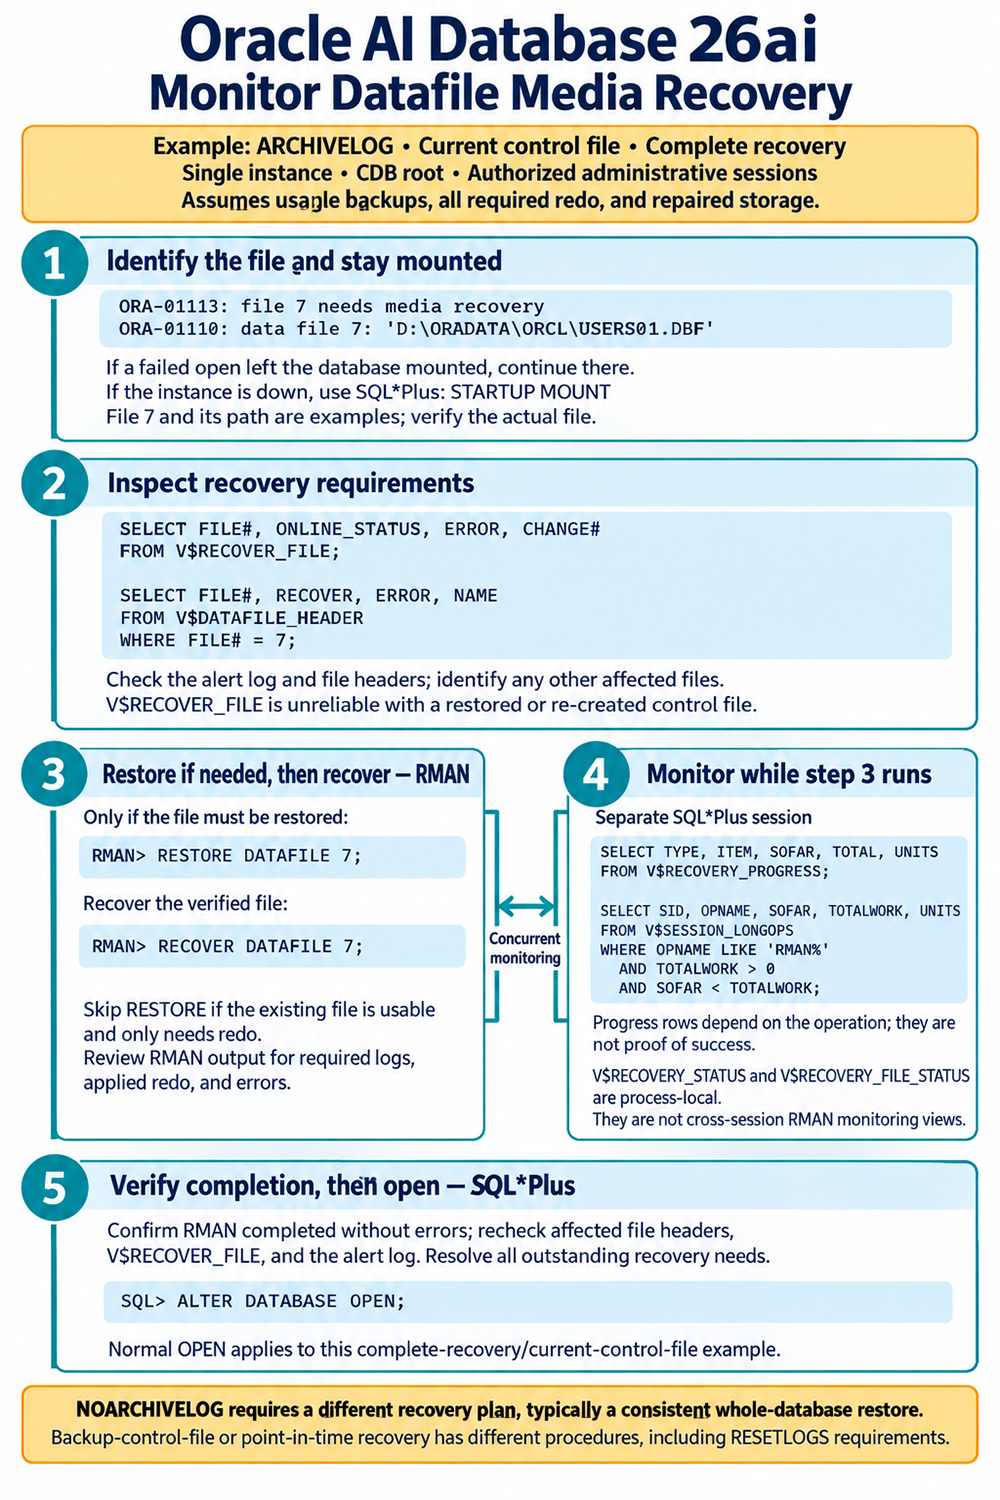
1. Identify the File and Confirm the Database State
An attempted open might report the following illustrative error:
ORA-01113: file 7 needs media recovery
ORA-01110: data file 7: 'D:\ORADATA\ORCL\USERS01.DBF'
The messages identify a recovery requirement and its associated file. They do not independently establish physical corruption. Review the complete error stack, including operating-system errors, and determine whether the file is missing, inaccessible, damaged, or simply requires redo.
If the failed open left the database mounted, continue from that state. If the instance is down, an authorized SQL*Plus session can mount it with STARTUP MOUNT. Do not issue startup unconditionally against a running instance.
Confirm that the administrative session is connected to the intended CDB root:
SHOW CON_NAME

SELECT instance_name, status
FROM v$instance;

SELECT name, database_role, open_mode, log_mode
FROM v$database;
Keep the database mounted for this example. Other recovery procedures can keep unaffected data available, but choosing those procedures depends on the file's role and recovery scope. The first reported file is also not necessarily the only affected file.
2. Inspect Recovery Requirements and File Headers
Start by examining recovery requirements across the visible files:
SELECT con_id, file#, online_status, error, change#, time
FROM v$recover_file
ORDER BY con_id, file#;
V$RECOVER_FILE identifies files needing media-recovery attention and the starting SCN where applicable. Interpret its ERROR value; for example, OFFLINE NORMAL does not indicate that recovery is required. This view has no NAME column. Obtain names from V$DATAFILE or the header view.
Do not rely on this view with a restored control file or one re-created after the media failure. Such a control file lacks the information needed to update the view accurately. The current-control-file assumption in this example matters.
Inspect the verified file's header:
SELECT con_id, file#, recover, error, fuzzy,
       checkpoint_change#, name
FROM v$datafile_header
WHERE file# = 7;
Check RECOVER and ERROR together. A header-read error can require investigation of temporary access problems before deciding to restore. A usable file that needs redo may require recovery without restoration. Header inspection alone cannot detect every corrupt data block.
FUZZY is not a standalone corruption test. Its interpretation depends on database state and the file's circumstances. Likewise, requiring every file-header SCN to be identical is not a universal health test. Use the file requirements, command output, and diagnostics together. See the definitions of V$RECOVER_FILE and V$DATAFILE_HEADER.
3. Restore When Necessary, Then Recover with RMAN
In Session A, connect RMAN to the intended target CDB root using authorized credentials. Confirm the absolute datafile number, using REPORT SCHEMA when needed. Before proceeding, establish that required backups and redo are available and that the storage fault has been addressed.
Only when the file must be replaced from backup, restore it:
RMAN> RESTORE DATAFILE 7;If the existing file is usable and only needs redo, skip that restore. Then recover the verified file:
RMAN> RECOVER DATAFILE 7;RESTORE retrieves a backup file; RECOVER brings it forward using the applicable recovery inputs. Required redo can include online as well as archived redo. Do not assume that any available backup and a few archives are sufficient for complete recovery.
Read RMAN's output for selected files, required logs, progress messages, and errors. Do not add an UNTIL target or backup-mode commands to this complete-recovery example. If a backup or required log is unavailable, diagnose the missing input instead of treating an unchanged progress counter as the cause.
4. Monitor Concurrently from a Separate Session
While Session A performs its work, use a second authorized SQL*Plus connection to the same instance and CDB root. The monitoring step runs concurrently with recovery; it is not something to begin only after RECOVER returns.
SELECT start_time, type, item, sofar, total, units
FROM v$recovery_progress
ORDER BY start_time, type, item;
Read TYPE, ITEM, and UNITS together. An apply-rate item is different from an amount-of-redo item, so a generic calculation across all rows is misleading. Available rows depend on the recovery operation; not every file recovery provides every metric. Compare repeated samples with RMAN messages rather than expecting a fixed set of rows. Oracle documents these fields in V$RECOVERY_PROGRESS.
For instrumented RMAN operations, inspect long-operation rows:
SELECT sid, serial#, opname, sofar, totalwork, units,
       start_time, last_update_time,
       ROUND(100 * sofar / NULLIF(totalwork, 0), 1) AS pct_operation
FROM v$session_longops
WHERE opname LIKE 'RMAN%'
  AND opname NOT LIKE '%aggregate%'
  AND totalwork > 0
  AND sofar < totalwork
ORDER BY start_time, sid;
The percentage describes one reported operation. It is not the percentage of the entire restore-and-recovery job. Another stage or channel may still have work after a row reaches completion. The filter hides completed rows and can also match other RMAN jobs, so use session identifiers and times to interpret it.
Short operations or stages without matching instrumentation may not appear. Time estimates can change as work proceeds. Do not sum percentages from unrelated rows or interpret an empty result as success. The relevant column definitions are in V$SESSION_LONGOPS.
5. Verify Completion Before Opening
After RMAN reports successful completion, review its full output and the alert log. Recheck the affected headers and recovery requirements, including any other files identified earlier. Resolve outstanding problems before attempting to open the database.
Only when this mounted database is ready after complete recovery with its current control file, issue:
ALTER DATABASE OPEN;This is a normal open. Do not add RESETLOGS as a generic recovery step. Point-in-time recovery and recovery with a backup control file have different procedures. If opening reports another recovery error, investigate it rather than assuming the monitoring query already proved readiness.
Verify the resulting database and PDB states:
SELECT name, open_mode
FROM v$database;

SELECT con_id, name, open_mode, restricted
FROM v$pdbs;
Confirm the required application PDBs and application access separately. Successful media recovery does not itself establish that all services and application data checks have completed. Retain the recovery output and incident observations for the operational record.
Interpret Supporting Views in Context
Several other views help explain an incident without serving as its primary progress monitor. Use them to answer a specific supporting question.
| View | Useful information | What it does not establish |
|---|---|---|
V$ARCHIVED_LOG | Control-file records for archived redo and copies | That every recorded file remains readable |
V$LOG_HISTORY | Historical redo information | That a required archive copy is available |
V$RECOVERY_FILE_DEST | Fast Recovery Area space accounting | That media recovery has completed |
V$BACKUP | User-managed datafile backup-mode state | That an RMAN backup succeeded |
V$INSTANCE_RECOVERY | Checkpoint-related recovery targets and estimated MTTR | A live media-recovery completion percentage |
V$FAST_START_TRANSACTIONS | Parallel transaction recovery progress | Progress for every serial transaction or datafile restore |
Archived Log Records Are Not Proof of Applied Recovery
In V$ARCHIVED_LOG, multiple copies can produce multiple records. Identify redo using the thread, sequence, and incarnation information, rather than a sequence number alone. A recorded filename is not a physical validation of that file.
APPLIED describes physical standby apply for the relevant RFS-registered records. It is always NO for local destinations. It is therefore unsuitable as a primary RMAN recovery completion test. Neither the highest sequence number nor a count of archived-log rows proves that all required redo was applied. See V$ARCHIVED_LOG.
Backup Mode and Checkpoint Estimates Answer Different Questions
To investigate files specifically left in user-managed backup mode, use STATUS='ACTIVE' in V$BACKUP. A filter for everything other than NOT ACTIVE also includes other conditions. Do not issue END BACKUP merely because a file requires media recovery. Ordinary RMAN recovery does not require that backup-mode sequence. See V$BACKUP.
V$INSTANCE_RECOVERY helps assess checkpoint and recovery-I/O targets. Its estimated MTTR is not a countdown for the current datafile recovery. Similarly, V$FAST_START_TRANSACTIONS covers parallel transaction recovery; absence of rows does not describe all possible serial rollback work. Consult V$INSTANCE_RECOVERY and V$FAST_START_TRANSACTIONS for their scope.
When Progress Appears to Stop
First verify that your observation belongs to the intended instance, container, session, and operation. Then review RMAN output and recent alert-log entries. Recovery might be waiting for an input, encountering storage errors, moving between stages, or completing too quickly for your sampling interval. A counter alone cannot distinguish these cases.
Record successive observations with timestamps. Check whether RMAN reports an unavailable archive or a backup-read problem before changing anything. If the error names another file, expand the investigation to that file. Avoid canceling recovery solely because one view is empty or unchanged.
Monitoring should inform the next diagnostic step, not automatically trigger a restore, clearing operation, or RESETLOGS. The commands that change the database must follow the recovery plan and the actual failure evidence.
The next lesson concludes the module by bringing together these recovery and redo-maintenance decisions.
Recovery procedure reference: Oracle AI Database Backup and Recovery User's Guide, 26ai, G43741-04, May 2026, Chapter 16, Preparing for Complete Database Recovery, and the RMAN monitoring guidance.