| Lesson 4 | Incomplete database recovery steps |
| Objective | Explain and sequence the preparation, restore, recovery, reopening, and validation steps for whole-CDB point-in-time recovery with RMAN. |
Incomplete Database Recovery Steps in Oracle AI Database 26ai
Incomplete recovery returns a database to an earlier consistent state. In an RMAN database point-in-time recovery, or DBPITR, you restore suitable data file backups and apply recovery information up to the selected endpoint. You then reopen the recovered database and verify that its application data matches the intended state.
The order matters. If RMAN restores files that are too recent for the target, ordinary forward media recovery cannot move their contents backward. If required redo is missing, recovery cannot simply ignore the gap. Establishing the target before restoration and checking the outcome before resuming application access are central parts of the procedure.
Assumptions for This Procedure
The main example covers whole-CDB RMAN DBPITR in ARCHIVELOG mode. It assumes that the current control file and server parameter file, or SPFILE, remain available and that the recovery target belongs to the current database incarnation. Suitable backups, required redo, storage access, channels, and any necessary decryption material must also be available.
Connect RMAN to the CDB root as an appropriately privileged common user, such as one with SYSBACKUP or SYSDBA. This connection administers recovery of the whole CDB. It does not mean that the root can be independently recovered to an earlier point while its PDBs remain at unrelated states.
Restoring a lost control file or SPFILE, recovering to an ancestor incarnation, and performing PDB or tablespace PITR require additional procedures. RAC and Data Guard environments also need their documented coordination steps. Confirm that the example's assumptions match the intended recovery before adapting its commands.
1. Choose the Target and Preserve Recovery Options
Identify the incident and select the state you need to recover. For a harmful application change, determine when the unwanted work committed, rather than relying only on when someone reported the problem. For missing redo, investigate alternate archive destinations, backups, suitable standby copies, and other valid recovery paths before accepting an earlier endpoint.
Preserve the current state and incident evidence where feasible. A supported preservation backup or copy can retain options for investigation and retry, but a new whole closed database backup is not a universal prerequisite. After serious media loss, creating such a backup may be impossible. Do not confuse preserving surviving files with obtaining the earlier backups needed for PITR.
Verify that the selected backups and recovery history can reach the target. Encrypted backups require their decryption credentials or keystore, and encrypted data may require access to the appropriate keys during recovery. Backup records alone do not guarantee readable storage. Confirm practical access and capacity before restoring over existing data files.
2. Bring the Whole CDB to MOUNT
Stop application access and arrange the recovery outage. Whole-CDB DBPITR affects the CDB's included PDBs, so coordinate with all affected application owners. Prevent automatic reconnection or background application jobs from resuming writes when the database is reopened for verification.
With RMAN connected to the root, bring the database to the mounted state. MOUNT means that the instance has mounted the database using the control file; the database is not open for normal application access. In this RMAN procedure, mounting occurs before RESTORE DATABASE.
The example below assumes the CDB is initially open and can shut down normally. If it is already mounted, omit the shutdown and startup commands. A failed instance or unavailable control file requires preparation appropriate to that condition, rather than blindly repeating the same startup sequence.
3. Set the Target Before Restoring
Use SET UNTIL before both RESTORE DATABASE and RECOVER DATABASE in the same RMAN RUN block. This makes the target apply to backup selection as well as redo application. Setting it only after restoration may leave you with files that cannot be recovered to the desired earlier state.
RMAN selects suitable backups subject to the target and other applicable criteria. These may include full data file backups, incremental level 0 backups, or image copies. It does not invariably retrieve the newest backup overall, nor must all selected files come from one backup set. The selected files must collectively support the recovery plan.
RESTORE retrieves the data files; it does not itself perform the complete roll-forward to the target. An online backup can require additional recovery before its restored files are consistent. Keep the distinction between restoring a starting state and applying the changes needed to reach the endpoint.
4. Recover to the Selected Boundary
RECOVER DATABASE applies the required incremental changes and redo. RMAN can restore needed archived logs from backup when suitable channels and storage are available. The result must satisfy Oracle's consistency requirements for the recovered scope.
In the example, SET UNTIL SCN 1418901 establishes an exclusive upper boundary. Recovery excludes SCN 1418901 and, in this simplified illustration, proceeds through SCN 1418900. Replace the sample number with a target established from the actual database's history.
If restoration or recovery fails, investigate before reopening. A missing pathname, unreadable backup, and insufficient redo describe different problems. Do not proceed to RESETLOGS merely because some logs were applied. The command cannot make incompatible or insufficiently recovered files consistent by ignoring their recovery requirements.
5. Open with RESETLOGS and Open the Intended PDBs
After successful whole-CDB incomplete recovery, open the mounted CDB with RESETLOGS. This establishes a new database incarnation and restarts redo sequence numbering. Database SCNs do not reset to 1, and the database does not receive a new DBID.
Opening the CDB does not automatically open its PDBs. Open the intended PDBs afterward, while application access remains controlled. Opening all applicable PDBs can be appropriate for this whole-CDB example, but an actual environment may require opening them individually in a planned order.
The decision to reopen should follow review of the recovery result. Where the recovered state permits it, optional read-only inspection can help verify data before RESETLOGS. This does not bypass media recovery requirements. Return the database to mounted state before continuing recovery or performing the final RESETLOGS open.
6. Validate the Data and Review Backup Protection
Check representative application data after opening the required PDBs. Confirm that expected records are present, unwanted changes are absent, and important business relationships remain correct. The existence of a recovered table alone does not demonstrate that its rows match the intended endpoint.
A new backup after RESETLOGS is optional in Oracle 26ai. Earlier backups can remain usable with the required recovery history and incarnation information. A fresh backup can still provide a useful operational baseline, but it is incorrect to say that only this new backup is valid for future recovery.
Retain older backups and archived logs according to recovery and retention requirements. Review scheduled backups and any standby implications, then restore application access when verification and reconciliation are complete. A successful database open is one milestone in recovery, not the only acceptance criterion.
Illustrative RMAN Recovery Sequence
This sequence matches the diagram: whole CDB, ARCHIVELOG mode, current control file and SPFILE, and a target in the current incarnation. It assumes usable backups, accessible recovery material, configured channels, and an initially open CDB. Treat the commands as a supervised example: resolve any failure before proceeding to the next stage.
SHUTDOWN IMMEDIATE;
STARTUP MOUNT;

RUN {
  SET UNTIL SCN 1418901;
  RESTORE DATABASE;
  RECOVER DATABASE;
}

ALTER DATABASE OPEN RESETLOGS;
After the CDB opens, the following is a separate SQL*Plus example, executed while connected to the root, when all applicable PDBs should be opened:
ALTER PLUGGABLE DATABASE ALL OPEN;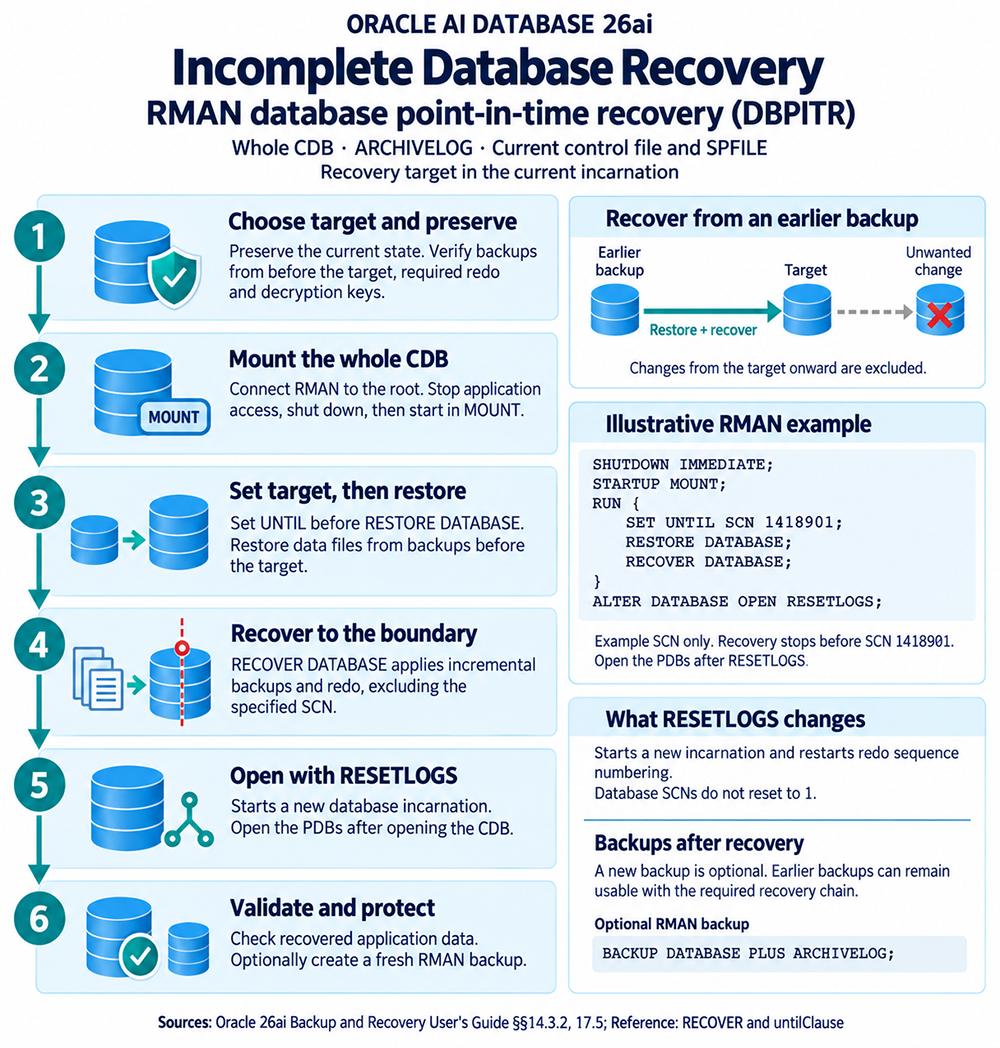
Using Another RMAN Target
The target-setting statement can instead express a time, log sequence, or existing named restore point. The following statements are alternatives to the example's SCN target, not a sequence to run together. Place the chosen statement before RESTORE and RECOVER in the appropriate RUN block.
SET UNTIL TIME "TO_DATE('2026-09-10 14:29:00', 'YYYY-MM-DD HH24:MI:SS')";
SET UNTIL SEQUENCE 480 THREAD 1;
SET TO RESTORE POINT before_update;
The explicit time format avoids dependence on the default date format but does not supply a time zone. Sequence 480 is excluded, and its redo thread and incarnation must be identified correctly. The restore point must exist and have the necessary recovery material. Restore-point boundary semantics should not be inferred from the exclusive UNTIL SCN rule.
Optional Backup After Successful Recovery
If the recovery policy calls for a fresh baseline, an optional RMAN backup can be taken after the CDB and intended PDBs are open and the backup configuration is ready:
BACKUP DATABASE PLUS ARCHIVELOG;An additional shutdown is not inherently required for this RMAN backup in ARCHIVELOG mode. Preserve earlier recovery material rather than deleting it because the redo sequence has restarted. Recovery through an incarnation boundary depends on the correct history, not merely on the presence of one newly created backup.
User-Managed Recovery with SQL*Plus
The earlier command examples in this course also introduce user-managed recovery. SQL*Plus RECOVER commands use their own syntax and assume that the required user-managed restore preparation has already been performed. They are alternatives to the main RMAN procedure, not additional commands to append to its RUN block.
| Recovery case | SQL*Plus command |
|---|---|
| Time-based | RECOVER DATABASE UNTIL TIME '2026-09-10:14:29:00' |
| Cancel-based | RECOVER DATABASE UNTIL CANCEL |
| Change-based | RECOVER DATABASE UNTIL CHANGE 1418901 |
| Backup-control-file context, cancel-based | RECOVER DATABASE USING BACKUP CONTROLFILE UNTIL CANCEL |
A backup control file describes the recovery context rather than a distinct endpoint method. It can be used during complete recovery when the necessary information is available, although reopening after backup-control-file recovery still requires RESETLOGS. That case needs its own preparation and is outside the current-control-file assumptions of the main example.
Automatic Redo Application in SQL*Plus
For user-managed recovery, you can issue SET AUTORECOVERY ON before RECOVER, or use the AUTOMATIC keyword in the command. For example:
RECOVER AUTOMATIC DATABASE UNTIL TIME '2026-09-10:14:29:00'Entering AUTO at a recovery prompt is another interaction option. Automatic application helps supply redo files using the expected locations and names; it does not create missing redo or establish an acceptable business target. RMAN already manages recovery selection through its own interface.
SQL*Plus RECOVER and the SQL statement ALTER DATABASE RECOVER have separately documented syntax. Do not assume that prefixing ALTER DATABASE to any SQL*Plus command makes it equivalent, or that an Enterprise Manager recovery workflow depends on that textual substitution.
Inspect Data File Headers During Recovery
Recovery output and the alert log are the primary record of what Oracle applied and where it stopped. Data file header information can help investigate files that still need attention. From SQL*Plus connected to the root with appropriate privileges, inspect the relevant state using:
SELECT con_id,
       file#,
       status,
       recover,
       fuzzy,
       error,
       checkpoint_change#,
       TO_CHAR(checkpoint_time, 'YYYY-MM-DD HH24:MI:SS') AS checkpoint_time
FROM   v$datafile_header
ORDER BY con_id, file#;
CON_ID identifies the container context, while FILE# identifies the file. RECOVER indicates whether media recovery is needed. FUZZY describes a fuzzy file state, and ERROR reports a problem reading or validating the header. The checkpoint fields describe the file's checkpoint position.
A restored file showing FUZZY=YES can require additional recovery. However, FUZZY=NO and apparently matching checkpoint values do not independently prove that all recovery requirements or business checks have been satisfied. Read-only and offline-normal files have documented exceptions that must be considered when interpreting the overall state.
This query examines header information; it does not scan every block for corruption. Do not define fuzziness merely by comparing one block SCN with a header checkpoint or assume that every open file always reports YES. The earlier lesson on monitoring open database backups with V$DATAFILE_HEADER provides related context.
Validate the Endpoint and Plan Any Retry
Compare the recovered application state with the incident evidence. For a harmful batch, check both that its unwanted effects are absent and that expected earlier records remain. Also determine which later valid transactions were excluded within the recovered scope.
If recovery stopped too early and RESETLOGS has not committed the new branch, further available redo may permit advancement. If too much redo was applied, a restore-based retry normally requires restoring suitable backups again. After RESETLOGS, further recovery planning must also account for incarnation history. Preserve the transcript and recovery material so that the next decision is informed.
External services may retain newer information than the recovered database. Payments can already have settled, messages can already have been delivered, and downstream systems can still contain later orders. Reconcile those effects before replaying transactions. Application correctness requires more than reopening files without Oracle errors.
When a Different Recovery Procedure Fits Better
Flashback Database may reach the desired earlier state without restoring data files when usable flashback history and required redo are available. It is an alternative recovery technique, not a RESTORE command. It cannot recreate missing flashback history merely because flashback is enabled after an incident.
PDB PITR recovers a selected PDB through a scoped RMAN procedure, allowing other PDBs to remain operational where the environment permits. It uses the PDB reopening procedure, including PDB RESETLOGS. Do not reset the whole CDB simply to complete recovery of one PDB.
TSPITR uses auxiliary recovery for an eligible set of tablespaces. Affected tablespaces are unavailable during that work, while the rest of the PDB may remain available. The production target CDB does not require RESETLOGS solely because selected tablespaces underwent TSPITR.
Finally, consider whether NOLOGGING operations left changes that cannot be reconstructed from redo alone. NOLOGGING does not disable all DML redo, and changing a logging default cannot retroactively supply missing history. Backup and logging policies must support the recovery state you intend to achieve.
The next lesson explains how to monitor recovery progress and investigate recovery messages using the alert log.