| Lesson 5 | Data normalization |
| Objective | Define data normalization. |
Define Data Normalization
When you design the tables in a database, you also define the relationships between them, and that process decides how the data is actually stored. Normalizing a database means organizing its tables so the same data doesn't repeat itself across rows. The usual result is a larger number of tables, each with fewer columns, tied together by a larger number of defined relationships.
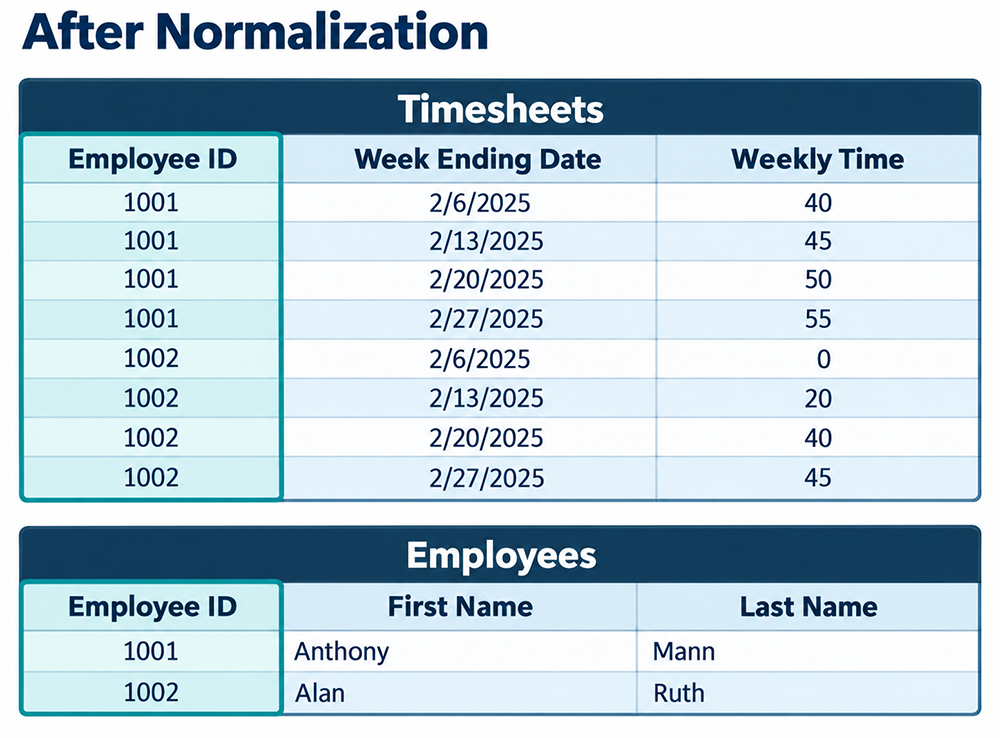
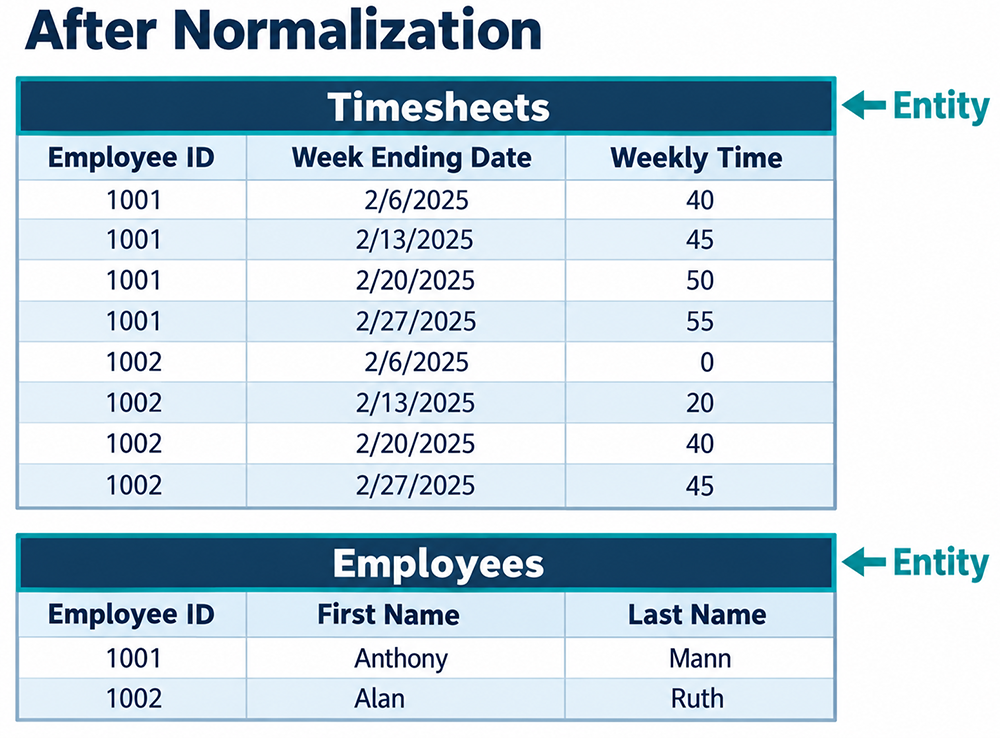
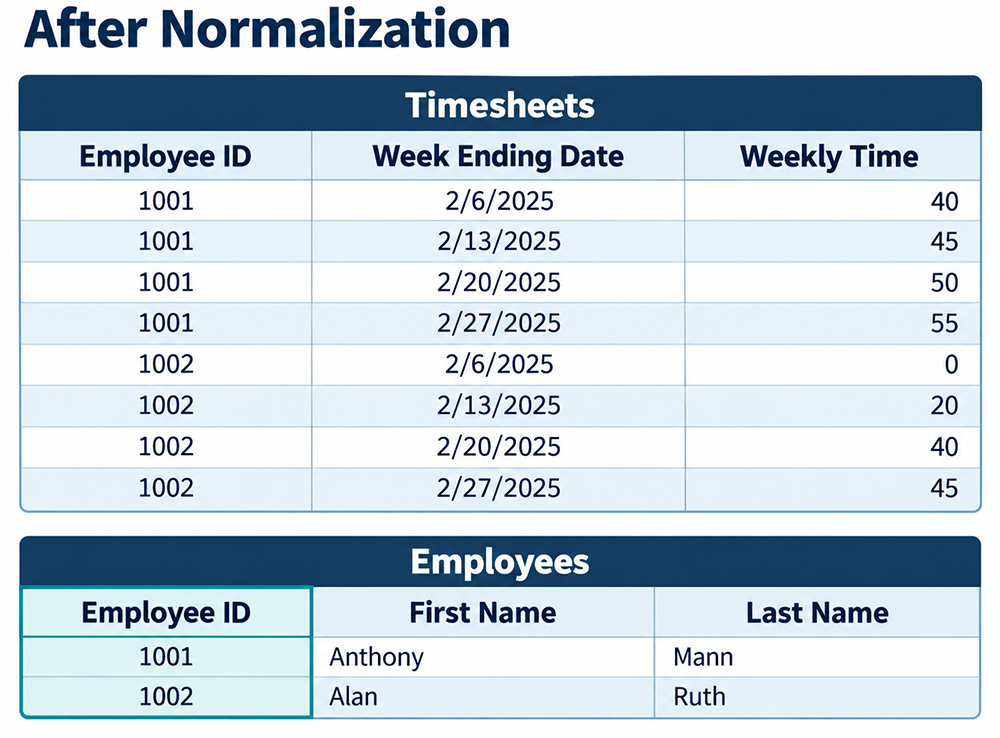
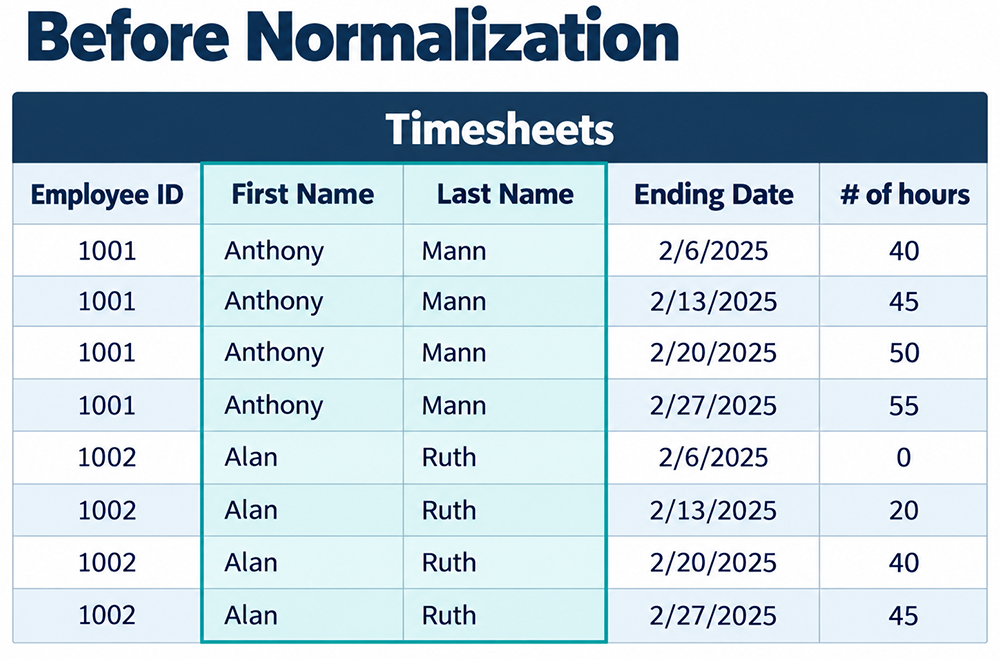
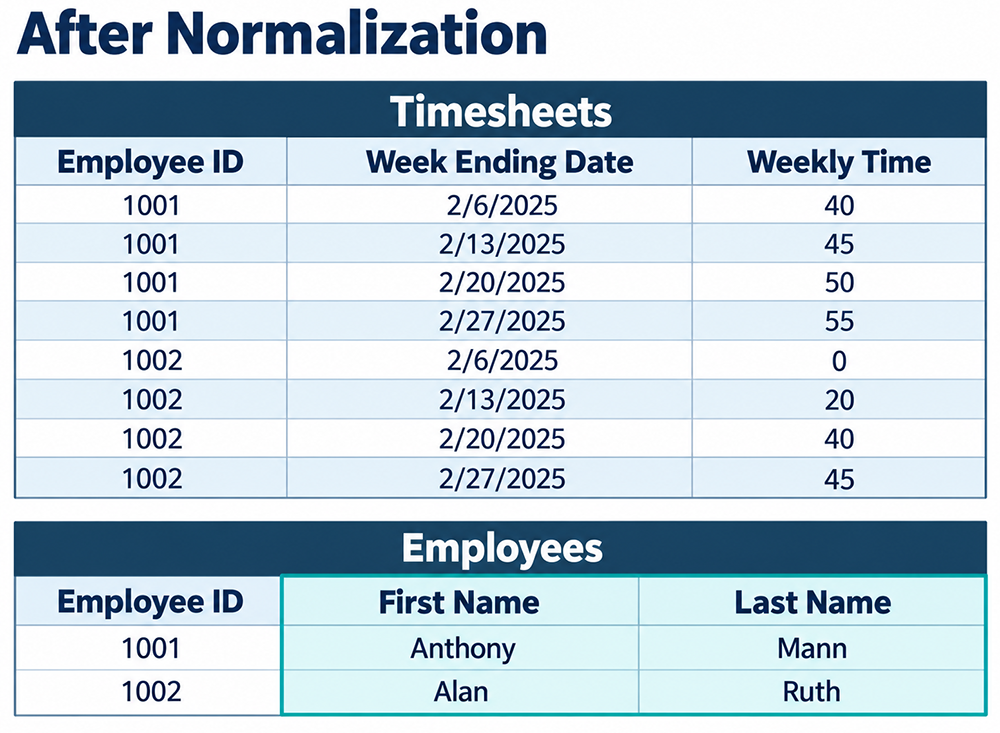
Normalizing is generally a good idea: non-repeating data tends to need less disk space, and well-indexed normalized tables are usually faster to query. That's not a universal rule, though, since normalization also increases the number of tables involved, and a query that has to join many tables together can run more slowly than one against a single wide table. The basic idea is to remove repeating columns wherever possible and move them into one or more new tables. The figures below walk through an example.
Normalizing is generally a good idea: non-repeating data tends to need less disk space, and well-indexed normalized tables are usually faster to query. That's not a universal rule, though, since normalization also increases the number of tables involved, and a query that has to join many tables together can run more slowly than one against a single wide table. The basic idea is to remove repeating columns wherever possible and move them into one or more new tables. The figures below walk through an example.
Remove Repeating Columns
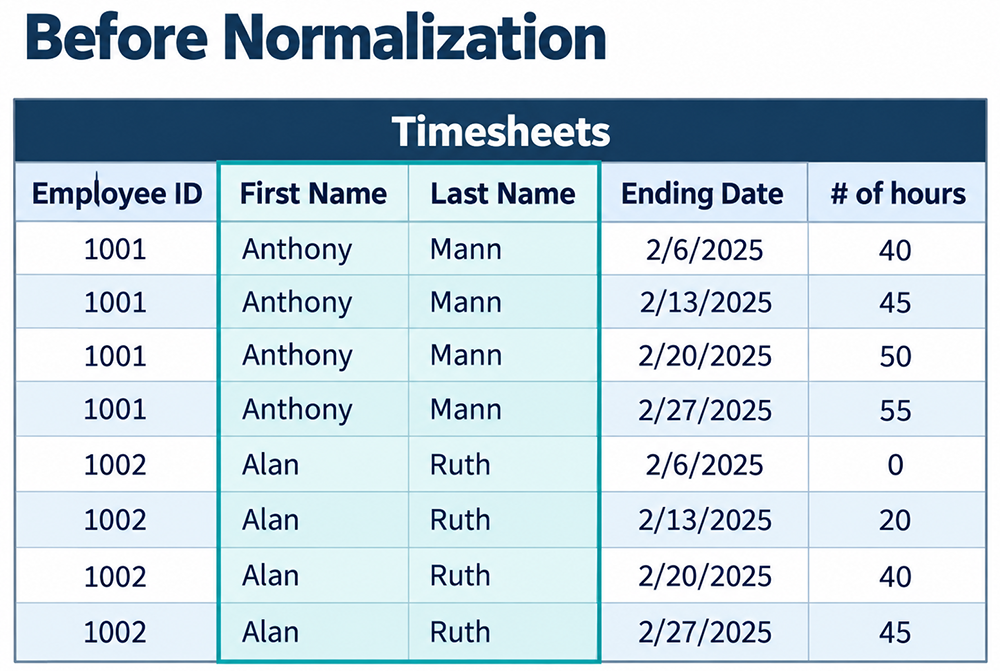
| Employee ID | First Name | Last Name | Ending Date | # of hours |
|-------------|------------|-----------|-------------|------------|
| 1001        | Anthony    | Mann      | 2/6/2025    | 40         |
| 1001        | Anthony    | Mann      | 2/13/2025   | 45         |
| 1001        | Anthony    | Mann      | 2/20/2025   | 50         |
| 1001        | Anthony    | Mann      | 2/27/2025   | 55         |
| 1002        | Alan       | Ruth      | 2/6/2025    | 0          |
| 1002        | Alan       | Ruth      | 2/13/2025   | 20         |
| 1002        | Alan       | Ruth      | 2/20/2025   | 40         |
| 1002        | Alan       | Ruth      | 2/27/2025   | 45         |
Purpose and Stages of Data Normalization
When designing a database for an organization, the main objective is to create an accurate representation of the data, the relationships between that data, and the constraints on it that matter to the organization. One technique for this is Entity-Relationship (ER) modeling. This lesson covers a different, complementary technique: normalization.
Normalization is a database design technique that begins by examining the relationships, called functional dependencies, between attributes. Attributes describe some property of the data, or of the relationships between the data, that matters to the organization. Normalization uses a series of tests, described as normal forms, to help identify the optimal grouping for these attributes, ultimately arriving at a set of tables that supports the organization's data requirements. The main purpose of this lesson is to introduce functional dependencies and describe normalization up to Third Normal Form (3NF); a later lesson takes a more formal look at functional dependencies and considers normal forms beyond 3NF.
Normalization, in other words, is a technique for producing a set of tables with desirable properties, given an organization's data requirements. A suitable set of tables has three characteristics:
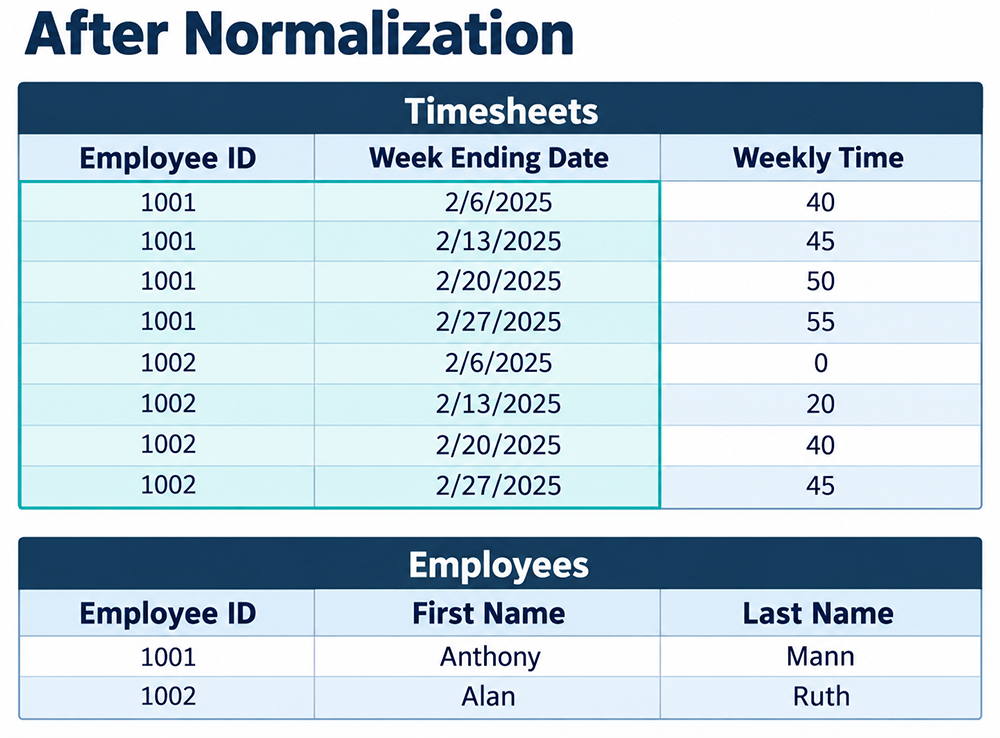
The figures above are a working example of a functional dependency. In the original Timesheets table,
Normalization is a database design technique that begins by examining the relationships, called functional dependencies, between attributes. Attributes describe some property of the data, or of the relationships between the data, that matters to the organization. Normalization uses a series of tests, described as normal forms, to help identify the optimal grouping for these attributes, ultimately arriving at a set of tables that supports the organization's data requirements. The main purpose of this lesson is to introduce functional dependencies and describe normalization up to Third Normal Form (3NF); a later lesson takes a more formal look at functional dependencies and considers normal forms beyond 3NF.
Normalization, in other words, is a technique for producing a set of tables with desirable properties, given an organization's data requirements. A suitable set of tables has three characteristics:
- It uses the minimal number of attributes necessary to support the data requirements.
- Attributes with a close logical relationship, a functional dependency, are found in the same table.
- Redundancy is minimal, with each attribute represented only once, with the important exception of the attributes that form all or part of a foreign key, which are essential for joining related tables back together.
The figures above are a working example of a functional dependency. In the original Timesheets table,
FirstName and LastName are functionally dependent on EmployeeID: once you know the employee ID, the name is determined, it can't vary from row to row for the same employee. That dependency is exactly what makes the name columns redundant in a table keyed on both EmployeeID and EndingDate, and exactly why they belong in their own Employees table instead, keyed on EmployeeID alone. Spotting a functional dependency like this one is the starting point for every normal form that follows.How Normalization Affects Performance and Beyond
Normalizing a database is rarely free of trade-offs. The table below works through its effects across six factors relevant to any SQL Server 2025 deployment:
Now that you've learned about data normalization, you'll learn about data denormalization in the next lesson.
| Factor | Consideration |
| Performance | Heavy normalization can hurt read performance when queries need to join many tables together, each join adds work for the optimizer and the engine. Columnstore indexes, indexed views, or selective denormalization, covered in the next lesson, can offset this for read-heavy workloads. |
| Maintainability | Normalized tables are generally easier to maintain than wide, repetitive ones, since each table has fewer columns and a given fact only needs updating in one place. |
| Extensibility | Normalization tends to help extensibility rather than being neutral to it: adding a new attribute to a properly normalized design usually means adding a new table, or a nullable column to an existing one, without restructuring data that's already there. |
| Scalability | A normalized schema with many focused tables scales well with SQL Server 2025 features like table partitioning and read-scale availability replicas, since each table can be indexed, partitioned, and distributed independently. |
| Availability | A highly normalized database running very large, multi-table joins can compete for resources with other activity on the same server. Always On Availability Groups, read-only routing to secondary replicas, and Resource Governor workload groups all help isolate that impact. |
| Security | It's easier to apply security at the table level than at the column level, so normalizing by entity, putting salary information in its own table, say, makes it simpler to restrict access to a complete, sensitive object. Row-level security, covered in the previous lesson, now makes this less of an all-or-nothing choice than it used to be. |
Now that you've learned about data normalization, you'll learn about data denormalization in the next lesson.
Data Normalization - Exercise
Before moving on to the next lesson, click the Exercise link below to get some hands-on practice with data normalization.
Data Normalization - Exercise
Data Normalization - Exercise