| Lesson 6 | Modifying Databases |
| Objective | Modify an existing database in SQL Server 2025 |
Modifying Databases in SQL Server 2025
Modifying a database isn't a particularly common occurrence. A database created with room to grow dynamically, the way the previous lesson recommended, may never actually need to be altered by hand. Occasionally it still is, though, whether that's widening a file that's gotten tight, switching on fuller logging before a database goes into production, or adding a second file to spread data across another disk. The
ALTER DATABASE statement is what handles all of it.
Changing a Database's Collation
To change an existing database's default collation:
ALTER DATABASE SalesDB
COLLATE Latin1_General_CI_AS;
Resizing an Existing File
ALTER DATABASE's MODIFY FILE clause changes an existing file's size or growth settings:
ALTER DATABASE SalesDB
MODIFY FILE (
    NAME = N'SalesData',
    SIZE = 160MB,
    FILEGROWTH = 64MB
);
NAME here refers to the file's logical name, not its physical filename; the .mdf or .ldf extension is never included. One rule is worth internalizing before relying on this: MODIFY FILE's SIZE option can only grow a file, never shrink one. Running it with a SIZE smaller than the file's current size fails with an error rather than doing anything.
As a concrete example, suppose the
employee database from the previous lesson still has its transaction log at its original default size, 8 MB, and it needs more headroom. Since the database was created with default values, its log file's logical name is employee_log, matching the physical file employee_log.ldf minus the extension:
ALTER DATABASE employee
MODIFY FILE (NAME = employee_log, SIZE = 16MB);
MB unit suffix on SIZE is actually optional; a plain number is interpreted as megabytes if no unit is given.
Shrinking and Removing a File
Since
MODIFY FILE can't shrink a file, actually reducing one that's grown larger than it needs to be is a separate operation, DBCC SHRINKFILE:
DBCC SHRINKFILE (SalesArchiveData, 64);
SalesArchiveData file down to roughly 64 MB, reclaiming whatever space in it isn't actually holding data. Removing a file from a database entirely is a two-step process rather than one direct statement, because ALTER DATABASE's REMOVE FILE only works on a file that's already completely empty. DBCC SHRINKFILE's EMPTYFILE option migrates all of a file's data out to the other files in the same filegroup first:
DBCC SHRINKFILE (SalesArchiveData, EMPTYFILE);

ALTER DATABASE SalesDB
REMOVE FILE SalesArchiveData;
REMOVE FILE before the file is actually empty fails outright, which is part of why shrinking and removing a file is worth treating as a deliberate, two-step sequence rather than something to attempt in a single statement.
Adding a New File or Filegroup
Continuing the
A second data file and filegroup earns its complexity in a couple of recurring situations. Placing a new filegroup on a separate physical disk from the primary filegroup spreads I/O across more hardware, which can genuinely help performance on a busy database. Separately, and often more relevant for a course project like this one's running
SalesDB example from the previous lesson, adding a new filegroup and a secondary data file inside it looks like this:
ALTER DATABASE SalesDB
ADD FILEGROUP SalesArchive;

ALTER DATABASE SalesDB
ADD FILE
(
    NAME = N'SalesArchiveData',
    FILENAME = N'C:\SQLData\SalesArchive.ndf',
    SIZE = 128MB,
    MAXSIZE = 1024MB,
    FILEGROWTH = 64MB
)
TO FILEGROUP SalesArchive;
ADD pattern, just with ADD LOG FILE in place of ADD FILE, for the rare case where a database needs more than one log file, usually to spread log activity across additional disks on a heavily-used system.
A second data file and filegroup earns its complexity in a couple of recurring situations. Placing a new filegroup on a separate physical disk from the primary filegroup spreads I/O across more hardware, which can genuinely help performance on a busy database. Separately, and often more relevant for a course project like this one's running
SalesDB example, a dedicated filegroup like SalesArchive gives you somewhere deliberate to move older, rarely-queried data, keeping the primary filegroup smaller and faster to back up without actually deleting anything. Neither reason applies to every database; a small, lightly-used one is usually fine living entirely in its single default data file, and adding a second file without a concrete reason just adds something else to manage.
ALTER DATABASE: Files and Filegroups at a Glance
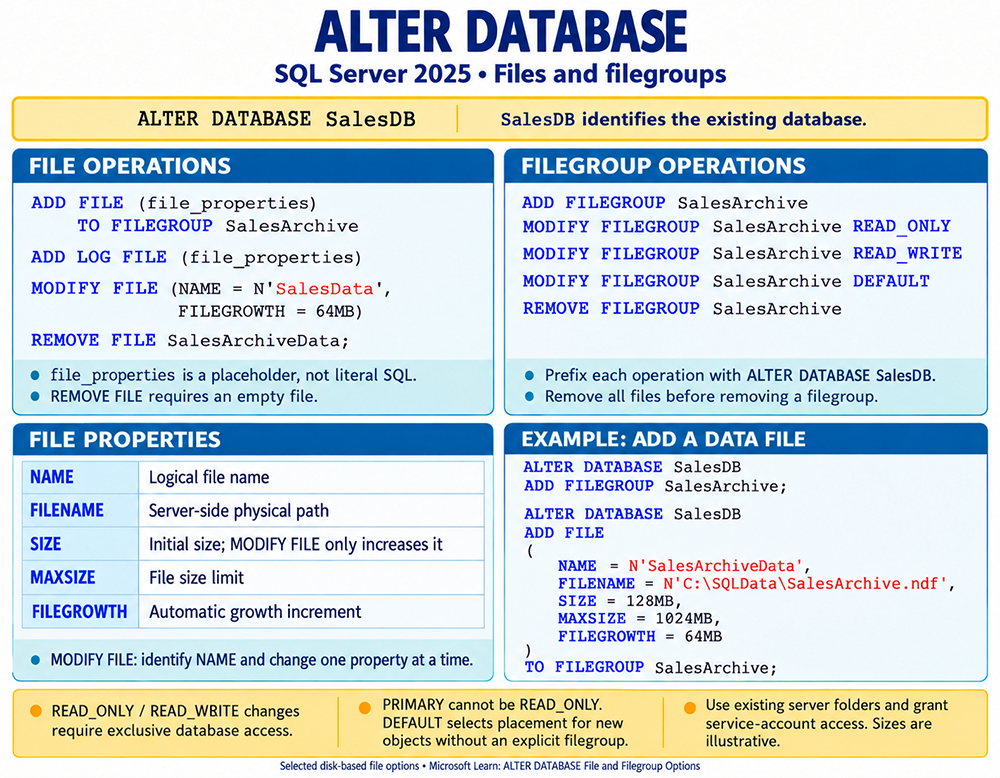
SQL Server 2025, files and filegroups
ALTER DATABASE SalesDB
SalesDB identifies the existing database.
File operations, each prefixed with
ALTER DATABASE SalesDB:
ADD FILE (file_properties)
    TO FILEGROUP SalesArchive

ADD LOG FILE (file_properties)

MODIFY FILE (NAME = N'SalesData',
            FILEGROWTH = 64MB)

REMOVE FILE SalesArchiveData;
file_propertiesis a placeholder, not literal SQL.REMOVE FILErequires an empty file.
ALTER DATABASE SalesDB:
ADD FILEGROUP SalesArchive
MODIFY FILEGROUP SalesArchive READ_ONLY
MODIFY FILEGROUP SalesArchive READ_WRITE
MODIFY FILEGROUP SalesArchive DEFAULT
REMOVE FILEGROUP SalesArchive
- Prefix each operation with
ALTER DATABASE SalesDB. - Remove all files before removing a filegroup.
| Property | Description |
NAME | Logical file name |
FILENAME | Server-side physical path |
SIZE | Initial size; MODIFY FILE only increases it |
MAXSIZE | File size limit |
FILEGROWTH | Automatic growth increment |
MODIFY FILE: identify NAME and change one property at a time.
Example: add a data file
ALTER DATABASE SalesDB
ADD FILEGROUP SalesArchive;

ALTER DATABASE SalesDB
ADD FILE
(
    NAME = N'SalesArchiveData',
    FILENAME = N'C:\SQLData\SalesArchive.ndf',
    SIZE = 128MB,
    MAXSIZE = 1024MB,
    FILEGROWTH = 64MB
)
TO FILEGROUP SalesArchive;
READ_ONLY/READ_WRITEchanges require exclusive database access.PRIMARYcannot beREAD_ONLY.DEFAULTselects placement for new objects without an explicit filegroup.- Use existing server folders and grant service-account access. Sizes are illustrative.
Changing the Recovery Model
A database's recovery model controls how much the transaction log retains and what kind of restore options it supports. Switching to the fullest level of logging:
ALTER DATABASE SalesDB
SET RECOVERY FULL;
FULL, every operation is logged in enough detail to support point-in-time restores; under SIMPLE, the log is truncated automatically and point-in-time restore isn't available. The specific tradeoffs between recovery models belong to a later course on backup and recovery; what matters here is that switching between them is itself just another ALTER DATABASE ... SET statement, no different in form from setting the recovery model shown in an earlier lesson in this module.
Other Common ALTER DATABASE SET Options
Beyond files, filegroups, collation, and the recovery model,
One more option is worth knowing mainly so it can be avoided:
ALTER DATABASE's SET clause controls a handful of other database-wide states worth knowing by name.
SINGLE_USER and MULTI_USER switch how many connections a database accepts at once:
ALTER DATABASE SalesDB
SET SINGLE_USER WITH ROLLBACK IMMEDIATE;

ALTER DATABASE SalesDB
SET MULTI_USER;
SINGLE_USER is exactly the kind of exclusive access the collation change earlier in this lesson sometimes requires: it limits the database to one connection at a time, and WITH ROLLBACK IMMEDIATE forcibly rolls back any other transactions already in progress rather than waiting for them to finish on their own. MULTI_USER reverses it, returning the database to its normal, multi-connection state once the maintenance that needed exclusive access is done.
ONLINE and OFFLINE control whether a database is reachable at all:
ALTER DATABASE SalesDB SET OFFLINE;
ALTER DATABASE SalesDB SET ONLINE;
READ_ONLY and READ_WRITE are also available at the whole-database level, not just the filegroup level covered earlier:
ALTER DATABASE SalesDB SET READ_ONLY;
ALTER DATABASE SalesDB SET READ_WRITE;
READ_ONLY setting is a common choice for an archive database that's done accepting new data but still needs to be queried.
One more option is worth knowing mainly so it can be avoided:
AUTO_SHRINK. Setting ALTER DATABASE SalesDB SET AUTO_SHRINK ON; lets SQL Server automatically shrink a database's files periodically on its own. It sounds convenient, but it runs on a schedule you don't control, competes with real workloads for I/O while it runs, and tends to just let the files grow right back the next time data is added, fragmenting them in the process. Leaving AUTO_SHRINK off, the default, and shrinking a file deliberately with DBCC SHRINKFILE only when there's a specific reason to, is the generally recommended approach instead.
Confirming a Change Took Effect
After running an
ALTER DATABASE statement, it's worth confirming the change actually took, the same habit worth having after CREATE DATABASE. sys.master_files reports the current size, growth setting, and path for every file on the instance:
SELECT name, size * 8 / 1024 AS SizeMB, is_percent_growth, growth
FROM sys.master_files
WHERE database_id = DB_ID('SalesDB');
sys.master_files' own size and growth columns are recorded in 8-kilobyte pages rather than megabytes directly, which is why the query above multiplies by 8 and divides by 1024 to convert back into a more readable MB figure. For the database's collation or recovery model specifically, sys.databases is the quicker lookup:
SELECT name, collation_name, recovery_model_desc
FROM sys.databases
WHERE name = 'SalesDB';
Putting It Together: A Maintenance Scenario
Individually, each statement covered above is simple. Realistically, though, a single maintenance task often needs several of them run together, in a specific order. Suppose
SalesDB needs its collation changed, something earlier in this lesson noted can fail against active connections or dependent objects. A complete, careful version of that change looks like this:
ALTER DATABASE SalesDB
SET SINGLE_USER WITH ROLLBACK IMMEDIATE;

ALTER DATABASE SalesDB
COLLATE Latin1_General_CI_AS;

ALTER DATABASE SalesDB
SET MULTI_USER;

SELECT name, collation_name
FROM sys.databases
WHERE name = 'SalesDB';
SINGLE_USER first clears the path for the collation change by forcing out any other connections; the collation change itself runs with nothing else competing for the database; MULTI_USER reopens it for everyone else once the change is done; and the final query confirms the new collation actually took effect rather than assuming it did. That same shape, isolate, change, reopen, verify, applies just as well to several of the other changes covered in this lesson, not only collation, whenever a change needs exclusive access to go through cleanly.
Permissions and Caution
As the earlier lesson on database permissions covered, modifying a database requires the
ALTER permission on it, membership in its db_owner role, or broader server-level rights such as sysadmin. Beyond simply having permission, it's worth treating any of these changes with real caution: altering collation, file layout, or the recovery model can affect performance, backup strategy, and data integrity all at once. Testing a change in a non-production environment first, and backing up the database beforehand, is worth the extra step before running one of these statements against a database anyone actually depends on. The effectiveness and impact of a given change also depends on the specific database's setup, current usage, and the wider SQL Server environment it runs in, so what's safe on one server isn't automatically safe on another.
ALTER DATABASE Categories at a Glance
This lesson has covered a fair amount of ground under one statement. Before moving on, it helps to see the categories lined up together:
Every one of these shares the same basic shape:
| Category | Example |
| Collation | ALTER DATABASE SalesDB COLLATE Latin1_General_CI_AS; |
| Files | MODIFY FILE, ADD FILE, ADD LOG FILE, REMOVE FILE |
| Filegroups | ADD FILEGROUP, MODIFY FILEGROUP ... READ_ONLY / READ_WRITE / DEFAULT, REMOVE FILEGROUP |
| Recovery model | SET RECOVERY FULL / SIMPLE |
| Access and state | SET SINGLE_USER / MULTI_USER, SET ONLINE / OFFLINE, SET READ_ONLY / READ_WRITE |
Every one of these shares the same basic shape:
ALTER DATABASE, the database's name, and then whatever specific change you're making. Once that pattern is familiar, looking up the exact syntax for a category you don't use often is usually all that's left to do.
What's Ahead
The next lesson covers the remaining operation in this module's trio: deleting a database entirely. It's also time to begin the course project; the Exercise link below has you write the Transact-SQL statements that create and modify the database you'll build on for the rest of the course.