| Lesson 2 | Introduction to Fast-Start recovery |
| Objective | Identify advantages and components of Fast-Start recovery. |
Fast-Start Recovery Components in Oracle 26ai
Fast-Start recovery helps Oracle return consistent data to service after an instance failure. Its central components are incremental checkpointing, on-demand rollback, and parallel transaction rollback. They address different parts of the recovery workload: reducing the changes that must be reconstructed, making required blocks available, and undoing unfinished work efficiently. Together, they improve availability while preserving transaction consistency.
Oracle AI Database 26ai continues to document Fast-Start Fault Recovery and also provides the separately named Oracle RAC Fast Restart Recovery enhancement. Understanding their roles prevents a common mistake: treating database recovery, application reconnection, and standby failover as one feature controlled by one parameter. This lesson explains the components, their advantages, and the evidence an administrator uses to assess them.
Database Instances and the Meaning of Recovery
An Oracle instance contains memory structures and processes. Database files hold persistent data, redo, and structural information. In a single-instance deployment, one instance manages the database. Oracle Real Application Clusters (RAC) allows multiple instances to access the shared database. RAC superseded the historical Oracle Parallel Server architecture; current recovery planning should use RAC concepts rather than obsolete OPS configuration instructions.
A crash can discard memory without destroying the persistent files. In that case, Oracle can reconstruct changes from the required online redo and undo unfinished transactions. If one or more RAC instances fail while another survives, a surviving instance performs instance recovery automatically. If a single-instance database or all RAC instances crash, crash recovery occurs at the next startup. These mechanisms assume the necessary files and redo remain available.
Losing a datafile or required storage introduces a different problem. The missing content may need to be restored and recovered through RMAN. Faster checkpointing cannot recreate a destroyed disk or replace independent backups. Diagnose the failure before selecting a procedure, and distinguish a failed instance from a damaged database file.
Two Recovery Phases: Redo, Then Undo
Cache recovery, also called rolling forward, applies the relevant redo records to affected data blocks. Redo describes changes; its recovery use is not limited to transactions that eventually committed. Reconstructing database state can therefore involve both committed and uncommitted changes. The checkpoint position identifies where the necessary recovery work begins.
Transaction recovery, also called rolling back, removes changes made by transactions that were uncommitted when the failure occurred. Undo information supplies the earlier values needed for this work. A block already written to a datafile can contain an uncommitted change, while a committed change may still need reconstruction from redo. Physical persistence and transaction commitment are separate concepts.
For example, imagine two sessions updating different customer records. Session A commits before the crash, but its modified data block has not yet been written to the datafile. Session B has not committed, although its block has already reached disk. Recovery preserves A's committed update by applying the needed redo and removes B's unfinished update using undo. The final result follows transaction state, not which block was written first.
Oracle can open the database after cache recovery completes while transaction recovery continues. Access to a block affected by unfinished work can still require recovery processing. Consequently, database open time, completion of background rollback, and full application responsiveness are different milestones. Measure each milestone that matters to the workload.
1. Incremental Checkpointing
Checkpointing advances the position from which instance recovery must reconstruct changes.[1] Database writer processes, commonly described as DBWR or DBWn, write dirty buffers from memory to datafiles. The checkpoint process coordinates and records checkpoint information. Log writer (LGWR) writes redo records to online redo logs. These responsibilities work together, but the buffer cache is not copied into the redo logs.
Fast-Start checkpointing advances recovery progress incrementally. Writing older modified buffers helps advance the checkpoint position, limiting outstanding recovery work instead of relying solely on large, event-driven batches. The aim is to manage the amount of redo processing and block reconstruction that would be required if the instance failed.
This creates a performance tradeoff. A more demanding recovery target can require more checkpoint-related writes during normal operation. On a busy update workload, insufficient storage bandwidth may make those writes compete with application I/O. Reducing expected crash-recovery work is useful, but it does not automatically reduce all normal I/O or improve every application's throughput.
The checkpoint is also unrelated to the time of the last backup. A backup supplies recoverable historical content; a checkpoint records progress in persisting current database changes. Advancing the checkpoint can shorten instance recovery even when the backup schedule is unchanged. Both mechanisms are needed for their respective failure scenarios.
| Effect | What it means |
|---|---|
| Less outstanding recovery work | A later checkpoint position reduces changes that must be reconstructed after an instance failure. |
| Incremental progress | Background writes advance the checkpoint rather than concentrating all progress at log switches. |
| More normal write activity | A shorter target can increase checkpoint-related datafile I/O. |
| Continued backup requirement | Checkpoints do not supply an independent copy after media or site loss. |
2. On-Demand Rollback
On-demand rollback helps new work obtain the blocks it needs without waiting for every terminated transaction to finish recovering. When a session needs an affected block, Oracle performs the necessary transaction recovery for that access while background recovery continues processing other work.
Suppose a failed batch transaction modified many inventory records. A new order needs one of the affected records. Recovering the relevant block can allow that order to progress sooner than waiting for the entire batch's rollback. The advantage concerns the availability of needed data, not retaining the failed transaction's uncommitted updates.
On-demand recovery does not promise that every request finishes immediately. A request can still wait for recovery or other resources. A useful assessment therefore includes the first successful application operations after reopening, particularly operations that touch data changed by the failed transaction. Testing only an unrelated table can miss the delays users actually encounter.
3. Parallel Transaction Rollback
Parallel rollback uses multiple recovery workers to undo terminated transactions where parallel transaction recovery applies. It can reduce the elapsed time needed to recover eligible large workloads, especially unfinished parallel DML or DDL operations. The benefit depends on the work available to parallelize and the resources needed to complete it.
The FAST_START_PARALLEL_ROLLBACK parameter controls the permitted degree of parallelism. Oracle 26ai documents FALSE, LOW, and HIGH, with LOW as the default. LOW limits the maximum degree to twice CPU_COUNT; HIGH limits it to four times CPU_COUNT. These are limits, not promises that a particular number of workers will be active or that doubling the limit halves recovery time.
Changing this parameter stops and restarts transaction recovery with the new implied degree. Treat a change during active recovery as an operational decision, supported by monitoring and workload evidence. Increasing concurrency may increase resource pressure on the application workload already running. The later parallel-rollback lesson develops the configuration and monitoring details.
On-demand and parallel rollback complement each other. On-demand processing addresses a requesting session's immediate need, while parallel background recovery addresses eligible unfinished work more broadly. Neither component replaces cache recovery, and neither should be described as restoring lost files from a backup.
Read the Modern Recovery Diagram
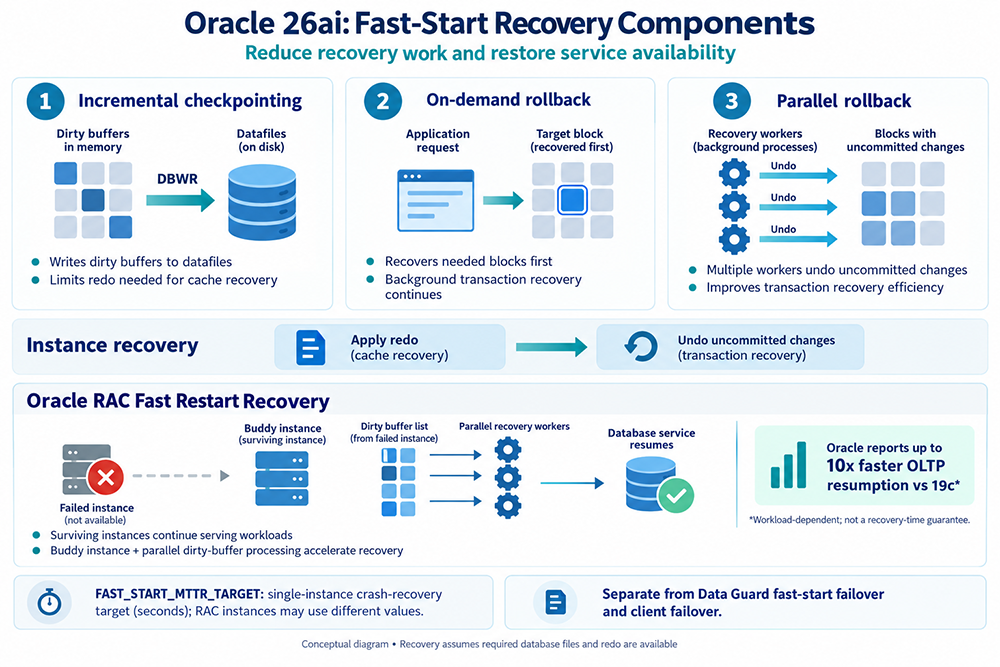
The three upper panels summarize complementary components rather than three mandatory sequential commands. The central strip shows the redo-and-undo relationship. The lower RAC panel adds a cluster recovery enhancement, while the bottom notes distinguish the recovery target from other similarly named availability features.
| Component | Primary advantage | Boundary |
|---|---|---|
| Incremental checkpointing | Limits outstanding cache recovery work. | Requires normal datafile writes and available redo. |
| On-demand rollback | Prioritizes recovery needed for accessed blocks. | Does not make every application request instantaneous. |
| Parallel rollback | Uses workers for eligible transaction recovery. | Benefits depend on workload and resources. |
| RAC Fast Restart Recovery | Accelerates return to productive service. | Its reported speedup is not a universal guarantee. |
What FAST_START_MTTR_TARGET Controls
FAST_START_MTTR_TARGET expresses a target, in seconds, for single-instance crash recovery. Oracle manages incremental checkpoint writes in an attempt to meet a practical startup and cache-recovery target. The documented range is 0 through 3600 seconds. The parameter can be changed at runtime, is not modifiable in a PDB, and RAC instances may use different values.
A positive target must be achievable on the actual system. Startup overhead, storage performance, redo volume, and the update workload affect the practical range. A very small configured number cannot eliminate fixed startup costs. Inspect the effective target and current estimate, then compare them with representative recovery tests before changing the configuration.
Zero is the documented default; it should not be presented as a command that universally enables Fast-Start recovery or guarantees immediate recovery. Database recovery and checkpoint mechanisms still have other operating conditions. Oracle's tuning guide uses positive targets when describing target-based checkpoint management and explains the effect of other checkpoint-related parameters.
Review overlapping settings such as LOG_CHECKPOINT_INTERVAL and LOG_CHECKPOINT_TIMEOUT against that guide. They can interfere with the mechanism used to meet the MTTR target. Do not copy an older parameter list into a modern system without establishing its actual purpose and interaction. The next lesson examines checkpointing in greater detail.
Finally, this parameter does not define the complete business outage. Failure detection, instance or host restart, service placement, client reconnection, transaction cleanup, and application checks contribute additional time. A recovery-time objective for the business requires measured service behavior beyond a single database estimate.
Oracle RAC Fast Restart Recovery in 26ai
Oracle describes RAC Fast Restart Recovery as shortening the interval between an instance crash or restart and a fully productive database. Its facilitating mechanisms include a predefined recovery instance, called a buddy instance, and parallel processing of the dirty-buffer list. Workload can continue across the remaining instances while recovery proceeds.
Oracle reports that affected OLTP applications can resume work up to ten times faster than with Oracle Database 19c. This is a qualified product comparison, not a promise for every cluster, incident, or transaction. Identify the tested service milestone, workload, and environment when evaluating the enhancement. The buddy instance should not be mistaken for a separate Data Guard standby database.
Do not describe FAST_START_MTTR_TARGET as a switch for this enhancement. The single-instance target parameter, transaction rollback controls, and RAC recovery optimizations have distinct documented roles. When planning a cluster upgrade, use supported release configuration and measure the return to useful application service under realistic workload conditions.
The diagram highlights the direction of the availability improvement without prescribing a manual recovery script. Administrators still need working shared storage, surviving capacity, service configuration, and an application connection strategy. Loss of all database storage requires an appropriate media or disaster recovery plan.
Client Failover and Standby Failover Have Separate Roles
Transparent Application Failover (TAF) concerns reconnecting supported clients after a connection or instance failure. Oracle documents service-based failover configuration and client connect-descriptor settings where applicable. It is not enabled by an ALTER SYSTEM SET FAILOVER_METHOD = TAF statement. Service and client capabilities determine what connection state can be restored.
Reconnection also does not imply automatic replay of every interrupted transaction. Application Continuity and Transparent Application Continuity address supported request replay under their own prerequisites. An application must handle uncertain outcomes appropriately and avoid blindly repeating a transaction that may already have committed.
Data Guard fast-start failover is another mechanism: the broker can automatically transition an eligible standby into the primary role. That changes database roles rather than merely recovering a failed RAC instance. A complete availability design may combine database recovery and client handling, but testing one does not prove the others.
Observe Recovery Without Inventing Results
The following queries are illustrative read-only checks for an administrator with the required privileges and correct container context. They are not output from an actual recovery performed for this lesson.
SELECT target_mttr, estimated_mttr
FROM v$instance_recovery;

SELECT usn, slt, seq, state,
       undoblocksdone, undoblockstotal
FROM v$fast_start_transactions;

SELECT pid, state, undoblocksdone
FROM v$fast_start_servers;
V$INSTANCE_RECOVERY distinguishes the effective MTTR target from the estimate based on current recovery work. A brief increase after a heavy update burst deserves interpretation over time. It is not automatically evidence that recovery configuration has failed.
V$FAST_START_TRANSACTIONS reports progress for transactions recovered in parallel. It does not show serial transaction recovery. V$FAST_START_SERVERS describes the workers performing parallel transaction recovery. An empty transaction view therefore cannot, by itself, prove that all recovery activity has completed. Correlate the views with diagnostic records and observed application behavior.
For RAC observations, consider which instance produced the values. Use the appropriate global views and instance identification when the question spans the cluster. Capture timestamps and workload context so comparisons refer to the same incident and recovery milestone.
Assess the Advantages with a Controlled Exercise
In a designated test environment, define representative committed and unfinished work, the failure scenario, and the expected business result. Record the starting configuration and storage conditions. Measure startup or surviving-instance recovery, first useful service response, affected-block access, and remaining transaction cleanup. Use an approved test procedure rather than deliberately crashing production to obtain a sample.
Compare results under similar loads. Faster startup with severely degraded application response may not satisfy the objective. Preserve logs and observations, reconcile committed outcomes, and document any client retry or service configuration issues. This turns a recovery feature into demonstrated availability rather than an assumed guarantee.
Historical course materials grouped checkpointing, on-demand rollback, and parallel rollback under Fast-Start Fault Recovery. Those concepts remain useful in Oracle 26ai. Current documentation and observed behavior provide the basis for applying them, while new RAC enhancements add further opportunities to reduce disruption.
Continue with understanding Fast-Start checkpointing to examine checkpoint progress and recovery-performance tradeoffs.
Oracle 26ai References
- Fast-Start Fault Recovery and instance recovery tuning
- FAST_START_MTTR_TARGET and FAST_START_PARALLEL_ROLLBACK
- Oracle RAC Fast Restart Recovery explanation and performance claims
- Transparent Application Failover configuration
- Parallel transaction recovery progress and recovery workers