| Lesson 11 | Connection with a database link |
| Objective | Establish connections over database links. |
Using Oracle 26ai Database Links
After a database link has been created, SQL can use it to reference an object in another database. In Oracle AI Database 26ai, this makes it possible to retrieve remote rows, combine information from several sites, and coordinate changes across databases. The familiar SQL syntax can hide much of the connection detail, but it does not remove network dependencies, authentication requirements, or transaction boundaries.
This lesson assumes that the required links already exist and that their remote identities have appropriate object privileges. It builds on the preceding database-link creation lesson. All table definitions, identifiers, and values below are illustrative. Use a dedicated lab session and matching test schemas before trying the update examples; the examples have not been executed against a live database.
Follow the connection from local to remote
A database link is a schema object in the originating database. When a statement uses the link, the local database acts as a client of the remote database. The application can remain connected to the local database while that database establishes the remote connection on its behalf. The link does not create a reverse link automatically.
For example, employees@hrdb_link identifies an employees object reached through the database link named hrdb_link. The link name is not necessarily a host name or Oracle Net service alias. Its definition supplies the remote connection information and determines how the remote identity is established. A fixed-user link, for example, uses its configured remote account rather than automatically using the application's login identity.
Connection naming is evaluated in the environment of the database server using the link. A workstation's working tnsnames.ora entry does not prove that the database server can resolve the same destination. Likewise, reaching the local database says nothing by itself about the network route from that database to a remote service.
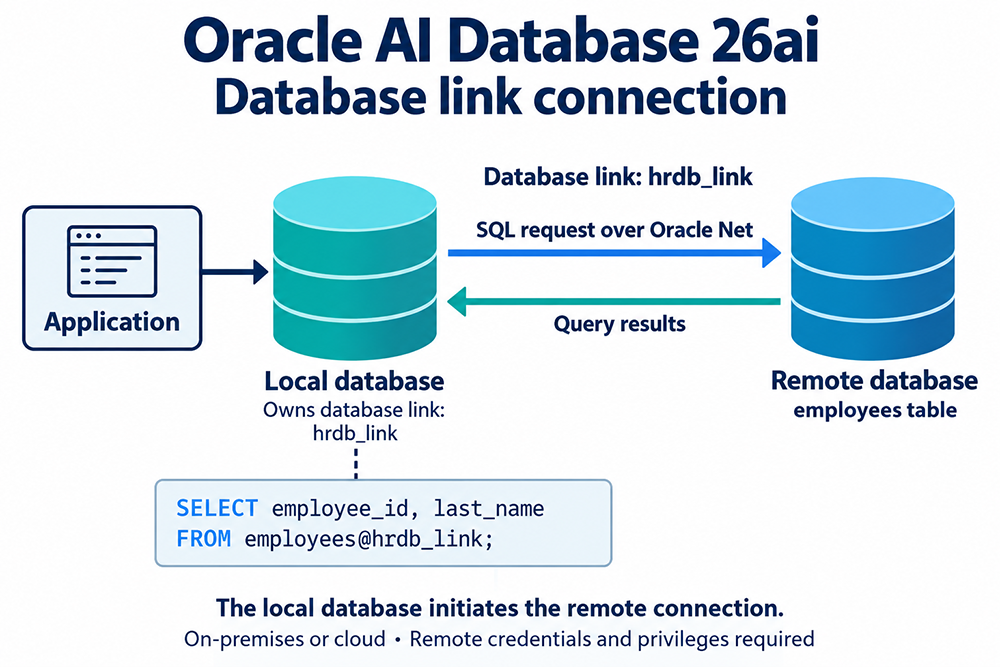
The diagram shows a logical request and response, not a new physical database containing both sites. Each database continues to manage its own objects and permissions. A link supplies access to those objects; it does not copy them into local storage or keep a local replica automatically.
Start with a remote query
Use a small query to verify the intended remote object and columns. The following matches the first diagram:
SELECT employee_id, last_name
FROM employees@hrdb_link;
For a larger table, restrict the test to a known row or a small set:
SELECT employee_id, last_name
FROM employees@hrdb_link
WHERE employee_id = 100;
The second query can succeed while returning no rows, so distinguish successful execution from a particular expected result. Confirm the schema and test data before deciding that an empty result indicates a connection problem. If the table belongs to another schema, use the appropriate qualified object name and ensure the remote identity can access it.
A remote query accesses objects at a remote database. A distributed query can combine data from multiple databases in one statement. These describe where data is accessed, not an exhaustive list of transaction types. Database links also support remote data modification and other documented operations. Oracle explains the object-reference syntax and restrictions in its Distributed Queries reference.
Successful name resolution or a successful TNSPING test is only part of the evidence. Executing the intended query additionally tests the connection, authentication, object resolution, and relevant access privileges. Keep the exact error text if it fails; replacing it with “the link is broken” discards information needed for diagnosis.
Combine data from two sites
Suppose an orders table is available through raleigh and an inventory table through rochester. A distributed query can join them using their shared item identifier:
SELECT o.order_id,
       o.item_id,
       i.quantity_on_hand
FROM orders@raleigh o
JOIN item@rochester i ON i.item_id = o.item_id
WHERE o.order_id = 5001;
This example assumes compatible item identifiers and suitable remote privileges at both sites. It uses explicit columns and a selective condition rather than fetching every column and row. The SQL aliases o and i are table aliases within the statement; they do not create additional database links.
Network cost matters even when the syntax resembles a local join. Execution can involve transferring intermediate data between sites. Oracle's optimizer determines the execution strategy, so do not infer the exact movement of every row from the textual order of the tables. Examine the execution plan and actual workload before choosing a tuning technique.
For a learning exercise, validate each remote query separately, then add the join. If one site is unavailable, the combined statement cannot provide the intended result merely because the other site is healthy. This incremental approach separates connection and object-access errors from join conditions and data-quality problems.
Define the transaction before making changes
A distributed transaction changes data at multiple database nodes as one unit of work. A statement that modifies only one remote database does not by itself establish that several nodes are being updated. In the following example, the intended unit is explicit: reduce inventory at Rochester and create the corresponding order at Raleigh.
Both changes must belong to the same session transaction. Committing the inventory update before inserting the order would split the business operation into two transactions. Per-statement autocommit in a client application would cause a similar problem. Configure the client so the intended unit remains pending until the application deliberately commits or rolls it back.
PL/SQL is useful for expressing the conditional logic, but a procedure or trigger is not required for distributed updates. Several SQL statements in the same transaction can involve several databases. A PL/SQL BEGIN ... END block also does not commit automatically simply because it reaches its end.
Assume item_id uniquely identifies an inventory row and quantity_on_hand is numeric. The example order table has columns named order_id, item_id, and quantity. Choose an unused order identifier in the lab. The table is named orders because ORDER is a SQL keyword and should not be introduced as an unquoted example table name.
BEGIN
  UPDATE item@rochester
  SET quantity_on_hand = quantity_on_hand - 1
  WHERE item_id = 12345
    AND quantity_on_hand >= 1;

  IF SQL%ROWCOUNT <> 1 THEN
    RAISE_APPLICATION_ERROR(
      -20001, 'Item missing or insufficient stock'
    );
  END IF;

  INSERT INTO orders@raleigh (order_id, item_id, quantity)
  VALUES (5001, 12345, 1);
EXCEPTION
  WHEN OTHERS THEN
    ROLLBACK;
    RAISE;
END;
/
The conditional update avoids subtracting from a row with insufficient stock. Immediately checking SQL%ROWCOUNT distinguishes one updated row from a missing item or unsuccessful stock condition. The exception handler rolls back the pending transaction and re-raises the error if the block fails. This is a deliberately self-contained lab example, not a reusable routine that preserves arbitrary caller work.
Use a session with no unrelated pending changes: the ROLLBACK applies to the session's transaction, not only the inventory statement. The slash is a SQL*Plus-style execution command for the block, not part of the PL/SQL sent through an application API.
Only after the block succeeds, issue the following in the same session:
COMMIT;If the block reports an error, stop and investigate rather than allowing a script to continue blindly to COMMIT. If you choose not to keep a successful lab change, use ROLLBACK before committing. A later failure during COMMIT is a different condition: its outcome can require distributed-transaction diagnosis rather than a simple assumption that nothing happened.
Understand the two-phase commit
Oracle coordinates a distributed transaction so the participating changes reach a consistent outcome. The database where the transaction originates acts as the global coordinator. Oracle selects a commit point site using commit point strength; this role is not determined by which database appears first in a SQL statement.
- Prepare: the coordinator requests readiness from participating nodes other than the commit point site. A prepared updating participant retains the information and locks needed to complete the agreed outcome.
- Commit: the commit point site commits first, and the remaining sites follow that outcome. The commit point site does not itself enter the prepared state.
If preparation cannot succeed, the transaction is rolled back. Successful coordination does not mean every disk write happens simultaneously. Read-only branches can also avoid unnecessary work, so a simple remote SELECT should not be described as always executing the full updating sequence. See Oracle's distributed transaction concepts for the protocol details.
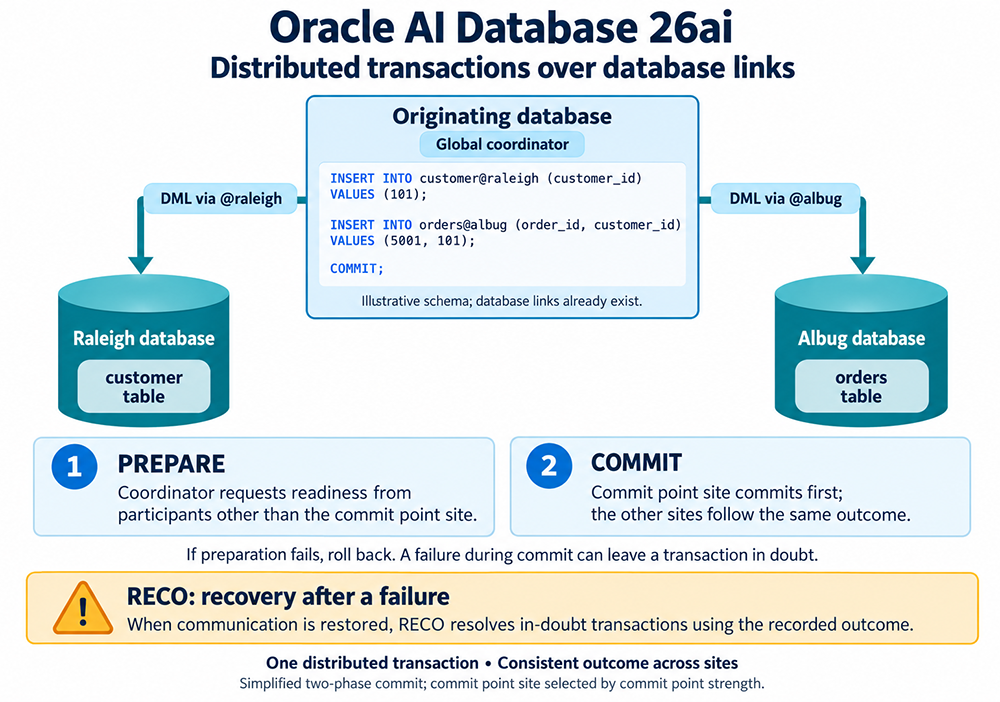
The diagram uses a different illustrative schema from the inventory example. Its SQL is:
INSERT INTO customer@raleigh (customer_id)
VALUES (101);

INSERT INTO orders@albug (order_id, customer_id)
VALUES (5001, 101);

COMMIT;
This abbreviated sequence assumes both inserts succeed and the client does not commit between them. Real application code must check for errors and roll back the intended unit if either insert fails before commit. Do not append these statements to the inventory example as though the two examples shared one table definition. Matching customer identifiers also do not automatically establish an enforced foreign key across databases.
Separate RECO recovery from normal coordination
A network or instance failure during distributed commit can leave a transaction in doubt at a participating site. RECO is the recovery background process that works to resolve such transactions when communication and recovery permit. It is not the process that routes every remote SQL statement or normally coordinates the application's work.
Prepared branches may retain locks until the outcome is resolved. A DBA can examine DBA_2PC_PENDING and DBA_2PC_NEIGHBORS with appropriate privileges. Record transaction identifiers and coordinate investigation across affected sites. Oracle's distributed transaction management guide describes this recovery work.
Do not treat a client timeout as proof of rollback. The database might have committed while the acknowledgment failed to reach the client. Repeating an insert or subtracting inventory again could duplicate business work. Before retrying an uncertain operation, establish its outcome through the application's recovery design and DBA evidence. Forced resolution is an exceptional administrative decision, not the routine response taught by this example.
Use a synonym for location transparency
A synonym supplies an alternative name for an object reference. In the intended local schema, an authorized user can create a private synonym:
CREATE SYNONYM remote_item FOR item@rochester;Queries in that context can then use the shorter name:
SELECT item_id, quantity_on_hand
FROM remote_item
WHERE item_id = 12345;
The synonym does not store inventory rows, grant remote privileges, or remove the link dependency. A public synonym requires its own creation privilege and broader naming consideration; it is not necessary for this example. Making a synonym public also does not automatically make a private link usable by every account. See CREATE SYNONYM for access and name-resolution rules.
Create this setup object separately from the distributed DML exercise. DDL has implicit commit behavior, so inserting synonym creation into pending application work can change its transaction boundary. Keep setup, testing, and transaction execution as distinct steps. Oracle's COMMIT reference explains the relevant transaction behavior.
Apply the model to cloud deployments
Cloud hosting does not change the need to identify the originating database, remote service, remote identity, and allowed network path. A cross-region connection must satisfy the relevant connectivity and security configuration. Do not assume that creating a link automatically enables routing, opens network access, or encrypts traffic.
Autonomous AI Database supports documented database-link workflows, including DBMS_CLOUD_ADMIN.CREATE_DATABASE_LINK. Its credential, target, and networking requirements depend on the service and deployment. It is therefore incorrect to state that Autonomous Database generally requires REST or GoldenGate instead of database links. Consult the applicable Autonomous database-link procedure documentation when using that platform.
Use the authentication and transport configuration approved for your environment. Keep credentials out of lesson scripts and diagnostic records. Do not use undocumented password representations as a supposed wallet setup, and do not assume that application replay features cover every distributed transaction scenario without checking their documented restrictions.
Test a connection and its transaction behavior
Start with the smallest read-only test that answers the connection question, then increase complexity. A useful test record identifies the local database and schema, the link used, the remote object, and the exact statement. Include the time and complete error message, but no passwords. This helps a DBA reproduce the failure without confusing workstation connectivity with the database server's outgoing connection.
For the update lab, record the starting inventory and whether the chosen order identifier already exists. Run the block once, confirm its success, and choose explicitly whether to commit or roll back. Inspect the corresponding business rows afterward through an authorized connection. A rollback test should leave neither the new order nor the inventory decrement committed; a successful commit test should retain both intended changes.
Also test an ordinary pre-commit error, such as an existing order identifier, in an isolated lab. Confirm that the error is reported and that the pending inventory change is rolled back. This tests application error handling without deliberately disrupting database connectivity or forcing an in-doubt transaction. Recovery testing requires a separate controlled plan.
- Check access context: confirm the local schema can resolve the intended link.
- Check the remote destination: verify the service and network path used by the database server.
- Check object access: execute a narrow query using the expected remote identity and columns.
- Check transaction boundaries: ensure related updates share one transaction and autocommit does not split them.
- Check uncertain outcomes: investigate commit failures before retrying business changes.
The module conclusion brings these ideas together with naming, listeners, and process-level connections. Database links extend that architecture by allowing a database to become a client of another service while keeping the application's access expressed in SQL.