| Lesson 2 | Oracle Data Pump functions and use cases |
| Objective | Describe the functions, uses, and limitations of Data Pump Export and Import. |
Oracle Data Pump Utility Overview
Oracle Data Pump Export and Import move logical data and metadata between Oracle databases. Export starts a server-side job that unloads selected database objects, object definitions, and optional table data. Import reads that logical representation and creates, loads, filters, remaps, or transforms supported objects in a target database. In Oracle AI Database 26ai, the command-line clients are expdp and impdp.
A Data Pump dump file is not a general-purpose database backup. It can move an application schema, copy selected tables, preserve metadata before a deployment, populate a test PDB, or help migrate compatible data. It does not preserve the physical files and recovery history required to restore a damaged database.
Lesson 1 introduced that logical-versus-physical distinction. This lesson applies it by examining the actual functions of Export and Import, the server-side architecture behind a job, and the operational problems for which Data Pump is appropriate. The goal is to choose Data Pump because the unit of work is a logical object or data set—not simply because a file containing database information is being created.
What Data Pump Export Captures
The expdp client starts and controls a Data Pump Export job. Depending on the selected mode and parameters, the job can write table rows and metadata describing tables, indexes, constraints, grants, views, stored program units, and other supported objects to a dump file set. The associated log records progress, messages, and errors and must be reviewed before an export is considered successful.
Export mode defines the initial scope of the job:
- Full mode processes the supported objects available to a full-mode operation in the connected database or PDB.
- Schema mode exports the supported objects owned by one or more schemas.
- Table mode selects named tables, partitions, and eligible dependent objects.
- Tablespace mode selects tables whose storage belongs to specified tablespaces, subject to documented restrictions.
- Transportable mode exports structural metadata while table data remains in data files that are moved separately.
Parameters refine that scope. CONTENT=METADATA_ONLY records object definitions without table rows, which can provide a useful deployment or
environment-creation baseline. CONTENT=DATA_ONLY omits object-creation metadata. INCLUDE and EXCLUDE select object types,
while QUERY can restrict exported rows. These controls make Data Pump far more selective than a physical backup.
A full-mode export is still a logical export. In a PDB, it is scoped to that connected PDB; it does not export every PDB in the CDB. It also does
not capture the database files, control file, SPFILE, online redo, or archived redo needed for media recovery. Therefore, neither FULL=YES nor
the phrase "full export" should be interpreted as complete physical protection.
What Data Pump Import Can Do
The impdp client starts and controls a Data Pump Import job. Import reads a compatible Data Pump dump file set, or it obtains data through a
supported network-link operation. It then processes the requested logical objects in the target database. Depending on privileges, parameters, and target
conditions, Import can create object definitions, load table rows, rebuild indexes, apply grants, or select only part of the exported material.
Import is not limited to reproducing the source names and storage choices. Parameters such as REMAP_SCHEMA, REMAP_TABLESPACE,
REMAP_TABLE, and TRANSFORM can adjust selected metadata for the destination. This supports tasks such as moving an application to a
different owner, placing imported segments in a new tablespace, changing selected storage attributes, or loading a copy under a new table name.
With SQLFILE, Import writes the DDL it would issue to a SQL file instead of executing it. A DBA can review planned object creation and revise
the import design before changing the target. Editing this review artifact does not modify the dump file.
When an object already exists, TABLE_EXISTS_ACTION requires planning. Skipping, appending, truncating, or replacing a table can produce very
different results for dependent objects and existing rows. Begin with a target inventory and a tested rule for conflicts; impdp is not an
automatic reversal of expdp.
Logical Movement and Physical Protection
The following diagram replaces six legacy images that combined Data Pump transportation with unrelated claims about fragmentation, file restoration, and corrupt-block repair. The revised diagram keeps logical movement in the Data Pump lane and physical protection in the RMAN lane.
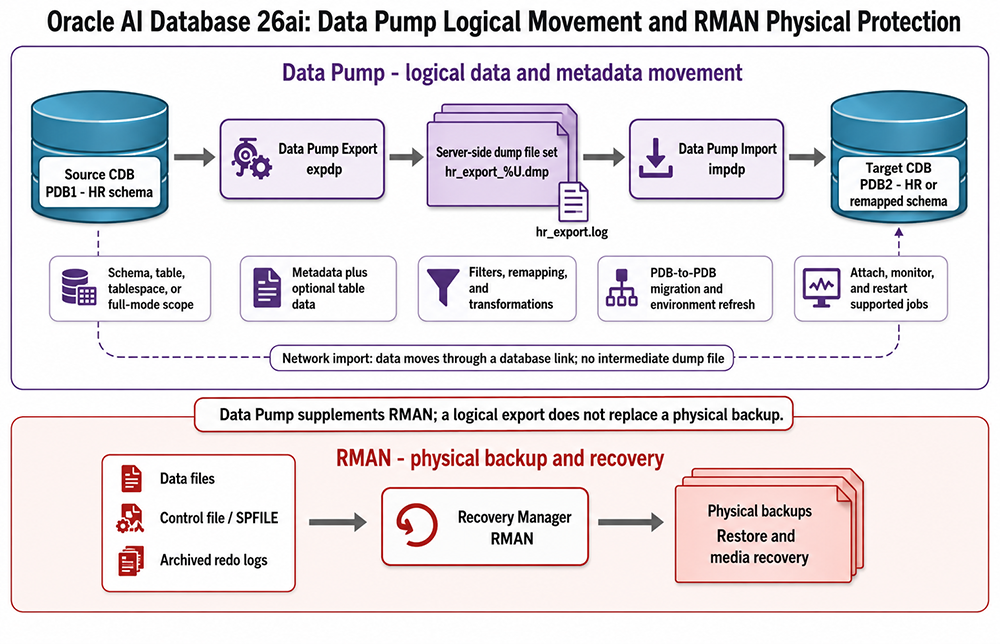
| Requirement | Data Pump | RMAN |
|---|---|---|
| Move a schema or selected tables | Designed for logical selection and movement | Not its primary object-copy workflow |
| Filter rows or object types | Uses logical filters such as QUERY, INCLUDE, and EXCLUDE |
Protects physical blocks rather than selecting logical rows |
| Remap a schema or tablespace | Supported through Import parameters | Does not perform Data Pump metadata remapping |
| Restore a lost data file or control file | Not supported | Physical restore and media-recovery function |
| Apply archived redo during recovery | Not supported | Part of the recovery workflow |
| Validate or recover corrupt blocks | Not a Data Pump function | RMAN validation and block media recovery |
Export/import can incidentally reorganize an object when Import creates it anew, but "eliminating disk fragmentation" is not a sound Data Pump objective. Likewise, importing a table is selective logical object handling, not a data-file restore. A dump file cannot substitute for a recoverable chain of physical backups and redo.
How a Data Pump Job Runs
expdp and impdp are clients; they are not the processes that perform all of the work. They pass job definitions to the database by
using the DBMS_DATAPUMP application programming interface. Data Pump uses DBMS_METADATA when it extracts, transforms, and re-creates
object metadata.
For each job, a server-side Data Pump control process coordinates the operation and assigns work to worker processes. A control job table in the job
owner's schema records information needed to track objects and progress. It also supports restart behavior when a job is stopped or interrupted under
supported conditions. The job owner therefore needs the required CREATE TABLE privilege and enough quota for the control table.
Because the database owns the job, the client can detach while work continues and later attach to the named job. Interactive commands can display status, change certain settings, or stop and restart a supported job. Killing a job instead discards the control table and prevents restart.
Data Pump normally reads and writes dump, log, and SQL files on the system named by the database connect string. An Oracle directory object associates a database name with a server-side path. It does not create the operating-system directory and does not grant operating-system permissions. Both layers must be prepared correctly.
CREATE DIRECTORY dpump_dir1 AS '/u01/app/oracle/dpump';

GRANT READ, WRITE ON DIRECTORY dpump_dir1 TO hr;
The path is illustrative. A DBA must create and secure the directory in the operating system, create the directory object in the correct container, and grant only the access needed by the job account. Dump files can contain sensitive rows, metadata, and grants, so their storage, encryption, retention, transfer, and deletion need the same governance applied to other production-data copies.
A Schema Export and Import
Assume that the operating-system directory exists, the database directory object has been created in PDB1, and the HR owner has
the required directory access. The schema owner can start an export without embedding a password in the operating-system command:
expdp hr@pdb1 DIRECTORY=dpump_dir1 DUMPFILE=hr_export_%U.dmp LOGFILE=hr_export.log SCHEMAS=HRThe connect identifier selects the source PDB service. DIRECTORY names the database directory object, not a client path. DUMPFILE
names the dump file set, and LOGFILE records the job results. The %U substitution variable lets Data Pump allocate numbered dump files
when the job configuration needs more than one file.
After the dump file set is transferred or otherwise made available to a prepared target server, a suitable target account can start Import:
impdp hr@pdb2 DIRECTORY=dpump_dir1 DUMPFILE=hr_export_%U.dmp LOGFILE=hr_import.log SCHEMAS=HRThe example assumes that the target account, directory, schema, tablespaces, and privileges have been prepared for the intended result. When the source
owner and target owner differ, a suitably authorized import can use REMAP_SCHEMA. Moving objects outside an account's own schema can require the
powerful DATAPUMP_EXP_FULL_DATABASE or DATAPUMP_IMP_FULL_DATABASE role. These roles should not be granted merely to avoid designing a
least-privilege workflow, and Data Pump jobs should not be run as SYS.
For repeatable operations, use a parameter file and invoke the client with PARFILE. This reduces quoting errors, makes the job definition
reviewable, and keeps credentials out of reusable command text. Protect parameter files because they expose operational details.
Data Pump in the Multitenant Architecture
Oracle AI Database 26ai uses the multitenant architecture, so the service in the Data Pump connect string is part of the job design. Connect Export to the PDB that owns the source objects and Import to the PDB that will own the target objects. Directory objects, local users, privileges, and available metadata are resolved in that container.
Data Pump does not perform one operation across an entire CDB. Connecting to the CDB root or seed produces a warning because Data Pump operations are not
typically needed there. A full-mode operation connected to PDB1 applies to the supported contents of PDB1; it does not silently
include PDB2 and every other pluggable database.
Data Pump can migrate all or part of a non-CDB into a PDB and move data between PDBs. Migration planning must still cover releases, the
VERSION parameter, character sets, time-zone files, encryption, installed options, transported-file endian format, and object restrictions.
Appropriate Data Pump Use Cases
A useful way to choose Data Pump is to identify the logical boundary of the requirement. Common examples include:
- Schema migration: move an application owner and its supported objects between databases or PDBs.
- Selective table copy: move named tables, partitions, or a filtered set of rows without copying every application object.
- Development and test refresh: create a controlled copy while remapping owners or tablespaces and excluding unnecessary objects.
- Metadata baseline: preserve supported object definitions with
CONTENT=METADATA_ONLYbefore a deployment or environment build. - DDL review: use Import with
SQLFILEto inspect the statements represented by a dump file before execution. - Transportable movement: use Data Pump for metadata while moving eligible data files separately, avoiding a row-by-row unload and load.
- Release migration: move compatible logical content after validating release, feature, character-set, and time-zone requirements.
Oracle AI Database 26ai also documents facilities for loading and unloading vector data. This is current datatype support—not a claim that Data Pump uses artificial intelligence to tune or repair jobs—and its restrictions must be reviewed.
Network Import and Transportable Operations
A network import can move data from a source database through a database link directly into the target. Because no intermediate dump file is involved, the approach can reduce file staging for an appropriate migration. The job still has compatibility, privilege, supported-link, object, and performance restrictions, and the database link must be secured as part of the design.
impdp app_admin@pdb2 NETWORK_LINK=pdb1_link SCHEMAS=HR REMAP_SCHEMA=HR:HR_STAGE LOGFILE=hr_network_import.logThis illustrative command assumes that app_admin is appropriately authorized, the fixed-user database link is supported and securely defined,
and the target schema has been prepared. Network Import normally reads the source and loads the target without a dump file. By contrast, a network Export
reads a remote source but writes its dump files on the server identified by the Export connection.
For transportable operations, Data Pump exports structural metadata while eligible tablespace data files move separately. Full transportable operations also move non-transportable content conventionally. Address endian differences, read-only requirements, self-containment, encryption, and compatibility.
Access Methods and Performance
Data Pump selects an access method according to the requested operation and the structure of each object. Direct path is often the fastest row-movement method because it bypasses much of the SQL layer. When direct path is unavailable, Data Pump can use external tables. Conventional path is available for cases in which conflicting table attributes prevent the other methods.
Active triggers, referential constraints on an existing target, fine-grained access control, clustered tables, encrypted columns, BFILE
columns, evolved types, and row filters can influence the method. Export and Import do not necessarily use the same method for the same table. Therefore,
the old original-Export advice to add DIRECT=Y should not be presented as the normal Data Pump workflow.
The PARALLEL parameter can allow multiple worker processes to perform eligible work concurrently, and the degree can be adjusted during a job.
It is an Enterprise Edition capability, and a larger value does not guarantee shorter elapsed time. CPU capacity, I/O throughput, dump-file layout,
object size, serial metadata operations, encryption, and access-method restrictions may become the limiting factor. Measure representative jobs and
review their logs instead of treating PARALLEL=4 as a universal tuning rule.
Operational Checks Before Using a Dump File
A completed client process is not sufficient evidence that the intended logical copy is usable. Before depending on a dump file set, verify:
- The log and process exit code show that all required objects and rows were processed successfully.
- Every file in the dump set is present, protected, readable by the target, and retained for the required period.
- The target PDB has compatible options, character sets, time-zone files, tablespaces, users, quotas, and encryption support.
- Filters, remaps, transforms, and existing-object actions match the approved migration design.
- Imported objects, row counts, constraints, indexes, grants, and application behavior are validated after the job.
- The RMAN backup and recovery plan remains intact and has not been replaced by the logical export.
Do not move, delete, or alter files while a job is using them. Restart support does not protect the dump set; define job naming, ownership, space, retention, encryption, and cleanup before production execution.
Historical Boundary and Lesson Summary
Oracle Data Pump replaced the original Export and Import workflow. In Oracle AI Database 26ai, original Export (exp) is desupported for all
uses. Original Import (imp) remains only for reading dump files created by original Export. The dump formats are not interchangeable:
impdp does not read original Export dump files, and imp does not read Data Pump dump files.
The modern function of Export is to capture supported logical data and metadata at a chosen scope. The modern function of Import is to create, load, select, remap, or transform that logical content in a prepared target. The server-side job architecture, directory objects, PDB connection, privileges, compatibility checks, and validation plan are all part of a successful operation.
Use Data Pump for logical portability, selective object handling, migration, and controlled environment refreshes. Use RMAN for physical backups, incremental block protection, data-file and control-file restoration, archived-redo handling, validation, and media recovery. When both are required, treat them as complementary layers with different recovery promises.
The next lesson applies these boundaries to more specific Export and Import operations.