| Lesson 1 | Entities & Attributes |
| Objective | Introduce entities, attributes, and identifiers in ER modeling and how they emerge from business objects. |
Entities and Attributes in Database Design
An entity type is a category of things a database needs to describe, such as Employee, Product, or Appointment. An attribute is a property of that category, such as an employee's name or an appointment's start time. An identifier is an attribute, or combination of attributes, that distinguishes each individual occurrence.
For example, Employee is an entity type; FirstName and LastName are attributes; and Alex and Morgan are values for one employee. EmployeeID identifies that employee even when another person has the same name. Understanding these distinctions is the starting point for building an entity-relationship model that represents the business accurately.
This lesson introduces the vocabulary and decisions used throughout the module. Begin with the information the organization needs to keep, rather than choosing SQL column types or drawing a table for every noun you encounter.
Read the Employee Entity Diagram
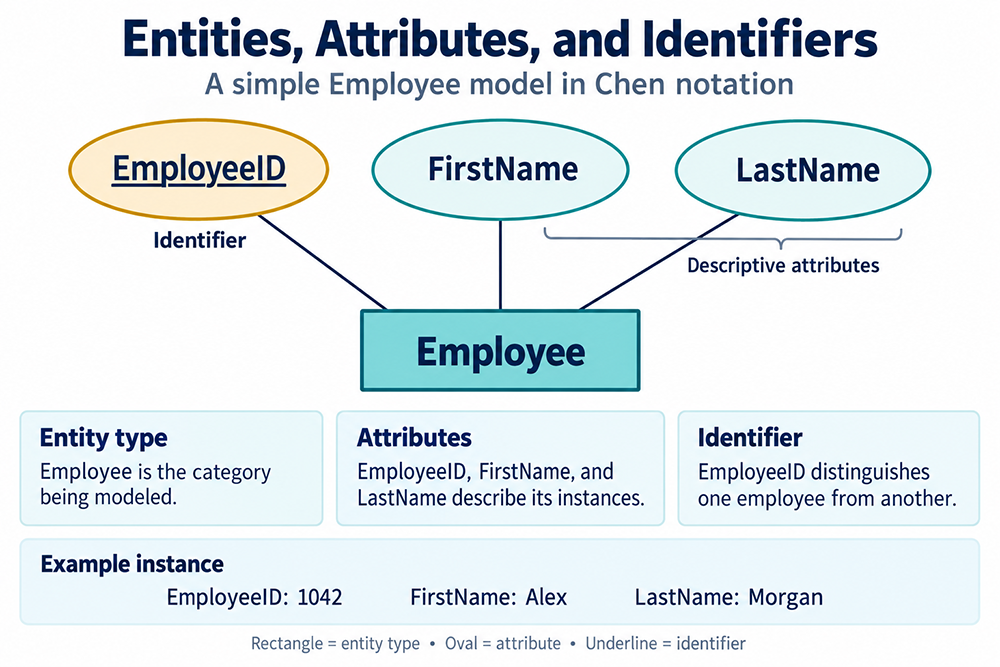
The diagram uses Chen notation. A rectangle represents an entity type, an oval represents an attribute, and an underlined attribute name marks an identifier. The connecting lines attach the attributes to Employee. They do not represent relationships between different entity types.
EmployeeID is still an attribute, although it has an identifying role. FirstName and LastName are descriptive attributes. All three belong to the definition of Employee; the values 1042, Alex, and Morgan belong to a particular employee instance.
This is a deliberately small model. It does not say that a real employee database needs only three attributes. It also does not show departments, employment history, relationships, or participation rules. Those decisions require additional requirements. Other notation styles, including Crow's Foot, commonly list attributes inside an entity box instead of separate ovals. Read the notation's legend before interpreting its symbols.
Entity Type, Instance, Attribute, and Value
The word entity is often used informally for both a category and a particular thing. During design discussions, use the more precise terms entity type and entity instance when the distinction matters.
| Term | Meaning | Example |
|---|---|---|
| Entity type | The category being modeled | Employee |
| Entity instance | One occurrence of that category | The employee identified by 1042 |
| Attribute | A defined property of the category | FirstName |
| Attribute value | The value of a property for an instance | Alex |
| Identifier | Attribute or attributes that distinguish instances | EmployeeID |
Suppose a second employee is also named Alex Morgan. The two people have equal values for FirstName and LastName, but they are different instances. Assigning them different employee identifiers lets the organization associate each person's records with the correct individual.
Changing an attribute value does not normally create a new instance. If employee 1042 changes their last name, the employee remains the same person in this model. Conversely, changing an identifier merely to match a name change can break the continuity the identifier was meant to preserve.
A useful test is to ask whether you are describing a definition or an occurrence. “Every employee has an EmployeeID” describes the model. “This employee's EmployeeID is 1042” describes data that conforms to it. Later lessons examine entity instances and the values stored for them in more detail.
From Business Objects to a Conceptual Model
A business object is something the organization recognizes and needs to discuss or track. It can be tangible, such as a vehicle, or intangible, such as a booking, agreement, or inspection. Database modeling turns that business vocabulary into explicit definitions of the information to retain.
Consider this requirement: “We need to list employees by department and keep their current work contact details.” Employee and Department are possible entity types. Employee name is a possible attribute. The assignment of an employee to a department is a possible relationship. Work contact details need further investigation because an employee might have several phone numbers or addresses.
Nouns are useful clues, but they are not automatic instructions to create entities. A report, screen, button, or calculation mentioned in a requirements interview may be part of the application without being a separate persistent business concept. Ask what facts must remain available after the screen closes and why the business needs them.
Define the scope of each candidate before adding attributes. Does Employee mean a person currently on payroll, anyone ever employed, or an individual employment engagement? If someone leaves and returns, does the system retain the same person record and create another employment record? Different answers lead to different models. Record the decision rather than letting an ambiguous name hide it.
The previous module's requirements analysis supplies these business questions. Modeling makes their answers specific enough to review with domain experts. A tidy diagram is useful only if its categories and rules describe the intended business.
Separate Conceptual, Logical, and Physical Design
Conceptual design describes the business meaning: the entity types, important attributes, relationships, and rules. An Employee concept can be discussed without deciding whether its identifier will use an integer, a character code, or another representation.
Logical relational design expresses the model as relations, commonly implemented as tables, with columns, candidate keys, and foreign keys. It also addresses how facts are separated so that they can be maintained consistently. In the simple Employee example, one entity type maps naturally to an Employee table, and its attributes map to columns.
Physical design selects implementation details for the chosen database system, including concrete data types, indexes, storage arrangements, and performance decisions. Some decisions overlap in practical projects, and teams use these labels somewhat differently. The useful distinction is between deciding what the information means and deciding how a particular DBMS will store and access it.
An ER diagram can describe different levels of detail, so the presence of a diagram does not by itself make a design conceptual. Nor does every conceptual entity require exactly one physical table. History, subtypes, and other requirements can change the mapping. Lesson 2 explains how entities and attributes map to relational tables.
Choose an Identifier That Matches the Business Scope
An identifier must distinguish every instance within the scope being modeled, not merely the small set currently visible in a sample spreadsheet. FirstName and LastName are poor employee identifiers because different people can share them and names can change.
Test a proposed identifier with three questions:
- Is it unique by rule? Obtain an explicit business guarantee or arrange for the system to assign unique values. Observing no duplicates today is not a guarantee.
- Is it available for every instance? A mandatory identifier cannot depend on a fact that is missing when the instance is created.
- Will it remain stable? Prefer identifiers that do not change when ordinary descriptive facts change, and establish rules about reuse.
A candidate key is a minimal set of attributes that uniquely identifies an instance. Minimal means that no attribute can be removed while preserving uniqueness; it does not mean “the shortest text.” If EmployeeID alone is sufficient, adding LastName does not produce a minimal candidate key.
A natural identifier has meaning in the business. A surrogate identifier is introduced primarily to identify a record. Neither label establishes quality by itself. An employee number may be a suitable business identifier if its allocation rules are reliable; a generated internal ID may be useful when external identifiers change or differ between systems.
A surrogate ID also does not prevent duplicate records for the same real-world person. The system still needs rules for identifying existing employees and handling duplicates. During relational implementation, one candidate key is selected as the primary key. SQL primary keys enforce uniqueness and non-null values; other candidate-key rules need appropriate constraints too. See the PostgreSQL primary-key documentation for one implementation, and the later lesson on rules for entity identifiers.
Define Attributes by Meaning, Domain, and Optionality
An attribute name should communicate one understandable fact. A vague field called Date leaves readers wondering whether it means hire date, birth date, or record creation date. Prefer a specific name and add a short definition where ambiguity remains.
For each attribute, record its meaning, allowed values, and whether a value is required. For example, a HireDate definition should specify what event it records. In an organization that rehires people, a single date might mean the latest hiring date rather than the first. If both facts matter, define them separately or model employment history explicitly.
An attribute domain is the set of permitted values. A SQL data type supplies part of the implementation, but does not express every business rule. A numeric type can represent many values that would be invalid for a particular quantity. A date type can represent dates unrelated to the event being recorded. Document the business restriction as well as the representation.
Optionality is another business decision. A missing middle name might be legitimate; a missing identifier is not acceptable for a primary key. Do not substitute a fake value such as “Unknown” or an arbitrary date simply to avoid thinking about absence. Decide whether the application needs to distinguish unknown, not applicable, and not yet provided, then design for those meanings.
Names in the diagram are simplified teaching examples, not a universal template for personal names. Real systems may need to support different naming conventions and display preferences. Similarly, address components depend on the countries served. The correct attribute structure follows the requirements, not the convenience of one sample record. The module's attribute domains and data types lesson develops these decisions.
Recognize Composite, Derived, and Multivalued Facts
A composite attribute can be described through meaningful components. An address may have a city and postal code, for example. Separate components when the system needs to search, validate, or maintain them independently. Do not split a value into pieces with no purpose, and do not assume that the same components apply everywhere.
A derived attribute can be calculated from other facts. Age depends on BirthDate and a reference date. Storing a current Age value without maintaining it allows it to become stale. Calculating age when needed is often appropriate; retaining an age recorded at a specific event is a different requirement and should be named accordingly.
A multivalued attribute permits several values for one instance. If an employee can have any number of contact phone numbers, fields called Phone1, Phone2, and Phone3 impose an arbitrary limit. A comma-separated list makes individual numbers harder to validate, reference, and update in an ordinary relational design.
A common solution is a related collection of employee phone records, each containing an employee reference and one number, with any needed type or validity information. This lets the design represent another number by adding another related record. Distinct fixed roles, such as separate emergency and work contacts, still require clear business definitions.
Some database products support collection types and specialized indexing, so “lists can never be indexed” is too broad. The introductory relational question is how each independently managed fact should be represented and constrained. Continue with recognizing multivalued attributes and resolving them into related entities for the fuller treatment.
Decide Whether a Fact Needs Its Own Entity
There is no rule that a particular word must always be an entity or always an attribute. Department could initially look like an employee label. If the organization tracks department identifiers, names, managers, or budgets independently, Department has its own facts and is a strong candidate for an entity type.
Ask whether the concept has its own identity, whether several other instances refer to it, and whether its facts change independently. Repeating a department's full details for every employee would make a single department change require many updates. Representing the department separately gives those facts a clear home.
Relationships can also require their own facts. If employees move between departments and the organization needs assignment history, a current Department attribute alone is insufficient. An assignment may need start and end dates. This is why understanding the required history matters before settling on a diagram.
A Practical First-Pass Modeling Checklist
- Write the business questions the database must answer.
- Identify the categories of things those questions concern.
- Define exactly what one instance of each category represents.
- List its attributes and give each an unambiguous meaning.
- Propose identifiers and test uniqueness, availability, and stability.
- Record allowed values, optional facts, repeated values, and history needs.
- Review example instances and difficult cases with a domain expert.
Include counterexamples in the review: two people with identical names, a person with no phone number, an employee with four numbers, or a department that has been renamed. These cases reveal assumptions that a diagram containing only ideal sample data can conceal.
Check Your Understanding
Is Alex an attribute? In this example, no. FirstName is the attribute; Alex is a value. Is EmployeeID separate from the attributes? No. It is an attribute with an identifying role. Does changing LastName create a new employee? Normally not: the identifier maintains continuity for the same instance.
Does the diagram define an Employee table already? It describes an entity type and selected attributes. A relational table is a subsequent implementation of that model. Can a sample with unique names prove that names are a key? No. A key requires a rule that continues to hold as valid new instances are added.
What You Will Learn in This Module
The following lessons build from this vocabulary to practical design decisions. You will explain how entities map to tables, distinguish instances from their stored values, choose identifiers, define domains, resolve multivalued attributes, and apply entity and attribute constraints that protect consistency.
Keep the Employee example in mind: Employee names the category, employee 1042 is one instance, FirstName names a property, and Alex supplies its value. Those distinctions let you discuss the business model clearly before translating it into database structures.
Next, study entities and attributes in a conceptual model to follow the mapping from business concepts to relational tables.