| Lesson 3 | Entity Identifiers |
| Objective | Explain the purpose of entity identifiers and how they support relationships and integrity. |
Entity Identifiers: Connecting Customer Instances and Data Values
An entity identifier is an attribute, or a combination of attributes, that uniquely distinguishes one entity instance from another. Its purpose is to let the database refer to the correct instance when storing, retrieving, changing, and relating data. A customer's name describes the customer; a dependable CustomerID identifies which customer record is intended.
In a relational design, a selected identifier becomes a primary key. Related tables can store that key as a foreign key, linking their records to the customer. This lesson follows three customer instances from their attribute values into a table, then shows why keys matter when an order refers to a customer.
The distinction builds on entities and attributes in a conceptual model: an entity type defines a category, while each instance supplies its own values. The identifier connects those values to one specific occurrence.
Three Customers, One Entity Type
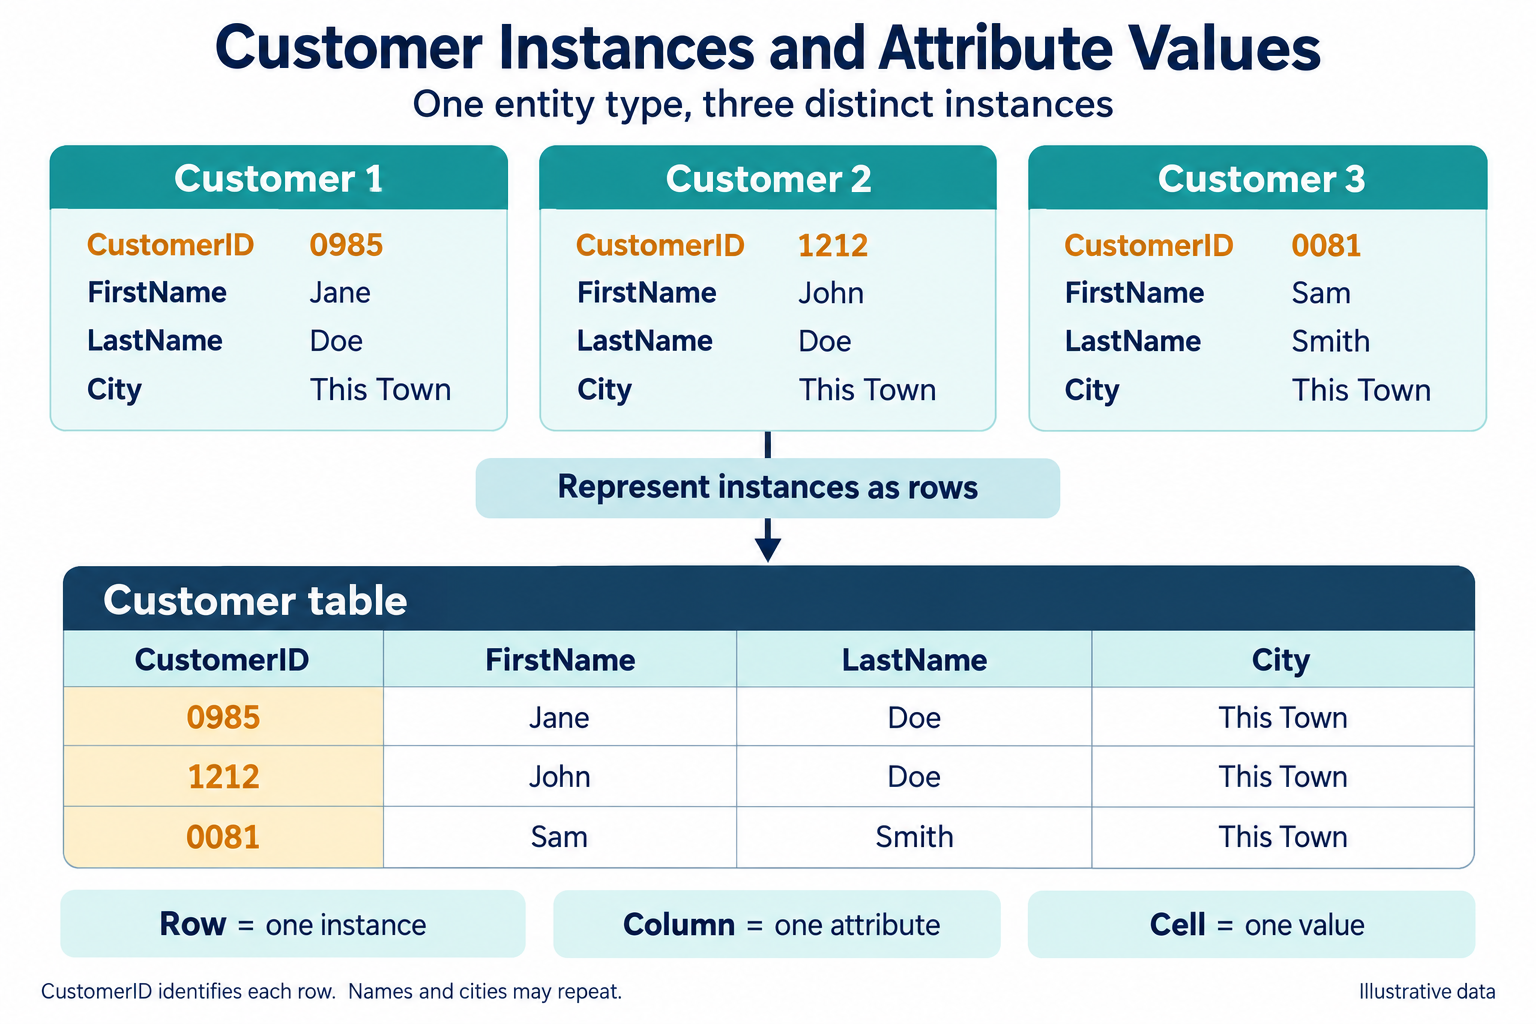
The cards and table show the same information in two forms. Each card groups the facts about one customer. The table places the corresponding instances in rows, using a common set of columns. The sample values are repeated below so they remain available as ordinary text.
| CustomerID | FirstName | LastName | City |
|---|---|---|---|
| 0985 | Jane | Doe | This Town |
| 1212 | John | Doe | This Town |
| 0081 | Sam | Smith | This Town |
Customer is the entity type. Jane Doe, identified here by 0985, is one instance. LastName is an attribute, and Doe is its value for two different instances. Repeated descriptive values do not make those instances identical.
CustomerID is also an attribute. Its identifying role adds a rule: within this Customer table, each identifier must distinguish one row. The figure labels the cards Customer 1, Customer 2, and Customer 3 only to organize the illustration; those labels are not additional database keys.
The common City value makes another distinction visible. Knowing that a customer lives in This Town does not identify one customer. Even FirstName and LastName together should not be assumed unique. Two people can have the same full name, and a person's name can change.
Attribute Definitions Stay Separate from Their Values
The table definition describes which facts can be recorded and which rules apply. The rows contain the current data. Adding another customer normally adds another row; it does not require a new FirstName column or a separate table named after that person.
An attribute value has meaning through both its column and its instance. The text Doe is not enough to locate a customer record. The combination “LastName for CustomerID 0985” identifies a particular fact in this example. This is the practical reason to organize values under stable identifiers.
A row represents an instance at the level of detail chosen for the table. Here it represents a customer record. In an order table, a row represents an order, even though it may refer to a customer. Decide that level of detail before choosing a key; otherwise a key can be unique while identifying the wrong kind of occurrence.
The example uses a simplified current city, not a complete address model. If the application needs several addresses or address history, those facts need a more detailed design. The identifier provides a reference point for the related facts; it does not eliminate the need to model them.
Why Identifiers Matter
Identifiers make several everyday operations unambiguous:
- Retrieve a record: Find customer 0985 without guessing which Jane Doe is intended.
- Change a fact: Update that customer's city while preserving the customer's identity.
- Connect related records: Associate an order with the customer who placed it.
- Check integrity: Reject duplicate key values and references to nonexistent customers.
These functions are related but different. A primary key identifies a row. A foreign key constrains a reference between tables. Other rules govern whether a name is required, which values are permitted, and whether a person already has an account. No single key declaration answers every data-quality question.
Keys can also support efficient access through indexes, but a sound identifier does not guarantee that every query is fast. Performance depends on the query, indexes, data volume, and execution plan. Identity is a modeling requirement; access speed is a related implementation concern.
From Entity Identifiers to Database Keys
A candidate key is a minimal set of attributes that uniquely identifies an instance. Minimal means no attribute can be removed while retaining that property. If CustomerID alone identifies each row, CustomerID plus LastName contains an unnecessary attribute and is not a minimal candidate key.
A primary key is the candidate key selected as the table's principal identifier. An alternate key is another candidate key that was not selected as primary. A table has one primary-key constraint, although that key can contain several columns.
Do not conclude that every non-primary-key attribute is incapable of identifying a record. For example, a separately assigned customer number might be an alternate identifier if the business guarantees that it is unique and required. Name and City have no such guarantee in this example.
A foreign key is a column or group of columns whose values refer to an allowed key in another table, or sometimes the same table. The referenced key is often the primary key, but it can be another suitable unique key. The precise eligibility rules belong to the chosen DBMS.
For the SQL example below, PostgreSQL 18 enforces primary keys as unique and non-null and permits foreign keys to reference suitable unique columns. Its constraint documentation describes these requirements. The conceptual distinction remains useful across relational database systems.
Preserve the Meaning of Customer Codes
The diagram includes 0985 and 0081. For this example, these are character codes whose leading zeros belong to the representation. Store and compare them as text. Treating 0081 as an integer would produce the numeric value 81 and would lose that formatting unless a separate display rule restored it.
A system could instead use an internal numeric key and format a customer-facing number separately. Either approach can be valid, but the distinction should be deliberate. Do not let a spreadsheet import decide whether zeros are meaningful.
A natural identifier comes from the business domain; a surrogate identifier is introduced primarily to identify records. The name CustomerID alone does not establish which kind it is. Document how the values are assigned, their scope of uniqueness, and whether they can change or be reused.
Stability is especially valuable when other records refer to a key. If a customer moves, changing City should not require changing every order's customer reference. Avoid embedding mutable facts, such as the current city, into an identifier without a compelling requirement. The next lesson covers rules for choosing identifiers in greater depth.
SQL Example: Store and Retrieve Customer Values
The following is an illustrative PostgreSQL 18 example for a practice schema. The four-character limit matches this small teaching dataset; a real customer-code domain needs its own requirements. The name fields are required here as a simplifying assumption, not a universal model for personal names.
CREATE TABLE Customer (
    CustomerID VARCHAR(4) PRIMARY KEY,
    FirstName  VARCHAR(100) NOT NULL,
    LastName   VARCHAR(100) NOT NULL,
    City       VARCHAR(100)
);

INSERT INTO Customer (CustomerID, FirstName, LastName, City)
VALUES
    ('0985', 'Jane', 'Doe',   'This Town'),
    ('1212', 'John', 'Doe',   'This Town'),
    ('0081', 'Sam',  'Smith', 'This Town');

SELECT CustomerID, FirstName, LastName, City
FROM Customer
WHERE CustomerID = '0985';
The expected result is Jane Doe's row with CustomerID 0985 and City This Town. This is an expected result derived from the sample statements, not a captured database execution. The primary key permits at most one matching row for that identifier.
By contrast, a filter on LastName = 'Doe' matches both Jane and John. That is a valid search when the user wants all customers with that surname; it is unsuitable when an operation must identify exactly one customer.
SELECT CustomerID, FirstName, LastName
FROM Customer
WHERE LastName = 'Doe'
ORDER BY CustomerID;
The expected rows are 0985 Jane Doe and 1212 John Doe, in that order. The diagram's visual arrangement is not an implicit database ordering rule. Use ORDER BY for a required result order; do not depend on insertion order or the presence of a primary key.
To change one customer's current city, the identifier supplies a precise condition:
UPDATE Customer
SET City = 'New Town'
WHERE CustomerID = '0985';
This changes a descriptive value for the existing customer. It does not create another instance. The diagram continues to show the original sample state before this illustrative update.
Use Foreign Keys to Connect Orders to Customers
Suppose an order belongs to one customer and a customer can place many orders. Store the customer reference on each order. The order also needs its own identifier because CustomerID alone cannot distinguish multiple orders placed by the same person.
CREATE TABLE CustomerOrder (
    OrderID    INTEGER PRIMARY KEY,
    CustomerID VARCHAR(4) NOT NULL,
    OrderDate  DATE NOT NULL,
    CONSTRAINT fk_order_customer
        FOREIGN KEY (CustomerID)
        REFERENCES Customer (CustomerID)
);

INSERT INTO CustomerOrder (OrderID, CustomerID, OrderDate)
VALUES (5001, '0985', DATE '2026-11-01');

SELECT o.OrderID, c.CustomerID, c.FirstName, c.LastName
FROM CustomerOrder AS o
JOIN Customer AS c ON c.CustomerID = o.CustomerID
WHERE o.OrderID = 5001;
For the sample data, the join associates order 5001 with Jane Doe. The repeated CustomerID in the order is a reference, not a second customer instance. More orders may use that same customer reference while retaining distinct OrderID values.
Here, NOT NULL requires every order to carry a customer reference, and the foreign key requires a matching customer. Neither rule requires every customer to have an order. That is a separate participation requirement.
Deletion and key-change behavior also need an explicit policy. Should a customer with retained orders be deletable? Should the account be deactivated instead? The sample declares no cascading deletion action. Do not introduce cascading deletion merely to make a relationship diagram easier to implement; decide what must happen to the related business records.
A Unique Key Does Not Guarantee a Unique Real-World Customer
A second row with CustomerID 0985 would violate the primary key. However, a row with a new ID and the same name and city could satisfy all the declared constraints. The database cannot infer from those few attributes whether the row is a duplicate account or a different person.
Customer registration therefore needs a policy for recognizing existing accounts and reviewing possible duplicates. Avoid replacing that policy with a UNIQUE constraint on names: such a constraint would reject legitimate people who happen to share a name. Similarly, an email address is not automatically a reliable identifier when accounts may share addresses or addresses may change.
When duplicate records are merged, related references need to be reassigned deliberately. Simply deleting one customer row can conflict with retained orders or lose context. The modeling lesson is that record identity and real-world identity are connected, but they are not the same problem.
Associative Entities Also Need Identifiers
An associative entity records an association between other entity types. Enrollment, for example, can connect a Student with a CourseOffering and record facts such as enrollment date. In a conventional relational design, this supports a many-to-many relationship through a separate table.
If each student can enroll at most once in each offering, the pair StudentID and OfferingID can be a composite identifier. Alternatively, EnrollmentID can be the primary key while a uniqueness rule on the pair protects the same business restriction. Adding a surrogate key should not silently remove that restriction.
The rule depends on what an enrollment instance means. A student may take the same course in different terms, so StudentID plus CourseID could be too restrictive. If multiple enrollment attempts within one offering are allowed, even the student-offering pair may be insufficient. Define the occurrence first, then choose the attributes that distinguish it.
Associative describes the entity's role. Composite describes a key containing multiple attributes. The terms are not interchangeable, and an associative entity does not lack identity simply because it represents a relationship.
Review Your Identifier Design
- State what one row represents before selecting its identifier.
- Check uniqueness against business rules, not just today's sample rows.
- Keep identifiers available and prefer stable values for referenced records.
- Preserve meaningful formatting, including leading zeros in codes.
- Distinguish primary keys, alternate identifiers, and foreign-key references.
- Document duplicate-customer handling separately from duplicate-key prevention.
- Define relationship optionality and deletion behavior deliberately.
Attribute domains and other entity and attribute constraints complement these rules. They help express which values and combinations are permitted, while identifiers make it possible to locate and reference the intended instances.
Check Your Understanding
Why can Doe appear twice? LastName is descriptive and is not constrained to identify one customer. Why keep 0081 as text here? The code's leading zeros are part of this example's representation. Does changing City change the customer identifier? No; it updates a fact about the same instance.
Can two orders refer to 0985? Yes. Their OrderID values distinguish the orders, while their customer references can repeat. Does a generated CustomerID eliminate duplicate accounts? No. It establishes distinct record identifiers, while duplicate-person detection still needs business rules.
Continue to rules for creating entity identifiers to evaluate possible keys systematically. Keep the distinction from this lesson in mind: attributes describe instances, and identifiers let you refer to the correct instance as its descriptive values change.