| Lesson 10 | Problems with poorly represented many-to-many relationships |
| Objective | Describe redundancy, update, insertion and deletion anomalies in a poorly designed many-to-many implementation. |
Many-to-Many Relationship Problems: Redundancy and Anomalies
A many-to-many (M:N) relationship is a valid business association: a student can take several classes, and a class can have several students. Problems arise when its storage design repeats parent facts, limits associations to a few fixed columns, or makes references difficult to validate.
In Lesson 9, the Student/Class example separated student facts, class facts, and enrollment pairs. This lesson examines what can go wrong before that separation, and how to distinguish storage problems from the harmless repetition seen in a joined report.
Understand What the Flawed Table Stores
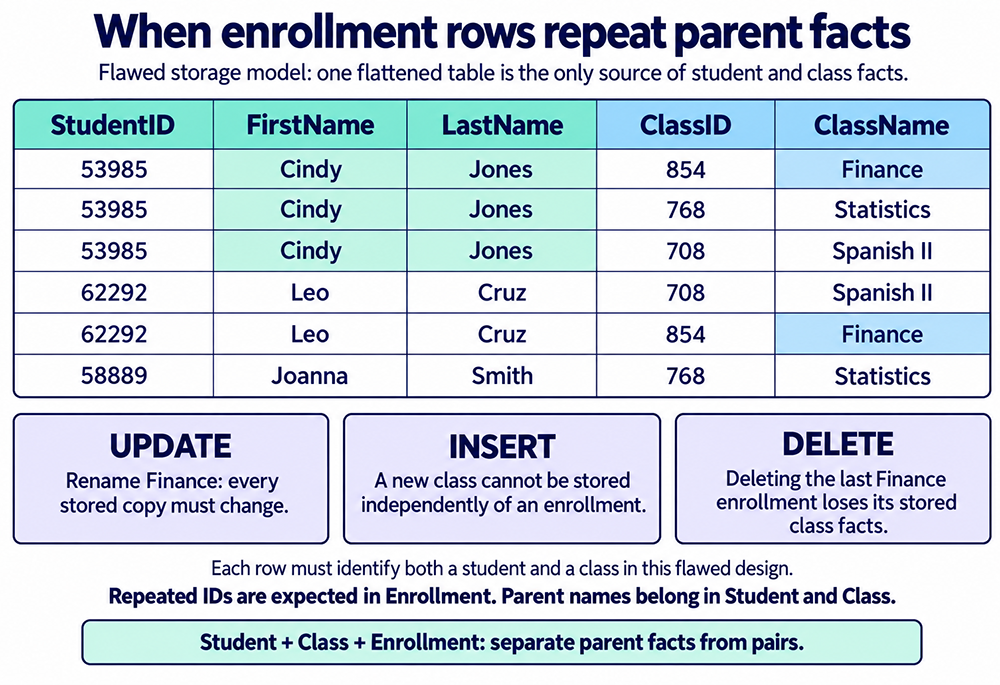
Suppose StudentClassFlat is the only stored source of student and class information, and every row must identify a complete enrollment pair. StudentID and ClassID together identify a row, while student names and class names are repeated within those rows. The diagram uses the same six enrollments as Lesson 9.
| StudentID | FirstName | LastName | ClassID | ClassName |
|---|---|---|---|---|
| 53985 | Cindy | Jones | 854 | Finance |
| 53985 | Cindy | Jones | 768 | Statistics |
| 53985 | Cindy | Jones | 708 | Spanish II |
| 62292 | Leo | Cruz | 708 | Spanish II |
| 62292 | Leo | Cruz | 854 | Finance |
| 58889 | Joanna | Smith | 768 | Statistics |
Three Anomalies Caused by Repeated Parent Facts
- Update anomaly: Renaming Finance requires changing both rows for ClassID 854. Changing only Cindy's row leaves Leo's row with the old name. Correcting Cindy's surname would likewise require changing three rows.
- Insertion anomaly: A new class with no enrolled students has no complete enrollment row in which to store its facts. A new student with no classes has the same problem. Inventing an enrollment or relaxing the row's meaning merely to hold parent facts undermines the design.
- Deletion anomaly: Removing both Finance enrollments would remove the only stored name for class 854. Deleting Joanna's only enrollment would also remove the only stored facts about Joanna. Deleting an association should not unintentionally erase a parent entity.
These insertion and deletion consequences follow from the stated single-table design. If separate parent tables already hold the facts, deleting an enrollment does not by itself erase those parent records. Repeated copied names may still become stale, but the risk is different.
Repeated Identifiers Are Different from Repeated Facts
StudentID 53985 should appear in three Enrollment rows because Cindy takes three classes. ClassID 854 should appear twice because Finance has two students. Those repeated references represent distinct associations.
The avoidable redundancy is storing Cindy's name in each enrollment and storing Finance's name for each student. StudentID determines student names; ClassID determines the class name. Those facts belong to their parent tables[1].
All six enrollment pairs in the example are distinct. A repeated identifier is not a duplicate enrollment, and a table of scalar columns does not violate first normal form merely because some values recur. Analyze dependencies and row identity rather than treating every repeated value as an error.
Detect Conflicting Copies of a Class Name
Assume the flattened example has been loaded into StudentClassFlat. This query identifies a ClassID with more than one distinct stored name:
SELECT ClassID, COUNT(DISTINCT ClassName) AS NameVariants
FROM StudentClassFlat
GROUP BY ClassID
HAVING COUNT(DISTINCT ClassName) > 1;
It returns no rows for the original sample. If one Finance row is renamed to Financial Studies while another remains Finance, it flags ClassID 854. This is a diagnostic for inconsistent copies, not a rule for deciding which name is correct. Resolve the authoritative value before changing data.
Relational Database Design
Other Symptoms to Investigate
- A single class reference per student: One ClassID in Student cannot represent several enrollments in that same row.
- Repeating fields: ClassID1, ClassID2 and ClassID3 impose an arbitrary maximum and complicate adding further associations.
- Identifier lists: A comma-separated list requires parsing and makes ordinary foreign-key validation of each member difficult. An association table gives each reference its own column value and row.
- Misplaced association attributes: One Grade in Student cannot identify grades for Cindy's three classes. Grade must identify the relevant student/class association, and possibly an attempt if the requirements allow several.
- Unclear keys: Without a defined association key, duplicate enrollments may be accepted or valid repeated attempts may be rejected accidentally.
These are questions to investigate. The business rule establishes M:N by permitting several related instances in both directions. Association attributes and repeated data can also occur in other patterns.
Separate Parent Facts from Enrollment Facts
| Table | One row represents | Facts stored there |
|---|---|---|
| Student | One student | StudentID, FirstName, LastName |
| Class | One specific class offering | ClassID, ClassName, ClassDept |
| Enrollment | One student enrolled in one class, under the example rule | StudentID and ClassID references, EnrolledOn, Grade |
A composite primary key on (StudentID, ClassID) prevents repeated pairs when only one enrollment per pair is permitted. Foreign keys validate both references. Non-null references require every existing Enrollment to identify its student and class; they do not require every parent to have an enrollment.
After separation, renaming Finance updates one Class row. A new class can be created before students enroll. Removing the last Finance enrollment leaves the Class row intact unless a separate operation explicitly deletes it.
If multiple attempts, terms, or sections are required, define the class offering and enrollment identity accordingly. Adding a surrogate EnrollmentID does not automatically establish the correct business uniqueness rule.
The next lesson demonstrates the conversion into two parent-to-junction 1:N relationships.
Choose Integrity and Performance Rules Deliberately
- Preserve parent records appropriately. Decide whether enrollments must be retained when a student leaves or a class is retired. Cascading deletion is a policy choice, not an automatic benefit of a junction table.
- Validate references and row identity. Use foreign keys and the required uniqueness constraints. Do not substitute assumptions in application code for an enforced rule.
- Check parent participation separately. A class-size minimum or a student's required enrollment count needs additional enforcement at the appropriate transaction or state transition.
- Measure index needs. A composite primary key may support access by its leading column. Review existing indexes and query plans before adding indexes for reverse lookups or joins.
Normalization reduces repeated parent facts and the associated update work; it does not guarantee faster queries. Performance depends on workload, indexes, data volume, and the DBMS. Arrays and JSON have legitimate uses, but choose a representation that supports the integrity and querying requirements of the association.
A Joined Report Can Repeat Names Safely
A query joining Student, Enrollment and Class may produce a result that looks like the original flattened table. That is expected: each report row describes an enrollment, so the same parent name can appear more than once. The report reads the name from one authoritative parent row rather than storing several independent copies.
Intentional denormalization also requires a plan for keeping copied values consistent. Historical snapshots, such as a product's agreed price on an order line, may represent a different fact from the product's current price and should not be overwritten merely because the values differ.
Check Your Understanding
- Is Cindy's StudentID appearing three times in Enrollment an anomaly? No. The three rows record different class associations.
- Why can renaming Finance be an update anomaly in StudentClassFlat? Its name is stored in multiple rows, and an incomplete update can leave conflicting copies.
- Does deleting an enrollment always delete its class? No. The loss occurs in the flawed design when that enrollment row holds the last stored class facts; a separate Class table prevents that dependency.
- Does an M:N association inherently make queries slow? No. Its implementation and the actual workload determine performance.
A sound M:N design gives the association its own rows while keeping parent facts in their parent tables. Identify the row's meaning, define its key, and validate each reference. This preserves the association without making a student's or class's existence depend on one particular enrollment.
[1] Redundant data: Repeated representations of a fact. Repeated references and repeated report values can be appropriate; independently maintained copies of the same parent fact create the update risks illustrated here.