| Lesson 5 | Achieving 1NF |
| Objective | Decompose a table to achieve 1NF. |
Achieving First Normal Form: Separate Repeating Values into Rows
To achieve first normal form in the conventional relational model taught here, represent each independently meaningful value in an appropriate attribute, remove repeating groups, and identify each row reliably. When one book has several authors, store their entries as related rows rather than adding Author1, Author2, and more numbered columns.
The important part of decomposition is preserving information. Keep every book, every author entry, and the association between them. Do not remove a value simply because it resembles another value or occurs more than once.
1. Identify the repeating group
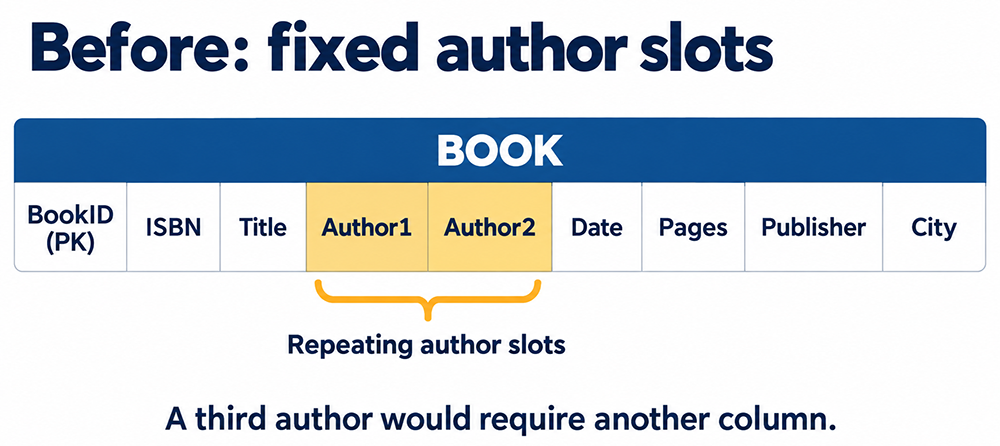
Ask what one row represents. Here it represents one book edition, identified by BookID. The numbered author columns impose an arbitrary limit on its contributors. They also make searching for an author require checking every author column.
As discussed in Lesson 4, the course treats these interchangeable slots as a repeating-group design. Distinct roles such as StartDate and EndDate are different: sharing a data type does not make columns a repeating group. Atomicity means one value in the model's domain, not something that is physically impossible to subdivide.
2. Move author entries into a related table
The following minimal decomposition retains the legacy two-table teaching model:
Book   (BookID, ISBN, Title, Date, Pages, Publisher, City)
Author (AuthorID, BookID, AuthorName)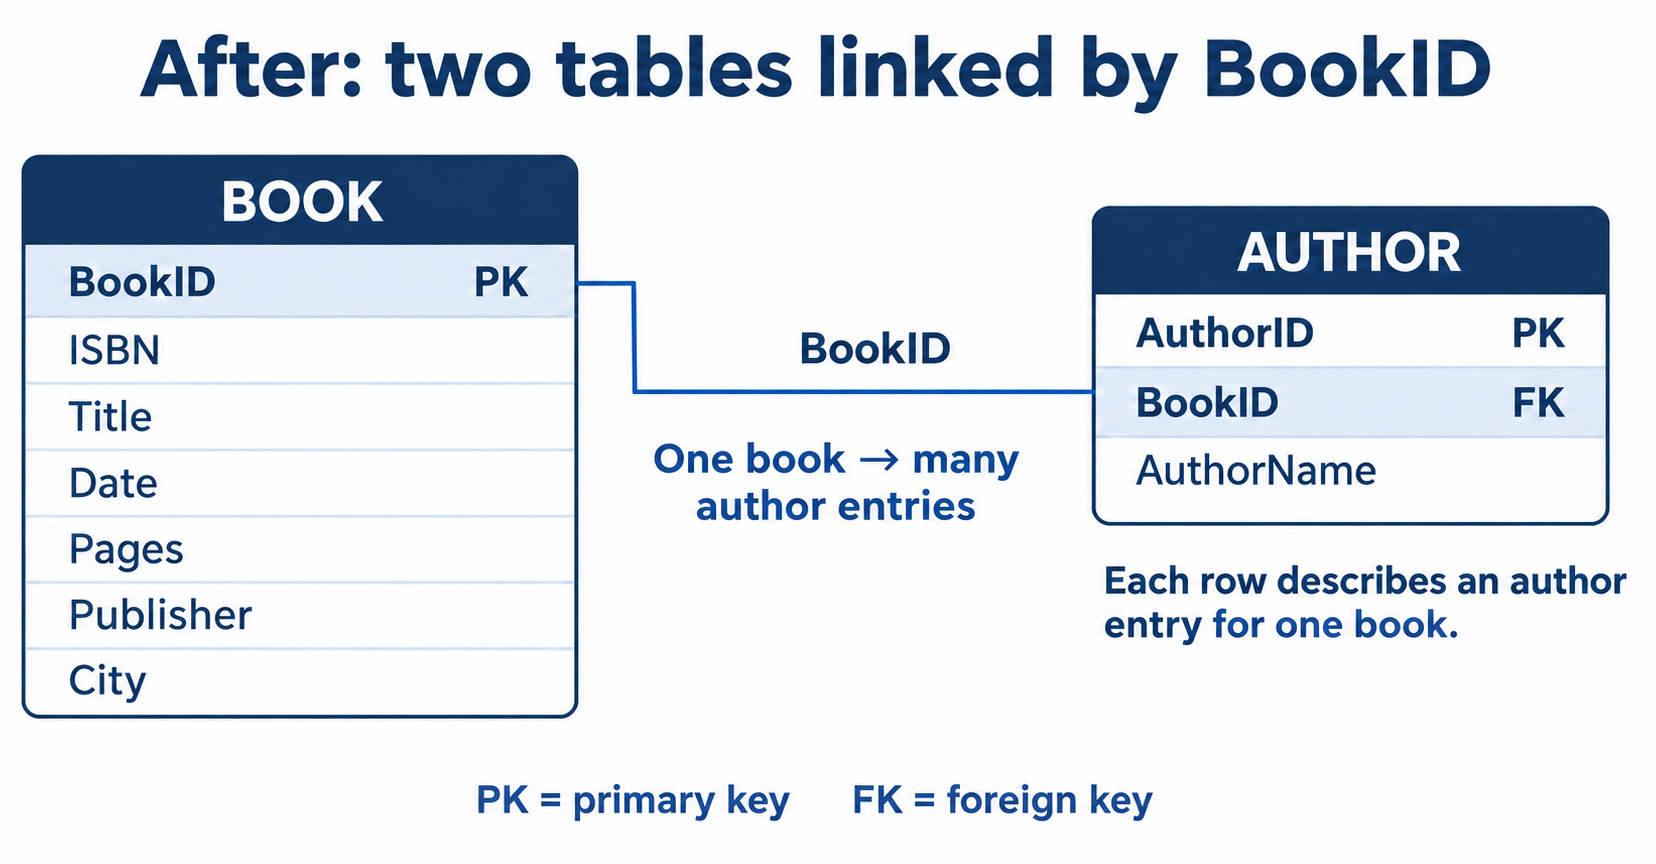
That distinction matters. If the same person contributes to two books, this simple AUTHOR table contains two entries with different AuthorIDs. The model removes fixed author slots, but it does not yet maintain one independent record for each person.
For example, a book with BookID 1 can have entries (101, 1, Alex Morgan) and (102, 1, Sam Patel). Adding a third contributor requires another row, not another column. A book with no recorded authors remains in BOOK without a child entry.
3. Choose keys and preserve ordering when required
BookID is the primary key of BOOK. AuthorID is the primary key of the minimal AUTHOR table; BookID is its foreign key. AuthorName should not be the identifier because different people may share a name.
If Author1 and Author2 encode meaningful credit order, the three-column child schema alone does not preserve that information. Add AuthorOrder and carry the original positions into it during migration. A useful set of constraints is:
-- Additional column in the minimal AUTHOR table:
AuthorOrder INTEGER NOT NULL

-- Additional constraints:
UNIQUE (BookID, AuthorOrder)
CHECK (AuthorOrder > 0)
This is schema notation, not a complete executable CREATE TABLE statement. The unique constraint prevents two entries occupying the same position for one book; it does not require consecutive positions. SQL result rows have no guaranteed order without an ORDER BY clause.
4. Migrate values without losing associations
- Copy each book's non-author attributes into BOOK once, retaining BookID.
- For each populated Author1 slot, create an AUTHOR entry referencing that BookID. Assign AuthorOrder 1 if order matters.
- Repeat for Author2 and any additional slots, preserving their positions.
- Investigate blank strings, conflicting values, and duplicate entries before loading them. Do not merge people solely because their names match.
- Verify that every child entry references an existing book and every meaningful source entry has been transferred.
Use a LEFT JOIN when reviewing the complete book list so books without author entries are retained:
SELECT b.BookID, b.Title, a.AuthorName, a.AuthorOrder
FROM Book AS b
LEFT JOIN Author AS a ON a.BookID = b.BookID
ORDER BY b.BookID, a.AuthorOrder;
This query assumes the AuthorOrder extension above. Compare the returned associations with the source rather than comparing only table row counts: decomposition intentionally changes how many rows each table contains.
When the catalog needs independent author identities
A real catalog commonly needs to connect the same person to multiple books. Use a separate Author entity and a BookAuthor association table for that many-to-many relationship:
Book       (BookID, ISBN, Title, Date, Pages, Publisher, City)
Author     (AuthorID, AuthorName)
BookAuthor (BookID, AuthorID, AuthorOrder)

Primary keys:
Book: BookID
Author: AuthorID
BookAuthor: (BookID, AuthorID)

Foreign keys:
BookAuthor.BookID → Book.BookID
BookAuthor.AuthorID → Author.AuthorID

Additional rules:
UNIQUE (BookID, AuthorOrder)
AuthorOrder must be positive and not null
In this design AuthorID identifies the person, while BookAuthor records their contribution to a book. This assumes one authorship association per book-person pair. If different contribution roles must be recorded separately, refine the association's attributes and key to match those rules.
The preceding lesson provides executable SQL for this three-table design. The two-table illustration here teaches the first decomposition; the three-table alternative addresses the broader identity requirement.
Keys, indexes, and what 1NF does not prove
Keys and foreign keys express identity, uniqueness, and references. Indexes are access structures; database systems commonly use indexes to enforce primary-key and unique constraints. An index on a column containing a list does not turn that list into separately constrained relationships.
Reaching 1NF does not prove that the book's remaining attributes are free from partial or transitive dependencies. Publisher and publication-city semantics, for example, need further business analysis. Nor does a new surrogate key remove existing dependencies.
Check your result
- Each row has a defined meaning and an appropriate key.
- Contributor entries occupy rows rather than numbered slots or embedded lists.
- Book references are valid and enforced with foreign keys.
- Meaningful ordering and books without contributors are preserved.
- Reconstructed associations agree with the source data.
Achieving First Normal Form — Exercise
Practice the decomposition in the Achieving First Normal Form exercise. Then continue to the limitations of first normal form to see why further dependency checks are necessary.