| Lesson 4 | Eliminating transitive dependencies |
| Objective | Decompose a table to remove repeated facts caused by a transitive dependency and verify the result. |
How to Eliminate Transitive Dependencies
To remove a transitive dependency that violates 3NF, move the dependent facts into a relation keyed by their determinant, retain the determinant as a reference, and verify that a join reconstructs the original information. The goal is to stop repeating facts in the wrong table while preserving their meaning and relationships.
Lesson 3 explained how to recognize the dependency chain. Here we apply the procedure to the Item and Category example from Lesson 2, then check the design rather than stopping at a drawing.
Start with Explicit Business Rules
Our catalog stores current item and category facts, with these assumptions:
ItemNois the only candidate key of the original Item table.- Each item belongs to exactly one category; a category can contain many items.
CategoryIDdetermines one current category name and manager. Neither the name nor the manager is assumed to be unique.- Title and Price describe an item. No additional dependencies are assumed among these attributes.
Item(ItemNo, Title, Price, CategoryID, CategoryName, CategoryManager)

ItemNo → Title, Price, CategoryID
CategoryID → CategoryName, CategoryManager
Four Steps to Remove the Repeated Facts
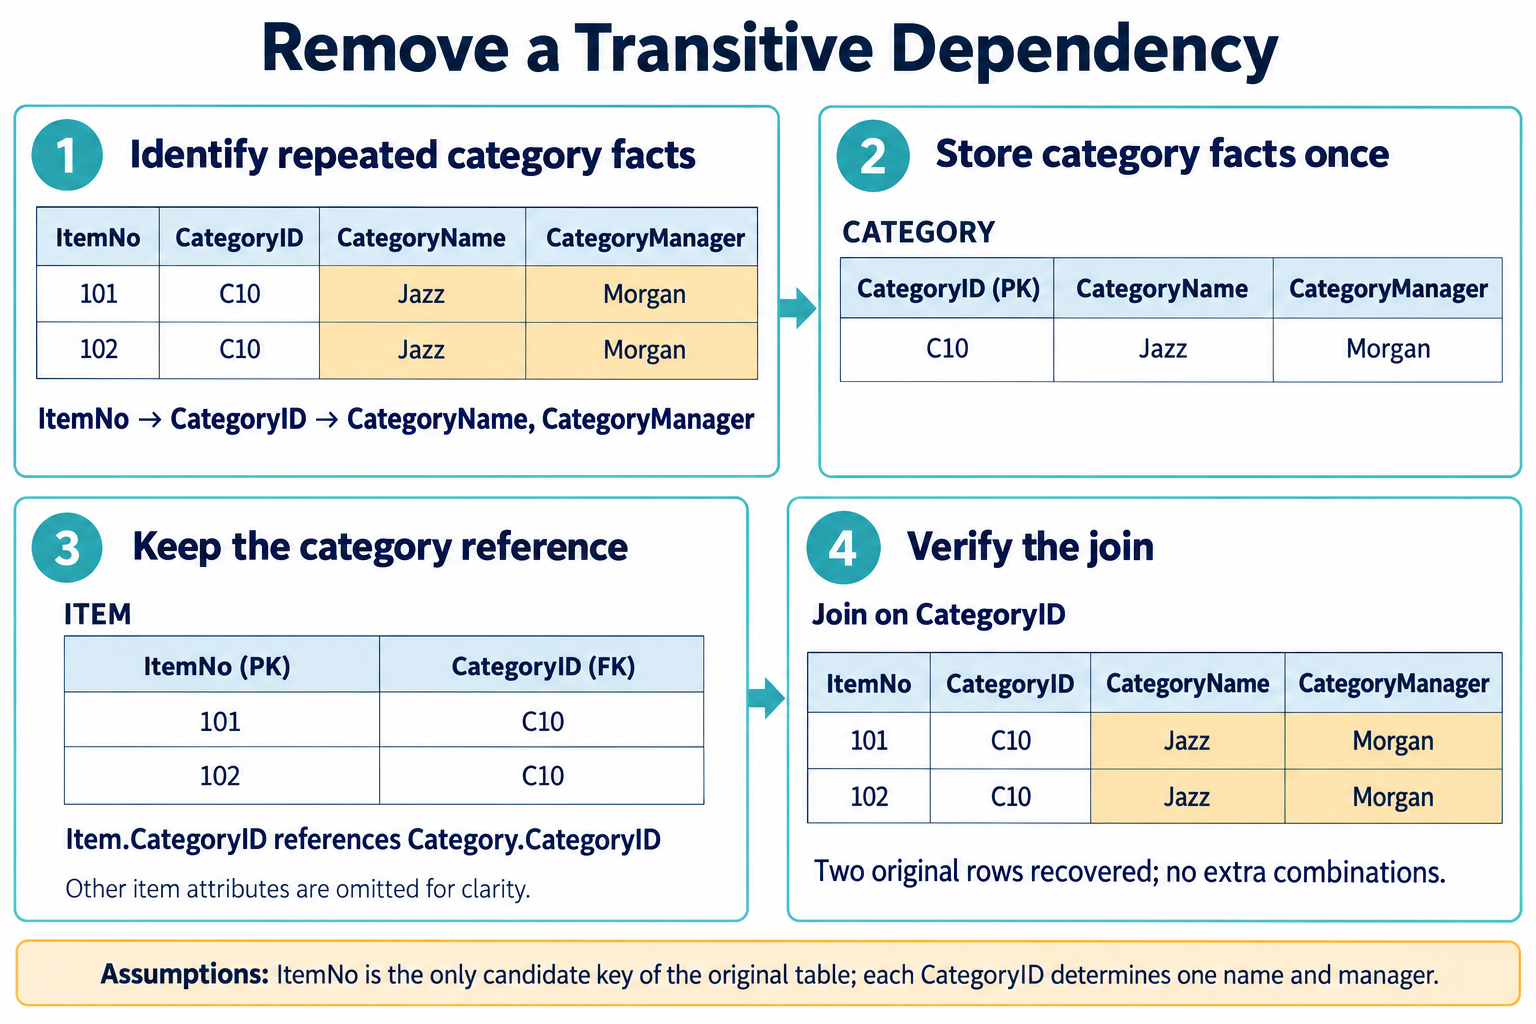
1. Identify the Dependency That Violates 3NF
Trace the chain ItemNo → CategoryID → CategoryManager; CategoryName follows the same pattern. CategoryID is not a superkey of Item because many items can share it. CategoryName and CategoryManager are non-prime attributes: neither belongs to a candidate key.
Thus, CategoryID → CategoryName, CategoryManager violates 3NF. For each nontrivial dependency, 3NF requires a superkey determinant or a prime dependent attribute. These dependencies meet neither condition.
Repeating the category manager in every item row makes a manager change a multirow update. It also prevents storing a category independently of its first item and risks losing its facts when its last item is deleted.
2. Create a Relation for the Category Facts
Place the determinant and its dependent attributes together:
Category(CategoryID PK, CategoryName, CategoryManager)CategoryID is now the primary key of Category. Store C10, Jazz, and Morgan once, regardless of how many items belong to C10. Do not add a unique constraint to CategoryName merely because it is descriptive: uniqueness must be a business rule.
When converting existing data, first check whether any CategoryID has conflicting names or managers. Resolve those conflicts before creating one category row per identifier. Selecting distinct combinations alone does not resolve contradictory category facts.
3. Retain the Foreign Key in Item
Remove CategoryName and CategoryManager from Item, while keeping its own facts and the category identifier:
Item(ItemNo PK, Title, Price, CategoryID FK)

Item.CategoryID references Category.CategoryID
This is schema notation, not executable SQL. Enforce the reference with a foreign-key constraint. Make Item.CategoryID NOT NULL to implement the stated rule that each item must have a category. CategoryID is not unique in Item: multiple items must be allowed to reference the same category.
Choose deletion behavior from the business rules. Blocking deletion of a category that still has items is often appropriate for this catalog; cascading deletion would also remove its items and requires an explicit business justification.
4. Verify the Decomposition
Recover the Original Information
The following illustrative SQL reconstructs the original columns:
SELECT i.ItemNo,
       i.Title,
       i.Price,
       i.CategoryID,
       c.CategoryName,
       c.CategoryManager
FROM Item AS i
JOIN Category AS c
  ON c.CategoryID = i.CategoryID;
This decomposition is lossless under the stated dependencies. The common attribute, CategoryID, determines all attributes of Category. Each original item therefore joins to exactly one category, recovering its category facts without generating additional combinations. The foreign key and NOT NULL constraint maintain a matching category for each item after the conversion.
Preserve the Functional Dependencies
The resulting Item table retains ItemNo → Title, Price, CategoryID. Category retains CategoryID → CategoryName, CategoryManager. The stated dependencies can be checked in their respective tables without joining them; this is dependency preservation.
Check the Operations That Previously Failed
- Update: Change the manager of C10 in one Category row; both items obtain the new manager through the join.
- Insert: Add category C20 before any item references it.
- Delete: Delete the last item in C10; the Category row remains.
- Reject an invalid reference: An item with a nonexistent CategoryID must fail the foreign-key check.
These checks target the anomalies caused by repeated category facts. They do not prove that every possible business rule is enforced or that every other relation in the database is normalized.
What Has Changed—and What Has Not?
Category facts now have one storage location per category. The business chain still exists: an item identifies a category, and that category identifies its manager. Normalization removes the problematic repetition inside Item; it does not eliminate useful relationships across tables.
Under the stated dependencies, both relations satisfy 3NF. Adding a new surrogate key to the original combined table would not achieve the same result because CategoryID would still determine repeated category facts. If additional dependencies or historical requirements emerge, reassess the design.
Review the Normal Forms
For a comparison of partial and transitive dependencies, see First, Second, and Third Normal Forms.
Summary
Identify a dependency that fails the 3NF test, place the determinant and its facts in a separate relation, retain the foreign key, and verify lossless reconstruction and dependency preservation. The next lesson brings these checks together to achieve third normal form.