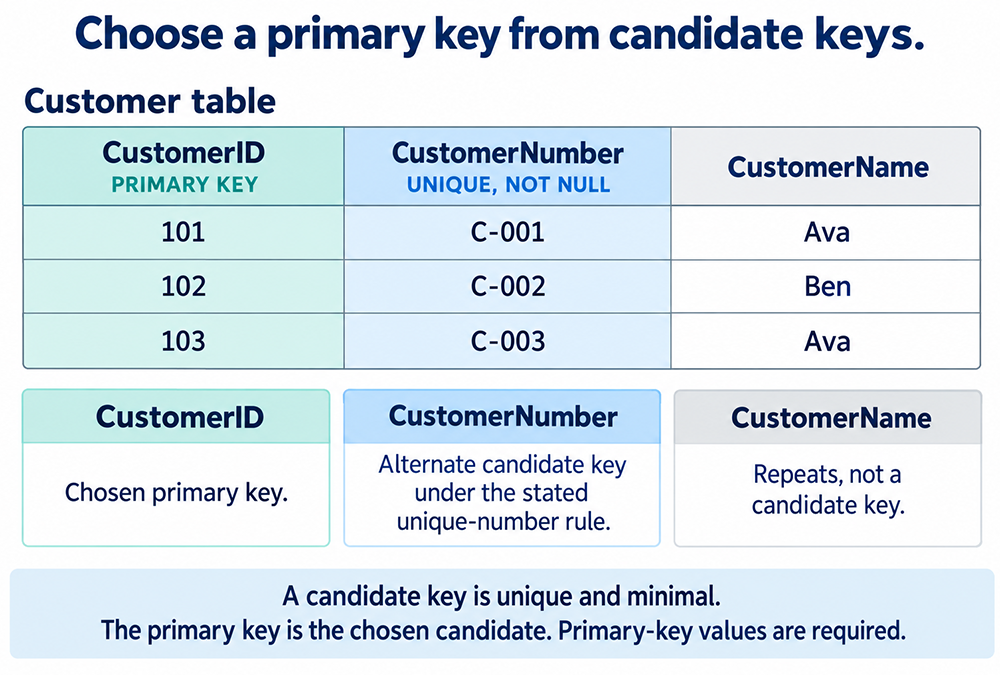
A primary key is the chosen column or combination of columns that uniquely identifies each row in a database table. Its values must be unique and its columns must not contain NULL. A table has at most one primary-key constraint, but that key can contain several columns.
For example, CustomerID can identify a customer even when two customers have the same name. An enforced primary-key constraint rejects a duplicate key; it does not choose an arbitrary matching row.
A foreign key has a different role: it references an eligible key in another table (or the same table). Many foreign-key values may repeat unless an additional uniqueness constraint prevents this.
Entity Identifier in an ERD vs. Primary Key in a Database Table
The entity identifier in an Entity Relationship Diagram and the primary key in a database table are closely related but serve different roles at different stages of the database development process.
Entity Identifier - Conceptual Level
The entity identifier is defined during the design phase of the DBLC, within the ERD. It represents
a unique attribute or combination of attributes that can distinguish each instance of an entity from
every other instance. The entity identifier is an abstract, design-level concept - it describes what
makes an entity instance unique without specifying how that uniqueness will be enforced in the
physical database.
For a Customer entity, CustomerID can be an identifier if the business rules make it unique. FirstName and LastName are not reliable identifiers: different people can share both. Diagram conventions vary, so provide a legend for underlining, PK labels, or other symbols.
Primary Key - Physical Level
The primary key is the physical implementation of the entity identifier when the database is
created. It is a concrete constraint defined in the database schema using SQL. Where the entity
identifier is a design decision, the primary key is an enforceable rule built into the table
structure.
A primary key in a database table has two defining requirements: uniqueness and non-nullability. Indexes are a separate implementation consideration:
Uniqueness - no two rows in the table can share the same primary key value.
Implementation note - DBMSs commonly use a unique index to enforce the key. A primary key does not promise sorted query results; use ORDER BY.
The transition from ERD to database implementation maps directly: CustomerID as the
entity identifier in the ERD becomes the PRIMARY KEY constraint on the
CustomerID column in the Customer table. The entity identifier describes the concept;
the primary key enforces it.
Separate mandatory constraints from design preferences:
Unique: no two rows have the same complete key.
Required: every key column has a non-NULL value.
Minimal as a candidate key: no unnecessary attribute is included.
Stable: prefer values that will not change. Changes may be blocked or require coordinated updates to references.
Suitable representation: choose a data type with adequate capacity and consider index and foreign-key storage costs.
Appropriate to the rule: a natural key, generated surrogate key, or composite key may fit. Sequential integers are common, but are not a requirement.
Characteristics of a Bad Primary Key
A person's name, address, or email can repeat or change. Sensitive identifiers also spread sensitive data into referencing tables. These properties often make such values poor choices for a widely referenced primary key.
A surrogate key avoids tying row identity to mutable descriptions, but it does not enforce business uniqueness by itself. If customer numbers must be unique, declare that rule separately even when CustomerID is the primary key.
Rules for Designating a Primary Key
Primary-key columns must be non-NULL. NULL is a marker for missing or unknown information, not zero or an empty string. Ordinary SQL equality does not treat NULL = NULL as true; use IS NULL to test for it. Do not explain the primary-key rule by claiming that NULL equals NULL.
NULL handling in a nullable UNIQUE constraint differs across DBMSs. When representing an alternate candidate key, explicitly declare both uniqueness and non-nullability.
SQL example: primary key and alternate key
CREATE TABLE Customer (
    CustomerID     INT NOT NULL PRIMARY KEY,
    CustomerNumber VARCHAR(20) NOT NULL UNIQUE,
    CustomerName   VARCHAR(100) NOT NULL
);

INSERT INTO Customer (CustomerID, CustomerNumber, CustomerName)
VALUES (101, 'C-001', 'Ava');
INSERT INTO Customer (CustomerID, CustomerNumber, CustomerName)
VALUES (102, 'C-002', 'Ben');
INSERT INTO Customer (CustomerID, CustomerNumber, CustomerName)
VALUES (103, 'C-003', 'Ava');
The repeated name Ava is allowed. Reusing CustomerID 101, inserting a NULL customer number, or reusing customer number C-001 is rejected by the respective constraint. IDs are supplied explicitly here; automatic generation syntax is DBMS-specific.
Candidate Keys
A candidate key is a minimal set of attributes that uniquely identifies every row under the business rules. Minimal means no proper subset is sufficient. Choose one candidate as the primary key; the others are alternate keys.
CustomerID and CustomerNumber are candidate keys under the stated rules. CustomerID is chosen as primary; the SQL enforces CustomerNumber with UNIQUE and NOT NULL. Names need not be unique.
Do not infer candidate keys solely from a small sample: a column that happens to contain distinct values today may repeat tomorrow. Establish the rule first, then enforce it.
Can a primary key contain more than one column?
Yes. A concatenated or composite primary key[1] uses a combination, for example PRIMARY KEY (StudentID, CourseID) when each student enrolls once per course offering. Neither component needs to be unique by itself.